Crusoe signs multi-year deal to power Perplexity's AI training and inference
Crusoe and Perplexity have announced a multi-year strategic partnership that integrates Perplexity’s full AI model lifecycle into the Crusoe Cloud infrastructure. Under the agreement, Perplexity will train its frontier models on dedicated NVIDIA GB300 NVL72 clusters and serve them in production using Crusoe’s Managed Inference service. This collaboration is designed to address the critical…
Key points
- Perplexity will train on dedicated NVIDIA GB300 NVL72 clusters and serve models via Crusoe Managed Inference.
- NVIDIA GB300 NVL72 offers 72 Blackwell Ultra GPUs, claiming 50x performance gains over Hopper-based platforms.
- Crusoe will adopt Perplexity Enterprise Pro and Max for its 1,800 employees as part of the multi-year deal.
The hardware backbone of this deal is the NVIDIA GB300 NVL72 platform, a liquid-cooled rack-scale system featuring 72 Blackwell Ultra GPUs and 36 Arm-based Grace CPUs. NVIDIA projects that this architecture delivers up to a 50x increase in AI factory output performance compared to previous Hopper-based platforms, driven by significant gains in user responsiveness and throughput per megawatt. For production serving, Crusoe utilizes its proprietary MemoryAlloy engine, which claims to achieve up to 9.9x faster time-to-first-token and 5x higher throughput than standard vLLM implementations.
In a reciprocal move, Crusoe will deploy Perplexity Enterprise Pro and Max for its own 1,800 employees, providing staff with advanced web search, multi-step research, and data analysis capabilities. Executives from both companies emphasized that the partnership ensures infrastructure scales alongside Perplexity’s growth, supporting the high-stakes environment of agentic AI where every millisecond of latency impacts millions of users.
Crusoe Signs Multi-Year Deal to Power Perplexity Training and Inference
Unite.AI · 15 September 2026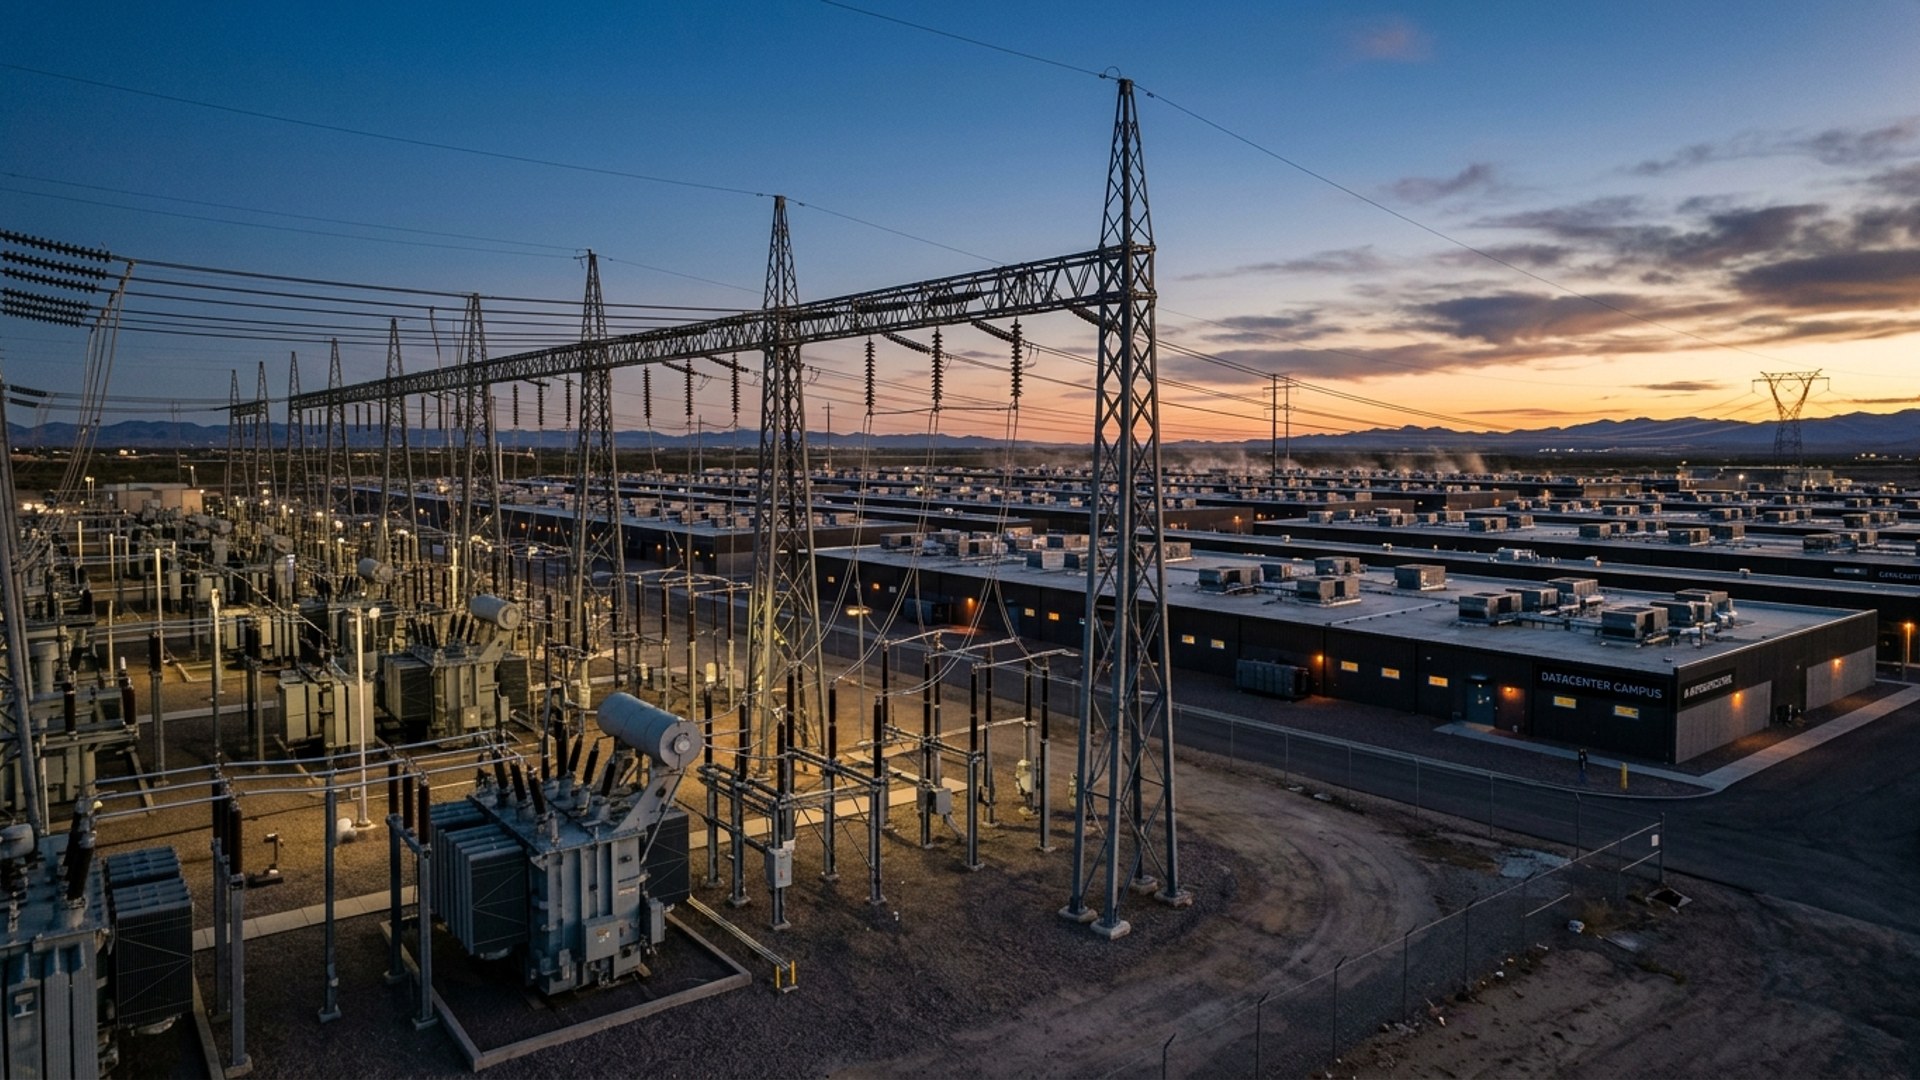
Crusoe on September 15, 2026, announced a multi-year partnership with Perplexity under which Perplexity will run its full model lifecycle on Crusoe Cloud, training frontier models on dedicated NVIDIA GB300 NVL72 clusters and serving them in production through Crusoe’s Managed Inference service.
The announcement, datelined San Francisco, also commits Crusoe to adopting Perplexity Enterprise Pro and Max for its 1,800 employees. According to the release, the deployment is meant to equip staff with web and internal knowledge search, multi-step research, data analysis, and access to frontier AI models.
The release characterizes Perplexity’s products as operating in real time for millions of users, an environment in which inference latency and throughput are the product rather than theoretical benchmarks. Crusoe said its Managed Inference service is built for production-grade inference powered by proprietary optimizations and engineered for performance and cost across popular models, and that Crusoe Cloud offers the operational depth and scale to match Perplexity’s growth.
Executive Statements
Crusoe co-founder and CEO Chase Lochmiller said the fastest-moving AI companies need infrastructure that keeps pace across the entire model lifecycle and scales with them as they grow. “Perplexity is building the future of how people find answers, and Crusoe is a key partner in making that possible, from the first electron to the last token,” Lochmiller said.
Perplexity co-founder and CEO Aravind Srinivas said that running AI at Perplexity’s scale means every millisecond of latency is felt by users. He described Crusoe as built around that constraint, calling it high-throughput, low-latency inference backed by next-generation hardware.
Dion Harris, senior director of HPC and AI Infrastructure Solutions at NVIDIA, said modern AI requires a unified computing architecture from research to deployment. Powered by NVIDIA GB300 NVL72 and NVIDIA InfiniBand, Harris said, Crusoe Cloud enables Perplexity to train, fine-tune, and serve frontier models in production with the speed and efficiency agentic AI demands.
The GB300 NVL72 Platform
The dedicated training clusters named in the agreement run on NVIDIA’s GB300 NVL72, which NVIDIA describes as a fully liquid-cooled, rack-scale system integrating 72 Blackwell Ultra GPUs and 36 Arm-based Grace CPUs. NVIDIA’s published specifications list 130 TB/s of NVLink bandwidth, 20 TB of GPU memory with up to 576 TB/s of bandwidth, 37 TB of fast memory, and 2,592 Arm Neoverse V2 CPU cores. Each GPU in the system receives 800 Gb/s of network connectivity through a ConnectX-8 SuperNIC IO module, working with either Quantum-X800 InfiniBand or Spectrum-X Ethernet networking platforms.
NVIDIA claims that AI factories built on the GB300 NVL72 deliver up to a 50x overall increase in AI factory output performance compared with Hopper-based platforms. The company attributes that figure to a stated 10x improvement in user responsiveness, measured in tokens per second per user, and a 5x improvement in throughput per megawatt relative to Hopper, and notes the numbers are projected performance subject to change.
Managed Inference Service and History
The production-serving element of the agreement runs on Crusoe Managed Inference, which the company made generally available on November 20, 2025, for production inference workloads on Crusoe Cloud. The service is powered by Crusoe’s proprietary inference engine built around MemoryAlloy, a cluster-wide key-value cache that eliminates duplicate prefills by allowing GPUs to fetch prefix caches from local and remote nodes. Crusoe states the engine delivers up to 9.9x faster time-to-first-token and 5x higher throughput, benchmarked against vLLM for the Llama-3.3-70B model in a four-node deployment.
Crusoe offers the service in three deployment options, according to its Managed Inference product page. Serverless Inference offers usage-based consumption of open models through a fully managed API, aimed at early-stage workloads, low-volume traffic, and rapid experimentation. Self-Serve Deployments, which the page says are now generally available, run models optimized for throughput or responsiveness, including models customized with Crusoe’s Serverless Fine-Tuning. Tailored Deployments pair customers with Crusoe’s team for a dedicated, benchmarked endpoint, an option the page directs at proprietary models.
Developers reach the service through Crusoe Intelligence Foundry, a hub where they can generate API keys, use managed endpoints tuned to each model, monitor performance metrics, and enable provisioned throughput for production-scale deployments. Crusoe’s model hub lists pre-configured open models from labs including DeepSeek, Google, Z.ai, OpenAI, Meta, Alibaba, and NVIDIA, with stated parameter counts and context lengths for each model.
This text was published by Unite.AI and written by Theo Nash, AI Infrastructure & Compute, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
2 sources- Perplexity AI Partners With Crusoe for Nvidia (NVDA) GB300 Chip Access in Major Cloud Agreement Press · blockonomi.com ·
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us.
More in Hardware & Compute
All →- Broadcom’s AI Chip Business Thrives, Making It an Attractive Buy · 1 src
- MediaTek launches 2nm Dimensity 9600 Pro with 61% lower multi-core power · 1 src
- Bell expands Saskatchewan AI data centre to 1.2 GW, province's largest private investment · 1 src
- Broadcom Anticipates Strong Sales Growth to Anthropic · 2 src
- Nvidia Launches RTX Pro 5500 with 84GB GDDR7 to Bridge Performance Gap · 4 src
Comments
via GitHub Discussions