OM-1: A Robot Policy Trained Exclusively on Human Demonstrations
Reward AI, a robotics startup known for its DexCap and HumanPlus projects, has unveiled OM-1. This general-purpose manipulation policy learns from human wearers equipped with a sensorized glove, capable of operating industrial arms and humanoid robots at normal speed. Key findings include the absence of teleoperation or on-robot data in training. The system's unique approach is termed 'One…
Key points
- OM-1 learns from human demonstrations using a sensorized glove with seven DOF
- No teleoperation or on-robot data used during training
- Capable of operating various robotic platforms including arms and legged robots
Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
MarkTechPost · 14 September 2026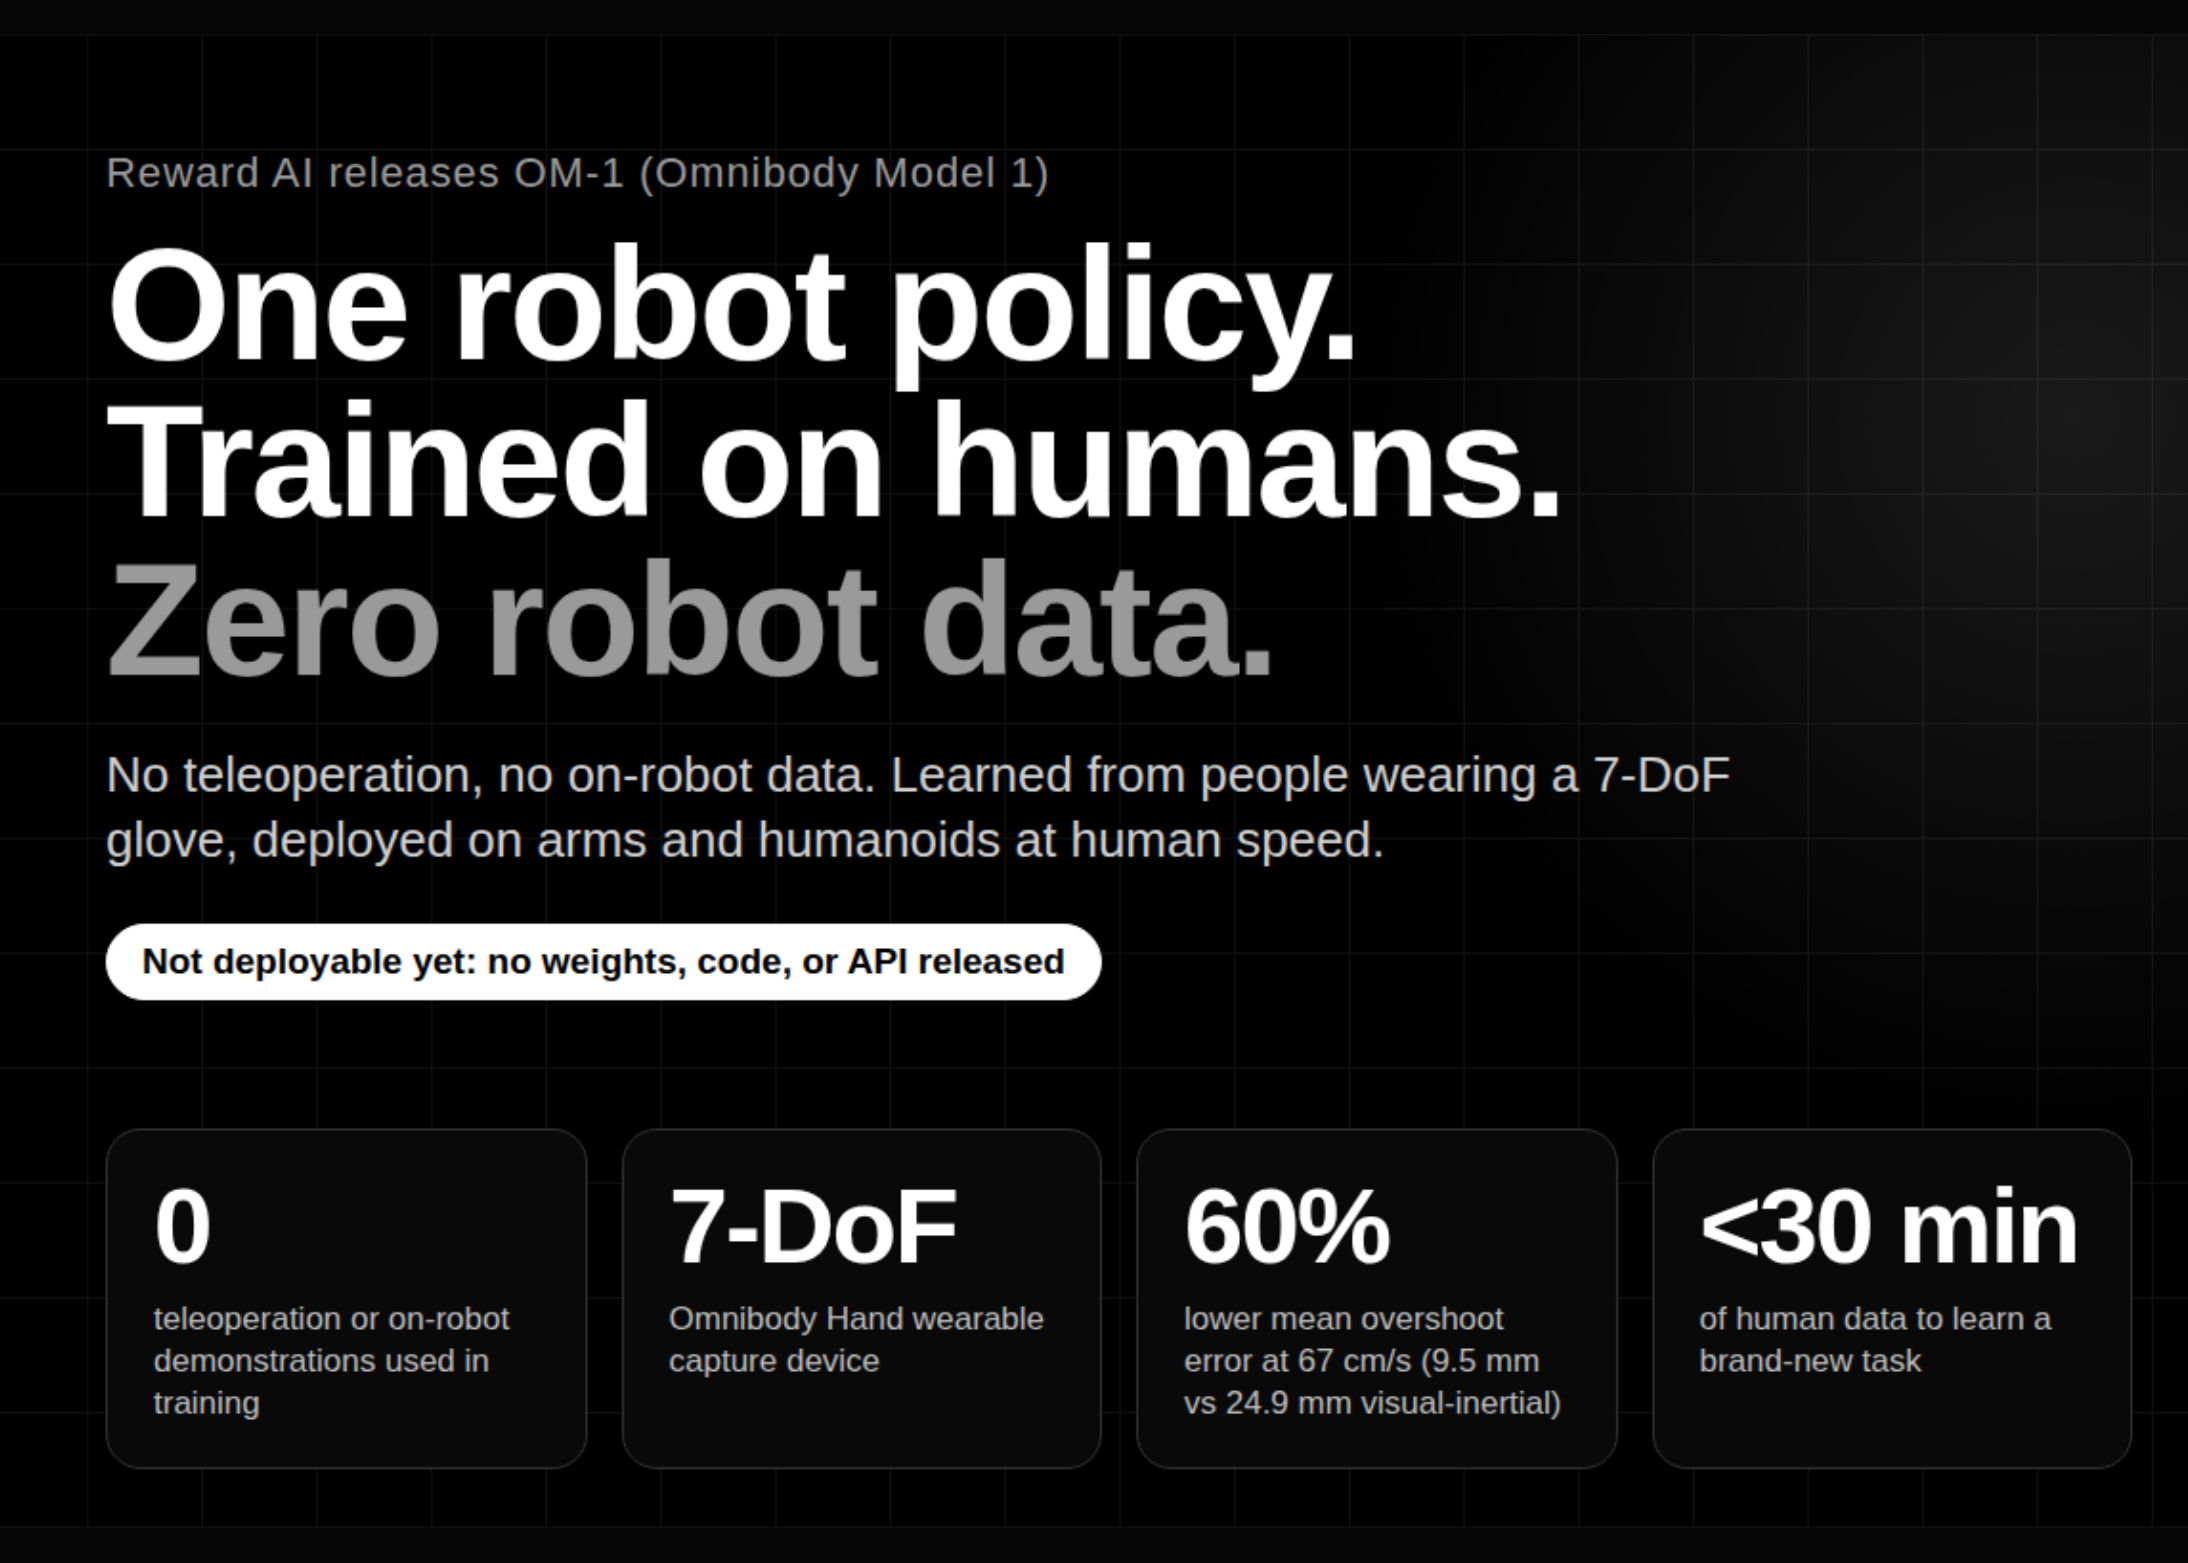
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Enterprise & Industry
All →- Cyara’s CEO outlines AI agent oversight as a workforce model · 1 src
- Arcana adds institutional portfolio data to Claude’s connectors · 1 src
- Anthropic brings Claude inference to India via Amazon Bedrock · 6 src
- Infor adds industry-specific AI agents to Velocity Suite, citing generic AI gaps · 1 src
- Tech Mahindra trains 12,500+ staff on Google’s Gemini Enterprise agents · 1 src
Comments
via GitHub Discussions