Google Research introduces ToolGrad for efficient AI tool-use dataset generation
Google Research has unveiled ToolGrad, a new framework designed to streamline the creation of datasets for training large language models in tool use. Unlike traditional methods that generate user queries first and then search for solutions via depth-first search, ToolGrad reverses this process by generating valid tool-use chains before creating the corresponding user prompts. This…
Key points
- ToolGrad generates tool-use datasets by creating solutions before queries, improving efficiency over traditional search methods.
- Fine-tuned Gemma-3 models using ToolGrad-500 data matched or surpassed proprietary LLMs on the BFCL benchmark.
- The framework achieves near 100% pass rates in data generation, enabling compact models to handle complex, long-horizon tasks.
The team evaluated this method using the ToolBench API database, which contains over 16,000 real-world APIs. They generated a small-scale dataset called ToolGrad-500 and used it to fine-tune Gemma-3 models ranging from 1B to 12B parameters. The resulting models, designated ToolGrad-1B, 4B, and 12B, were tested on the Berkeley Function Calling Leaderboard (BFCL). The results showed that these compact, fine-tuned models achieved near-perfect pass rates in data generation and outperformed their base versions. Notably, they matched or surpassed state-of-the-art proprietary models like Gemini, GPT, and Claude on out-of-distribution tasks involving unseen tools.
Presented at ACL 2026, this research addresses a key bottleneck in agentic AI development: the high cost and inefficiency of manually annotating or searching for complex tool-use trajectories. By enabling smaller models to perform at the level of larger proprietary systems, ToolGrad offers a scalable path for deploying capable digital agents in enterprise and consumer applications.
ToolGrad: Efficient tool-use dataset generation with textual "gradients"
Google Research · 10 September 2026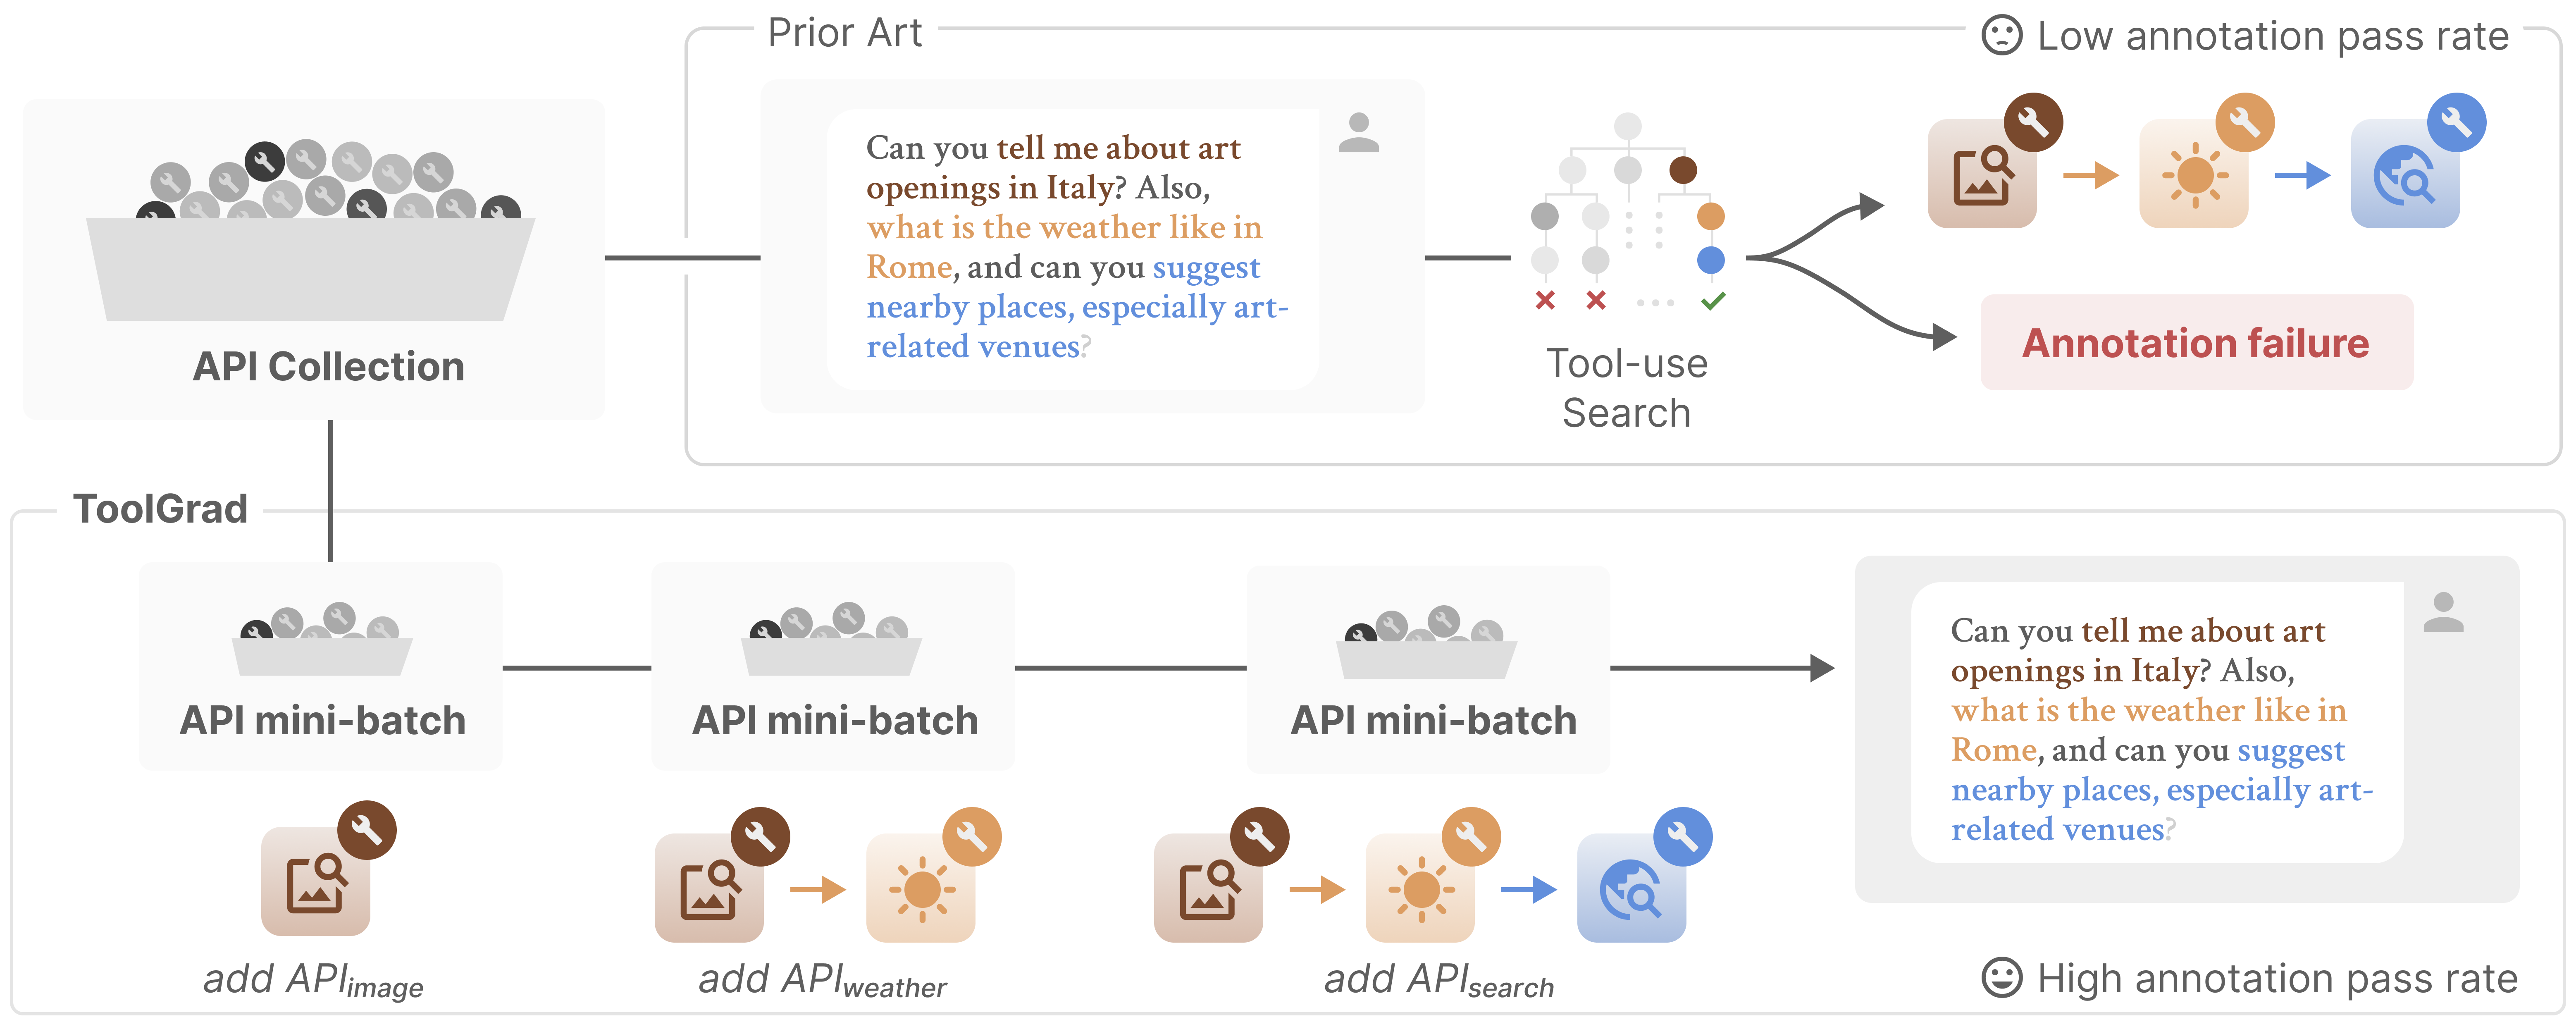
Loading the full article…
This text was published by Google Research. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
2sourcesThe headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- Nvidia pledges $250M in compute for UK AI agent safety research · 8 src
- OpenAI offers U.S. university labs free ChatGPT Business seats with Rosalind access · 2 src
- Anthropic reports small AI models may self-replicate on IoT devices within months · 29 src
- Researchers propose LLM-referenced C-test for evaluating supra-intelligence · 8 src
- Researchers study permutation diffusion LLMs for recommendation reranking · 1 src
Comments
via GitHub Discussions