DeepSeek releases V4.1-Flash with 1M context and MIT license
DeepSeek AI has released DeepSeek-V4.1-Flash, a multimodal Mixture-of-Experts model designed to address the memory bottlenecks of long-horizon agent workloads. The model features a 552B parameter backbone with 196B additional Engram parameters and supports a 1M-token context window. By activating only 8B parameters during prefill and 16B during decode, it significantly reduces computational…
Key points
- DeepSeek-V4.1-Flash features 552B parameters and a 1M-token context window with MIT-licensed open weights.
- New CSA2 architecture and FP4 quantization reduce KV cache footprint to 890 bytes per token.
- Model outperforms Opus-5 and GPT-5.6 Sol on Terminal-Bench 2.1 and DeepSWE v1.1 agentic tasks.
The release introduces several architectural innovations, including a Causal Encoder-Decoder structure that halves prefill compute and Compressed Sparse Attention 2 (CSA2), which reuses KV cache data across layers. These optimizations reduce the global KV cache footprint to 890 bytes per token, roughly 437 times smaller than DeepSeek-V1. The model also utilizes FP4 quantization for the main KV cache, further cutting storage requirements.
DeepSeek-V4.1-Flash is available under an MIT license with open weights on Hugging Face, supporting deployment via vLLM, SGLang, and Transformers. The team reports that the model outperforms competitors like Opus-5 and GPT-5.6 Sol on specific agentic benchmarks, such as Terminal-Bench 2.1 and DeepSWE v1.1, while maintaining efficient resource usage for enterprise and research applications.
Model page: DeepSeek-V4.1-Flash →
The story so far
3 episodes →- DeepSeek releases V4.1-Flash with 1M context and MIT licensethis story
DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse
MarkTechPost · 10 September 2026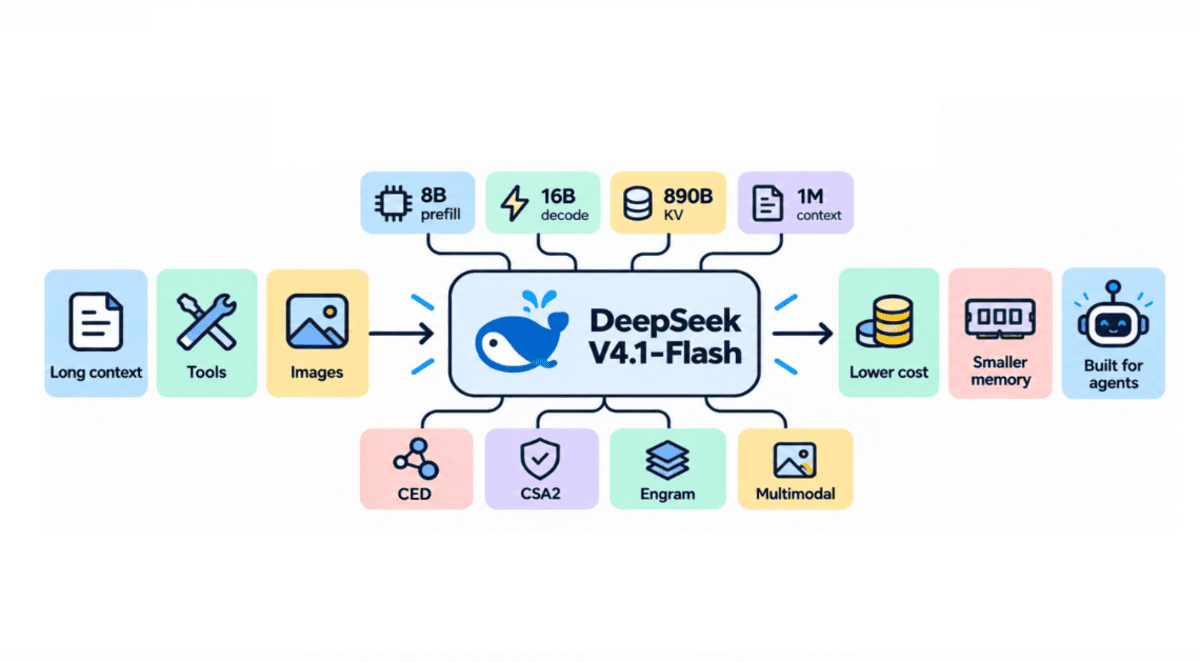
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
6sources- Reddit discussionreddit.com
- Why DeepSeek-V4.1-Flash Is Such an Exciting Open Model ReleasePress · KDnuggets ·
- DeepSeek V4.1 Flash at 41 tok/s on 8× A40 on TensorSharpPrimary source · github.com ·
- Baseten Adds DeepSeek-V4.1-Flash to Model APIs With 1M-Token ContextPress · Unite.AI ·
- SK Hynix, Samsung Shares Dip In Korea After DeepSeek Debuts AI Tech That Uses Less Memory – Micron, SanDisk Hold UpPress · finance.yahoo.com ·
- New Deepseek model V4.1-Flash cuts memory needs for AI agentsPress · The Decoder ·
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- Introducing Mistral Large 4 · 7 src
- OpenAI boosts GPT-6 speed by 50% in 28 Days update · 1 src
- Reflection AI debuts Beam, a 501B open-weight model rivaling GLM 5.2 with 3-4x less compute · 10 src
- Author tests four AI assistants on flawed forecasting scenarios · 1 src
- Anthropic prompts users to share voice data to enhance AI models · 8 src
Comments
via GitHub Discussions