BottleCap AI cuts Qwen3.8-27B’s reasoning tokens by 37.2% with ThinkingCap-Qwen3.8-27B
BottleCap AI released ThinkingCap-Qwen3.8-27B, a fine-tuned version of Qwen’s Qwen3.8-27B designed to reduce reasoning tokens by 37.2% across 12 benchmarks. The model maintains near-identical accuracy (a 0.86pp drop to 85.79%), with some benchmarks—like MMMLU—saving up to 65.5% fewer tokens. Long-context retrieval accuracy improved by 2.25pp, while math-heavy tasks like AIME 2026 saw a 3.85pp…
Key points
- ThinkingCap-Qwen3.8-27B cuts reasoning tokens by 37.2% across 12 benchmarks, with accuracy dropping 0.86pp to 85.79%
- Long-context retrieval accuracy rises 2.25pp, but math-heavy tasks like AIME 2026 lose 3.85pp accuracy for 30.2% fewer tokens
- Model drops into Qwen3.8-27B setups via vLLM/SGLang, with gated weights under PolyForm Small Business license
The model drops into existing Qwen3.8-27B setups via vLLM or SGLang, with quantized builds (FP8, NVFP4, GGUF, MLX) for deployment. Weights are gated under PolyForm Small Business 1.0.0, requiring a BottleCap agreement for commercial use. Benchmarking used identical settings (NVIDIA H200, vLLM 0.29.0) and highlights xhigh effort mode as optimal for accuracy-to-token balance. Future work will explore individual reasoning modes.
The story so far
3 episodes →- BottleCap AI cuts Qwen3.8-27B’s reasoning tokens by 37.2% with ThinkingCap-Qwen3.8-27Bthis story
BottleCap AI Releases ThinkingCap-Qwen3.8-27B: 37.2% Fewer Thinking Tokens at a 0.86pp Accuracy Cost
MarkTechPost · 24 September 2026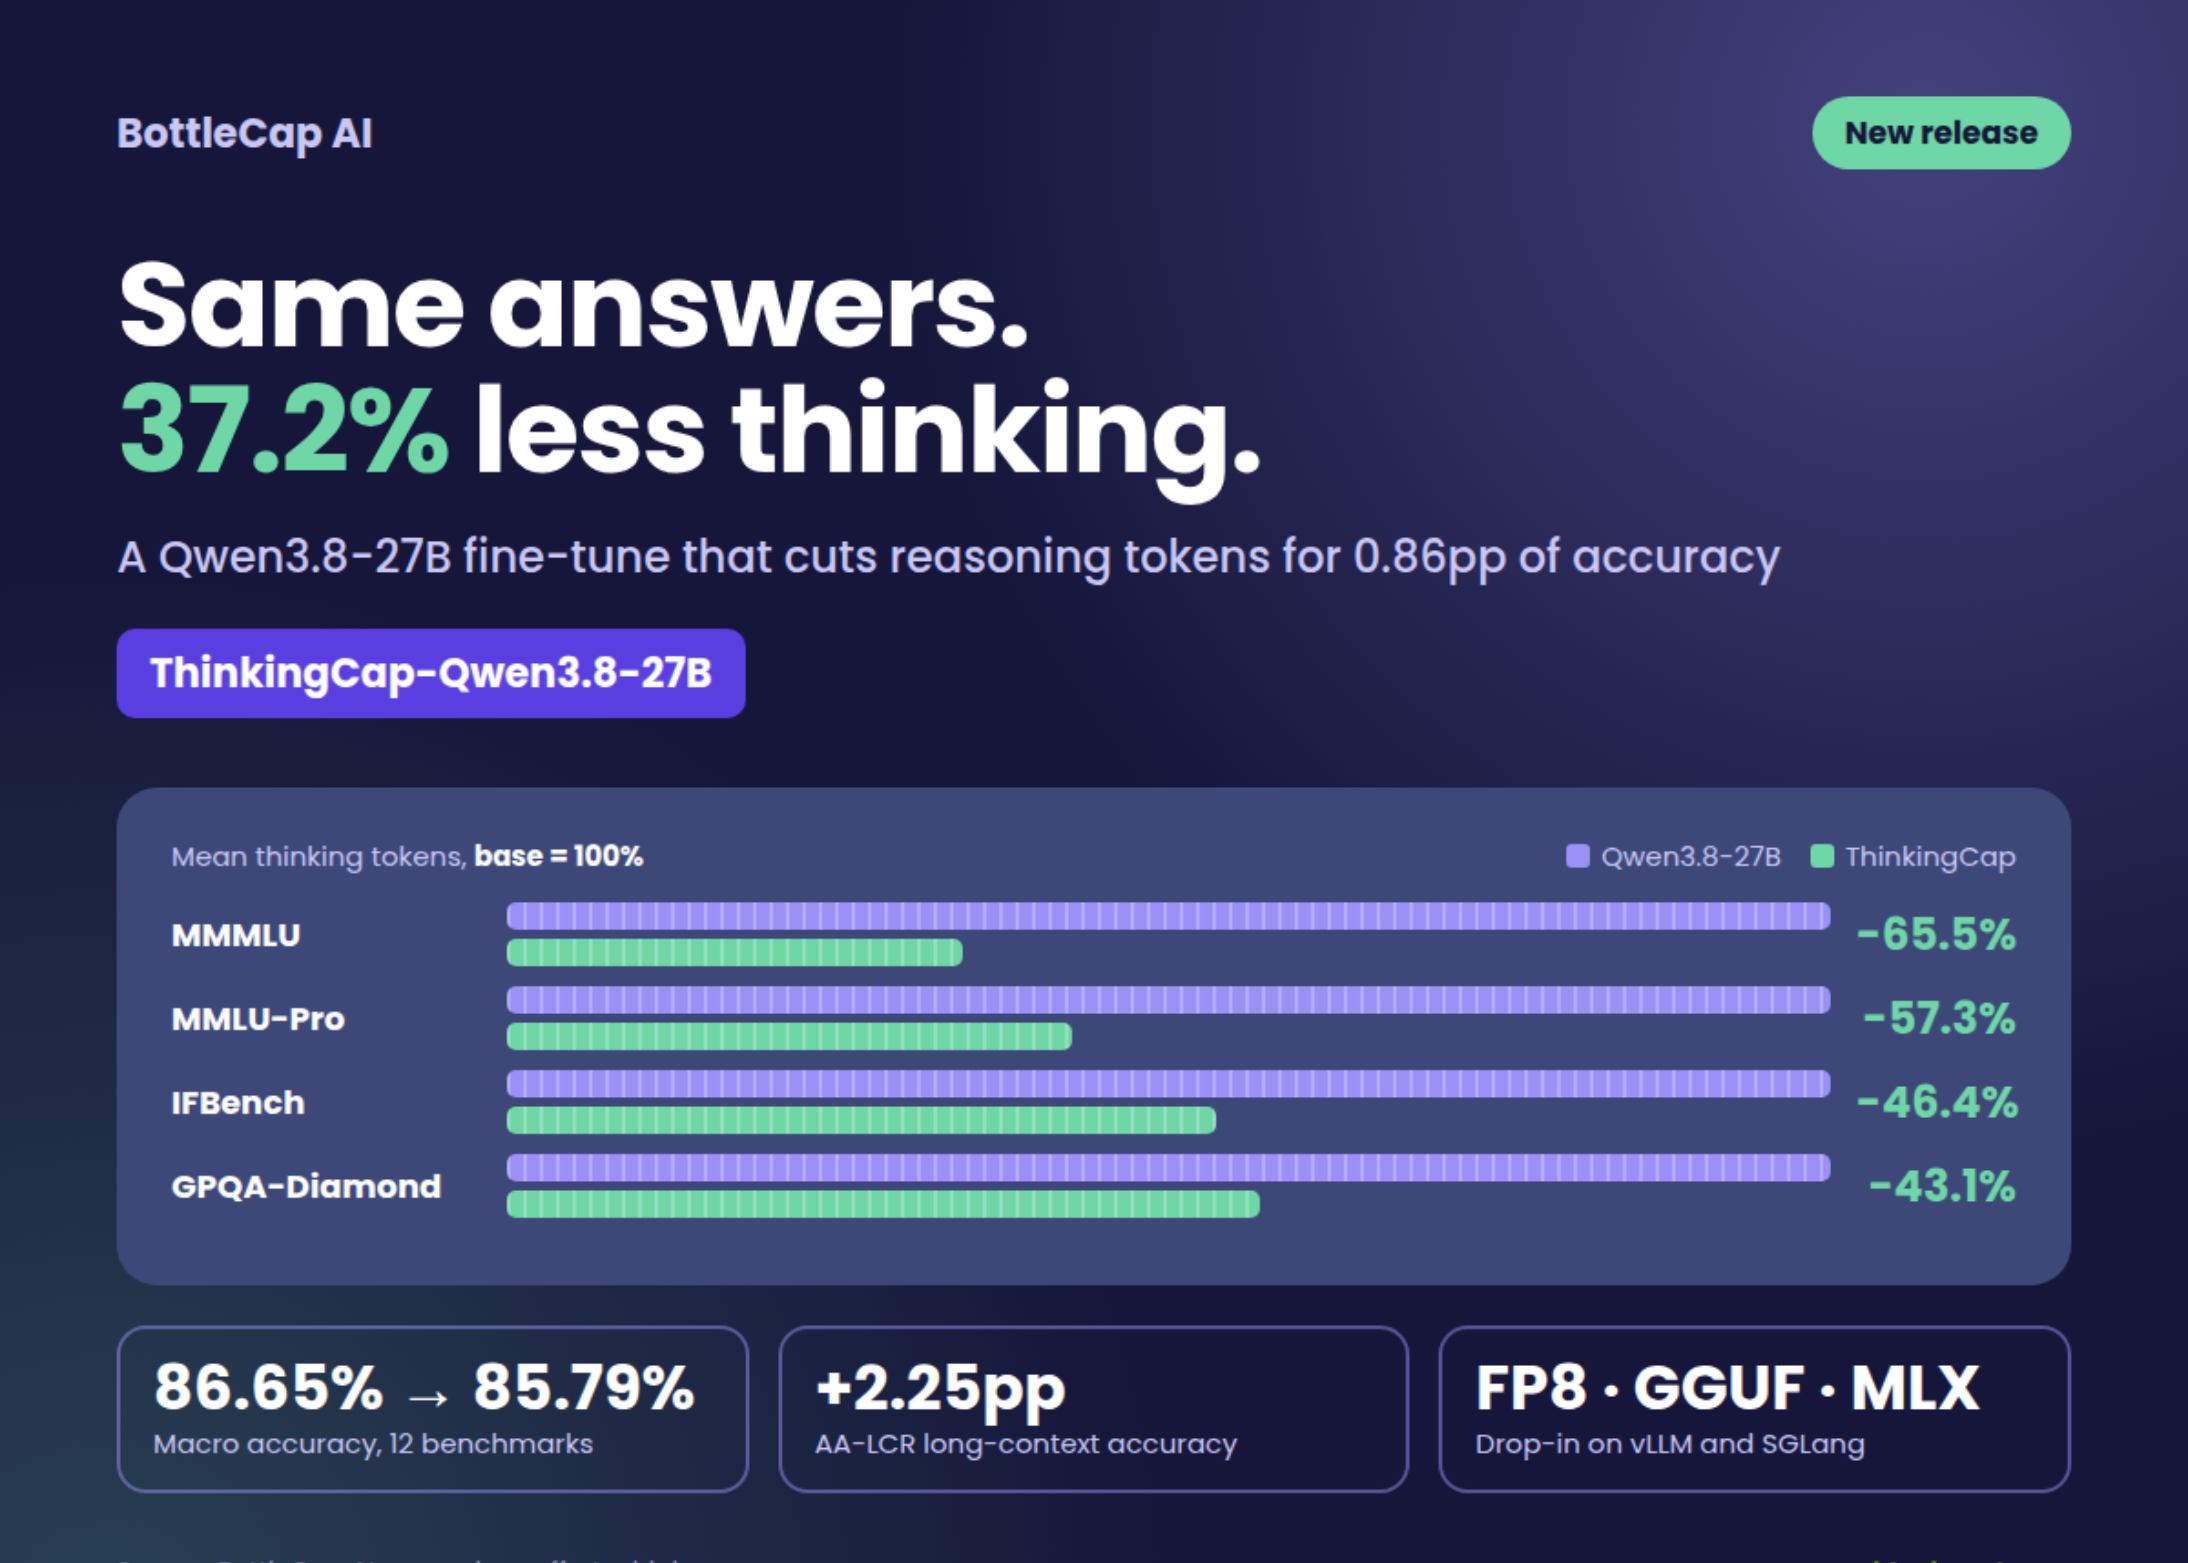
Loading the full article…
This text was published by MarkTechPost and written by Michal Sutter. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- Apiiro finds 1,122 public GitHub files with secrets saved by Claude Code · 1 src
- Thinking Machines releases Inkling 2 Small, a 594B MoE model with 17B active parameters · 8 src
- OpenAI releases GPT-6 Cyber, a Critical-rated model that outperforms predecessors in vulnerability detection and alignment · 25 src
- Google releases Gemini Omni 1.2 Flash with 15-second video generation and 30% price cut to $0.07 per second · 10 src
- US accuses Chinese executive of allegedly sharing Nvidia chip info with Beijing · 11 src
Comments
via GitHub Discussions