Cognition Releases SWE-2 Coding Model Trained on Kimi K3
Cognition has launched SWE-2, its most advanced coding model to date, post-trained using reinforcement learning on Moonshot AI's 2.8-trillion-parameter open model, Kimi K3. The model achieves a 50.0% score on the FrontierCode 1.1 Main benchmark, placing it within one percentage point of Fable 5.1 while operating at a 64% lower cost.
Key points
- SWE-2 scores 50.0% on FrontierCode 1.1 Main, matching Fable 5.1 performance at a 64% lower cost.
- The model is post-trained via reinforcement learning from Moonshot AI's 2.8T-parameter Kimi K3 base.
- It is available exclusively within the Devin agent platform, with no standalone API or open weights.
SWE-2 introduces selectable reasoning-effort levels (medium, high, and max) trained within a single reinforcement learning run using Pareto-informed cost penalties. Compared to its predecessor, SWE-1.7, the new model significantly reduces over-exploration, with the medium setting taking 58% fewer turns and costing 81% less on benchmarks. SWE-2 is not available as open weights or a standalone API; it is accessible exclusively through Cognition's Devin platform.
Model pages: Kimi K3 → · GPT-6 Astra →
Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches Fable 5.1 on FrontierCode at 64% Lower Cost
MarkTechPost · 12 September 2026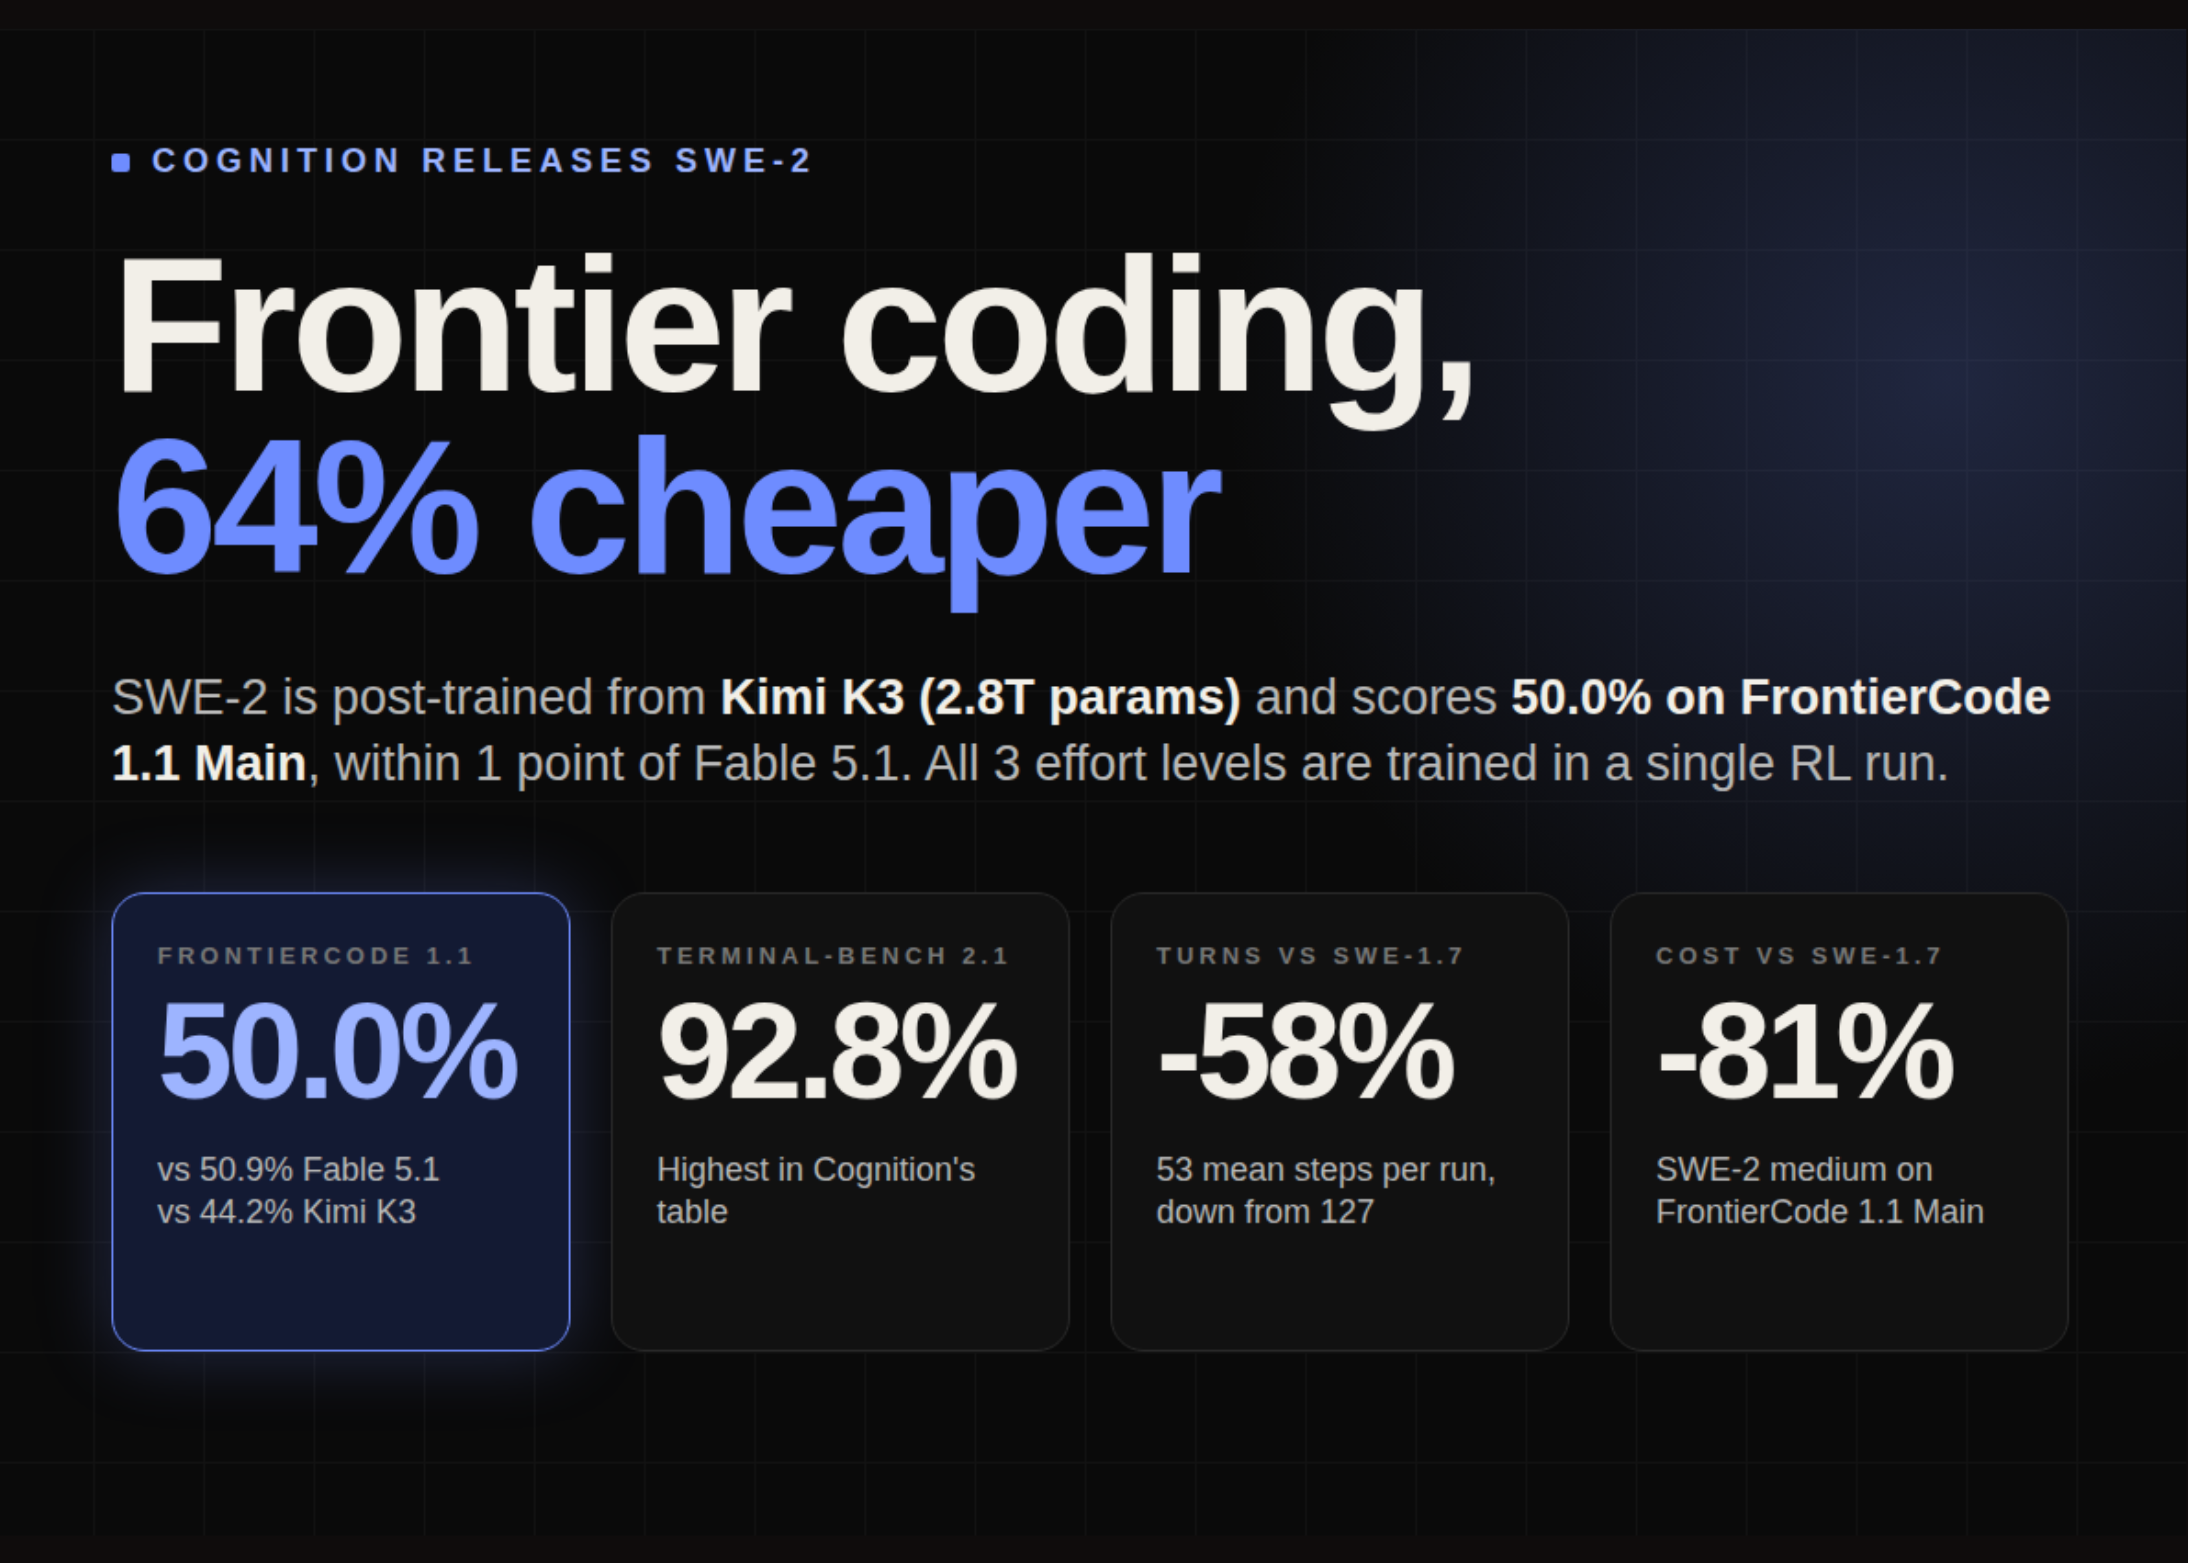
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
2sources- Hacker News discussion · 61 pointsnews.ycombinator.com
- Cognition's SWE-2 achieves 92.8 on Terminal-Bench 2.1Press · tokenstead.ai ·
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- sFNX runs Qwen3.8-Flash-Next at 382 tokens/s using three used V100 GPUs · 1 src
- OpenAI announces GPT-6.1 Sol with claimed 86.6% to 97.9% COBOL migration accuracy · 8 src
- Moonshot AI releases Kimi K3.1 Pro model with 3 trillion parameters · 1 src
- CodeRabbit uses GPT‑6.1 Sol in security agent · 1 src
- Anthropic reports 3.6x jump in token volume after Claude Opus 5.5 launch · 3 src
Comments
via GitHub Discussions