Fireworks AI releases Ember-1, a post-trained Kimi K3 model
Fireworks AI has released Ember-1, a specialized model derived from Moonshot AI’s open-weight Kimi K3. The new model is post-trained to produce shorter reasoning traces while maintaining task accuracy, addressing the high token costs associated with reasoning models in multi-turn agentic workloads. Fireworks reports that Ember-1 delivers Kimi K3’s quality with approximately 40% fewer tokens.…
Key points
- Ember-1 is a post-trained Kimi K3 model that uses about 40% fewer tokens while maintaining accuracy.
- The model is available only via Fireworks serverless API as a Research Preview; weights are not released.
- Production A/B tests showed output tokens per task fell from 49.3K to 29.9K with comparable quality scores.
The model is currently available only as a Research Preview through the Fireworks serverless API. Fireworks has not released the weights, training code, or exact algorithms, meaning self-hosting is not possible. Pricing remains identical to Kimi K3 at $3.00 per million input tokens and $15.00 per million output tokens, with savings coming solely from reduced token generation.
In production A/B tests with two customers, Ember-1 reduced output tokens per task from 49.3K to 29.9K while keeping the task score nearly unchanged (0.753 vs 0.751). Fireworks states that Ember-1 leads Kimi K3 Max on Terminal Bench 2.1 and DeepSWE 1.1, though it trails slightly on SWE-bench Verified. The company claims these results were achieved using its own data and no customer data, with all training conducted on Fireworks Serverless Training.
Model pages: Ember-1 → · Kimi K3 →
Fireworks AI Releases Ember-1: A Post-Trained Kimi K3 That Uses About 40% Fewer Tokens
MarkTechPost · 28 September 2026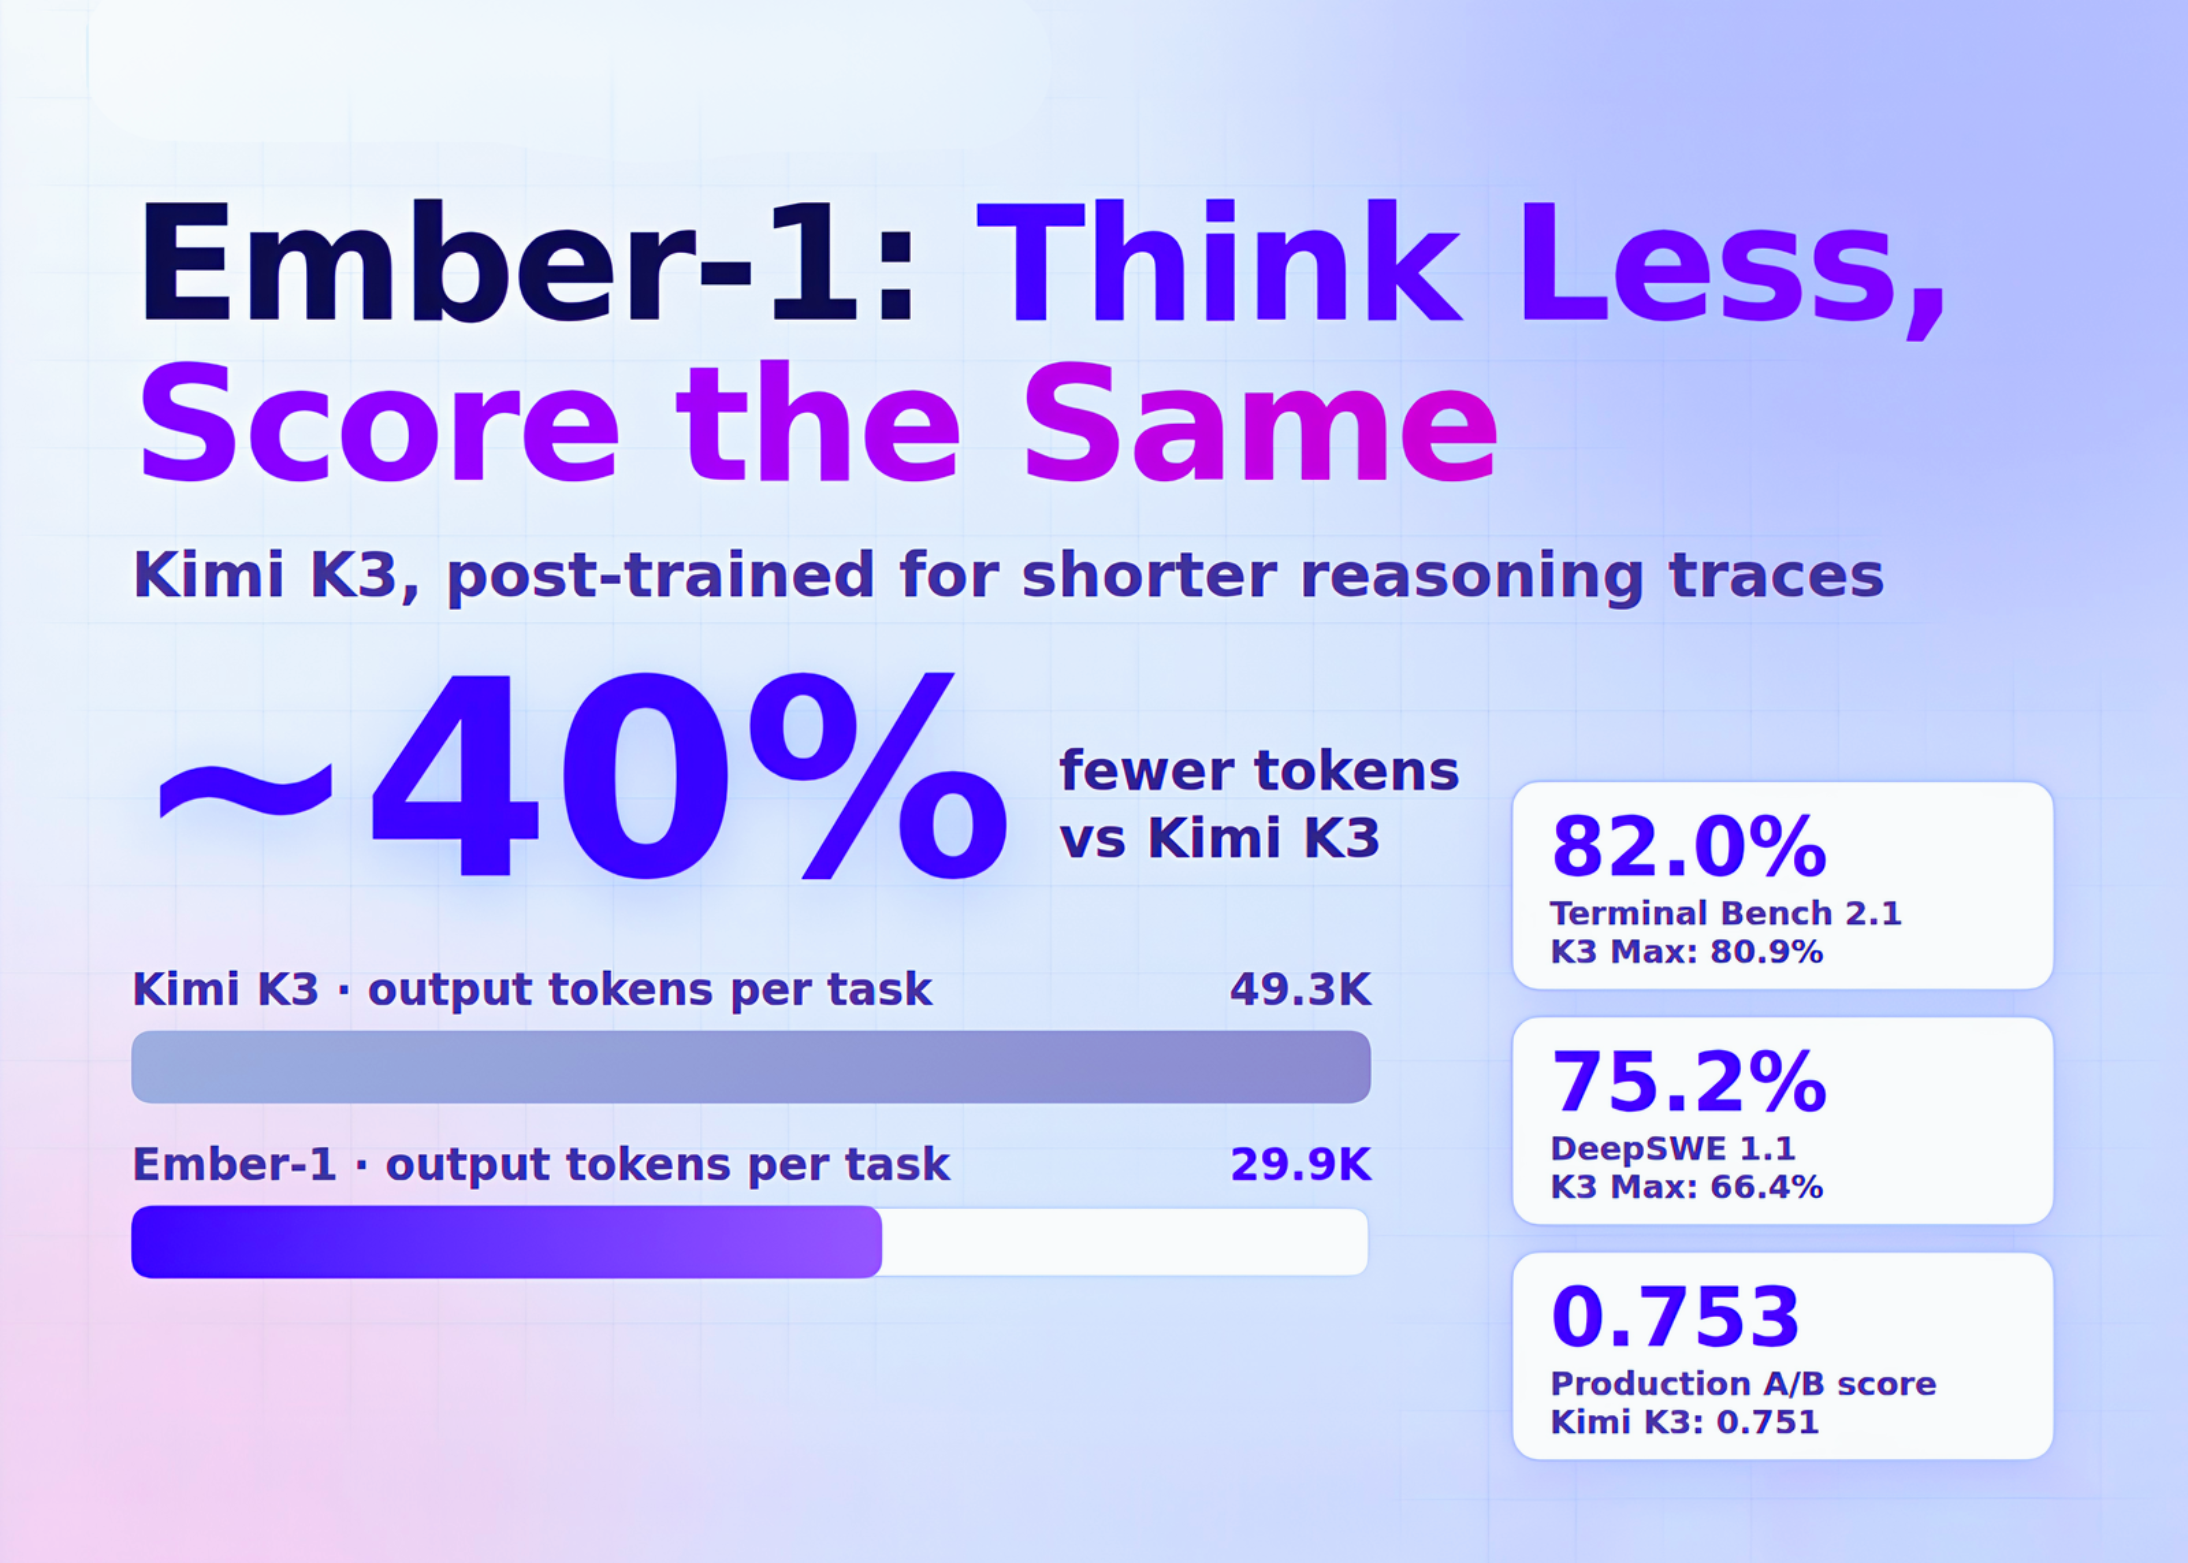
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- Introducing Mistral Large 4 · 7 src
- OpenAI boosts GPT-6 speed by 50% in 28 Days update · 1 src
- Author tests four AI assistants on flawed forecasting scenarios · 1 src
- Anthropic prompts users to share voice data to enhance AI models · 8 src
- Anthropic cuts cache-reading fees by 75% in Claude Fable 5.1 · 1 src
Comments
via GitHub Discussions