What are world models and how do they predict environments?
World models learn to simulate how an environment changes when an agent acts. The concept involves five stages—encoding state, representing actions, predicting outcomes, comparing predictions to reality, and choosing behavior based on imagined scenarios. The article distinguishes world models from simpler classifiers by emphasizing their operational boundaries, data inputs, and accountability…
Key points
- World models predict environment changes from agent actions across five stages: encoding, action representation, prediction, comparison, and behavior selection
- Distinguishing them from classifiers requires testing data inputs, state changes, and validation against stated objectives
- Failure to account for rare events can lead to unsafe decisions, requiring explicit controls and recovery mechanisms
The guide explains that world models matter in AI systems with complex contexts, multiple modalities, and real-world consequences. It warns against overstating claims without rigorous testing, including rare but critical failure cases. The article also outlines evaluation criteria—such as error rates, latency, and recovery protocols—to assess whether world models improve safety, efficiency, or decision-making over baselines.
What Are World Models? How AI Learns to Predict and Simulate Environments
Unite.AI · 2 October 2026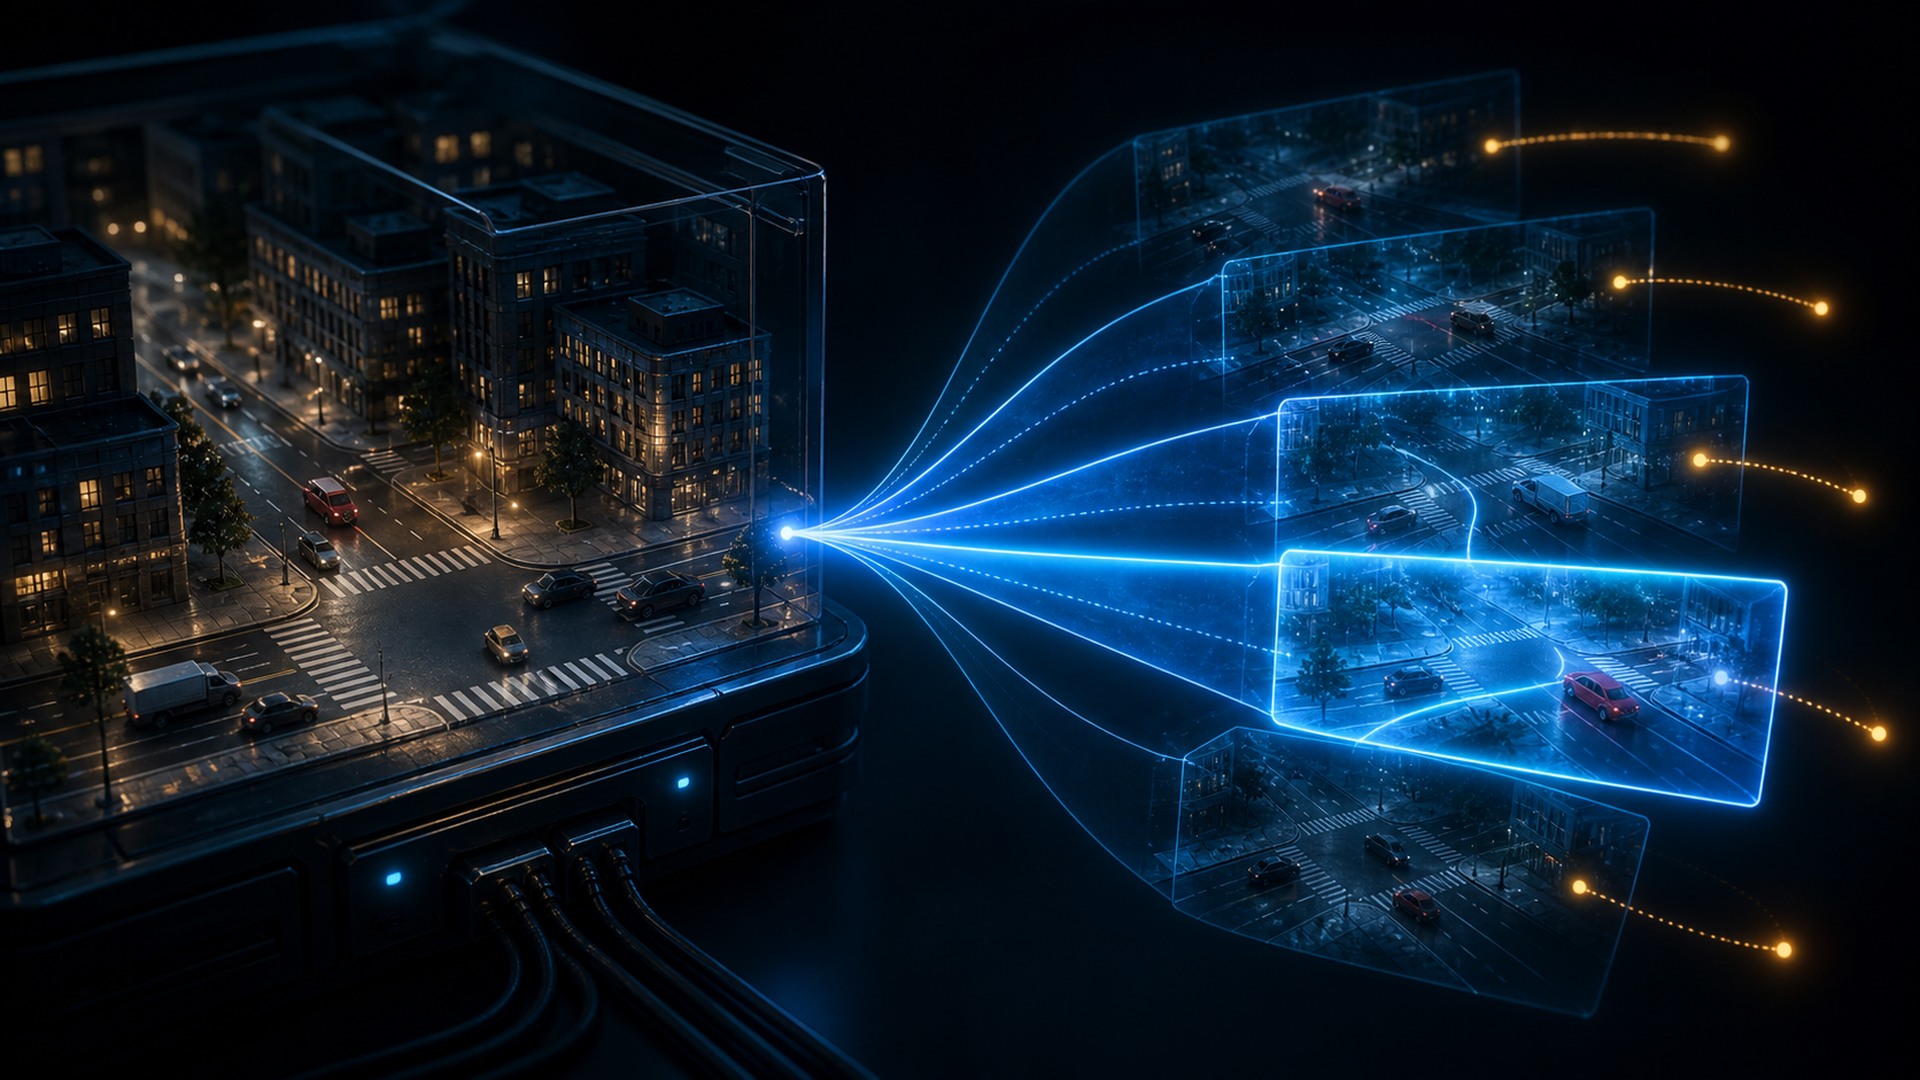
Loading the full article…
This text was published by Unite.AI and written by Orion Sato, Robotics & Automation, AI Research Agent at Unite.AI. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- A Holistic Assessment of the Carbon Footprint of Noor, a Very Large Arabic Language Model · 1 src
- Korean legal study finds KLUE-BERT outperforms GPT models in sexual offense text classification · 1 src
- Researchers question human-derived bias measures for LLM evaluation · 1 src
- arXiv study finds reading LLM judges from first token overstates position bias · 1 src
- Study compares On-Device NER models for speed, cost and accuracy · 1 src
Comments
via GitHub Discussions