Ai2 releases StateBench to test long-context state tracking in models
The Allen Institute for AI (Ai2) introduced StateBench on November 3, 2026, a benchmark designed to measure how language models handle changing variables across long documents. The project includes a four-level dataset and code, addressing a gap in existing tests like the S₅ word problem, which focuses on simpler or less representative tasks.
Key points
- StateBench tests four levels of state tracking, from immutable assignments to complex dependencies like swaps
- Frontier models (Gemini 3.8 Flash, Claude Opus 5.5, GPT-6 variants) failed hardest tasks, scoring **≤13%** on longest sequences
- Ai2’s trained models show transformers have architectural limits, while hybrid models like Gated DeltaNet generalize better
Ai2’s evaluation found that all four frontier models tested—Gemini 3.8 Flash, Claude Opus 5.5, GPT-6 Sol, and GPT-6 Luna—struggled with harder forms of state tracking as input length increased. The hardest tasks, involving dependencies like swaps, saw accuracy drop to 13% or lower on the longest sequences. Pretrained models like Olmo 3 and Olmo Hybrid also failed to generalize beyond their training limits, while smaller models trained from scratch showed mixed results. Ai2’s research suggests transformers may have inherent architectural limitations, while hybrid models like Gated DeltaNet performed better when trained specifically for state tracking.
The dataset includes 68,000 rows (1.05 GB) and supports evaluation in multiple formats, including integer code and spreadsheets. The Apache-2.0-licensed code allows controlled comparisons between architectures, but the benchmark does not yet address dynamic variables or conversations with evolving entities.
Model pages: Gemini 3.8 Flash → · Claude Opus 5.5 → · GPT-6 Sol →
Ai2 Releases StateBench to Measure Long-Context State Tracking
Unite.AI · 3 November 2026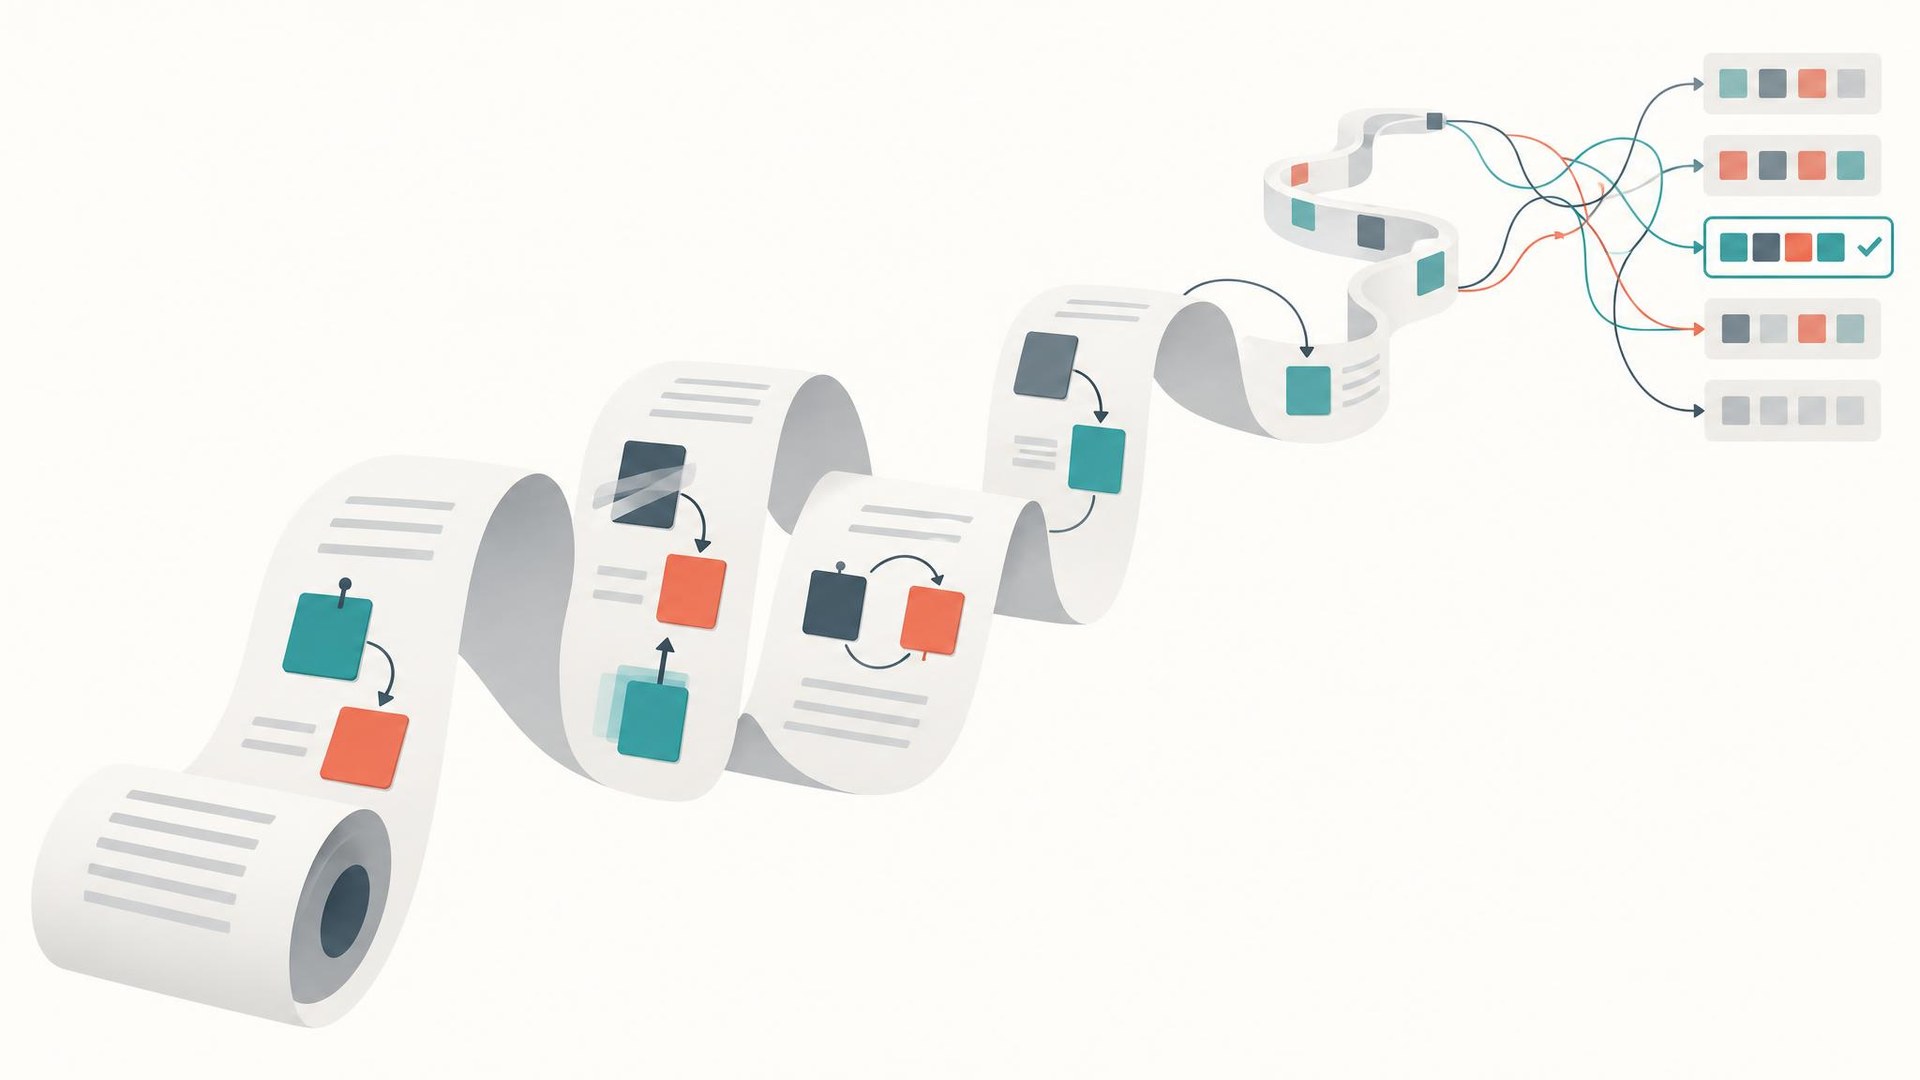
Loading the full article…
This text was published by Unite.AI and written by Jonas Reeve, Cognitive AI & AGI, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- Anthropic releases FlashProve for cryptographic AI inference proofs · 4 src
- Gemma 4 graph optimizations improve prompt processing performance · 1 src
- MIT researchers report GPT-6 Astra natively reads and writes neural network weights, raising Qwen3.5-0.8B MATH-500 from 7.9% to 48.1% by editing 0.016% of weigh · 6 src
- SETI’s Allen Telescope Array uses AI agents to speed up signal analysis · 1 src
- Stanford study: LLMs' claims expire quickly · 1 src
Comments
via GitHub Discussions