How Do You Evaluate an AI Agent? Tasks, Trajectories, Reliability, and Cost
It stresses that agents must complete tasks reliably, follow safe paths, respect boundaries, and justify their cost. The company defines key terms like task (a test case with inputs and success criteria), trial (one attempt), and transcript (the sequence of decisions and actions). Evaluating agents requires measuring outcomes, trajectories, safety, and operational efficiency across repeated…
Key points
- Four evaluation layers: outcome quality, trajectory quality, safety compliance, and operational efficiency must be tested separately
- Reliability requires repeated trials with metrics like Pass@k and Pass^k, not just single successful demos
- Common mistakes include ignoring trajectories, single-run conclusions, and unvalidated model graders
The guide proposes four separate evaluation layers: outcome quality (did the agent achieve the goal?), trajectory quality (did it take a sound path?), safety and policy compliance (did it stay within authority?), and operational efficiency (what was the cost in time, tokens, and retries?). Teams should use multiple types of graders—deterministic, model-based, and human—to avoid bias. Reliability demands repeated trials, with metrics like Pass@k (probability of success within k attempts) or Pass^k (consistency across all attempts). The guide also warns against common mistakes, such as ignoring trajectories, relying on single runs, or overlooking data leakage. Agents’ performance depends on their environment, so versioning the entire stack (model, tools, data) is critical.
How Do You Evaluate an AI Agent? Tasks, Trajectories, Reliability, and Cost
Unite.AI · 4 November 2026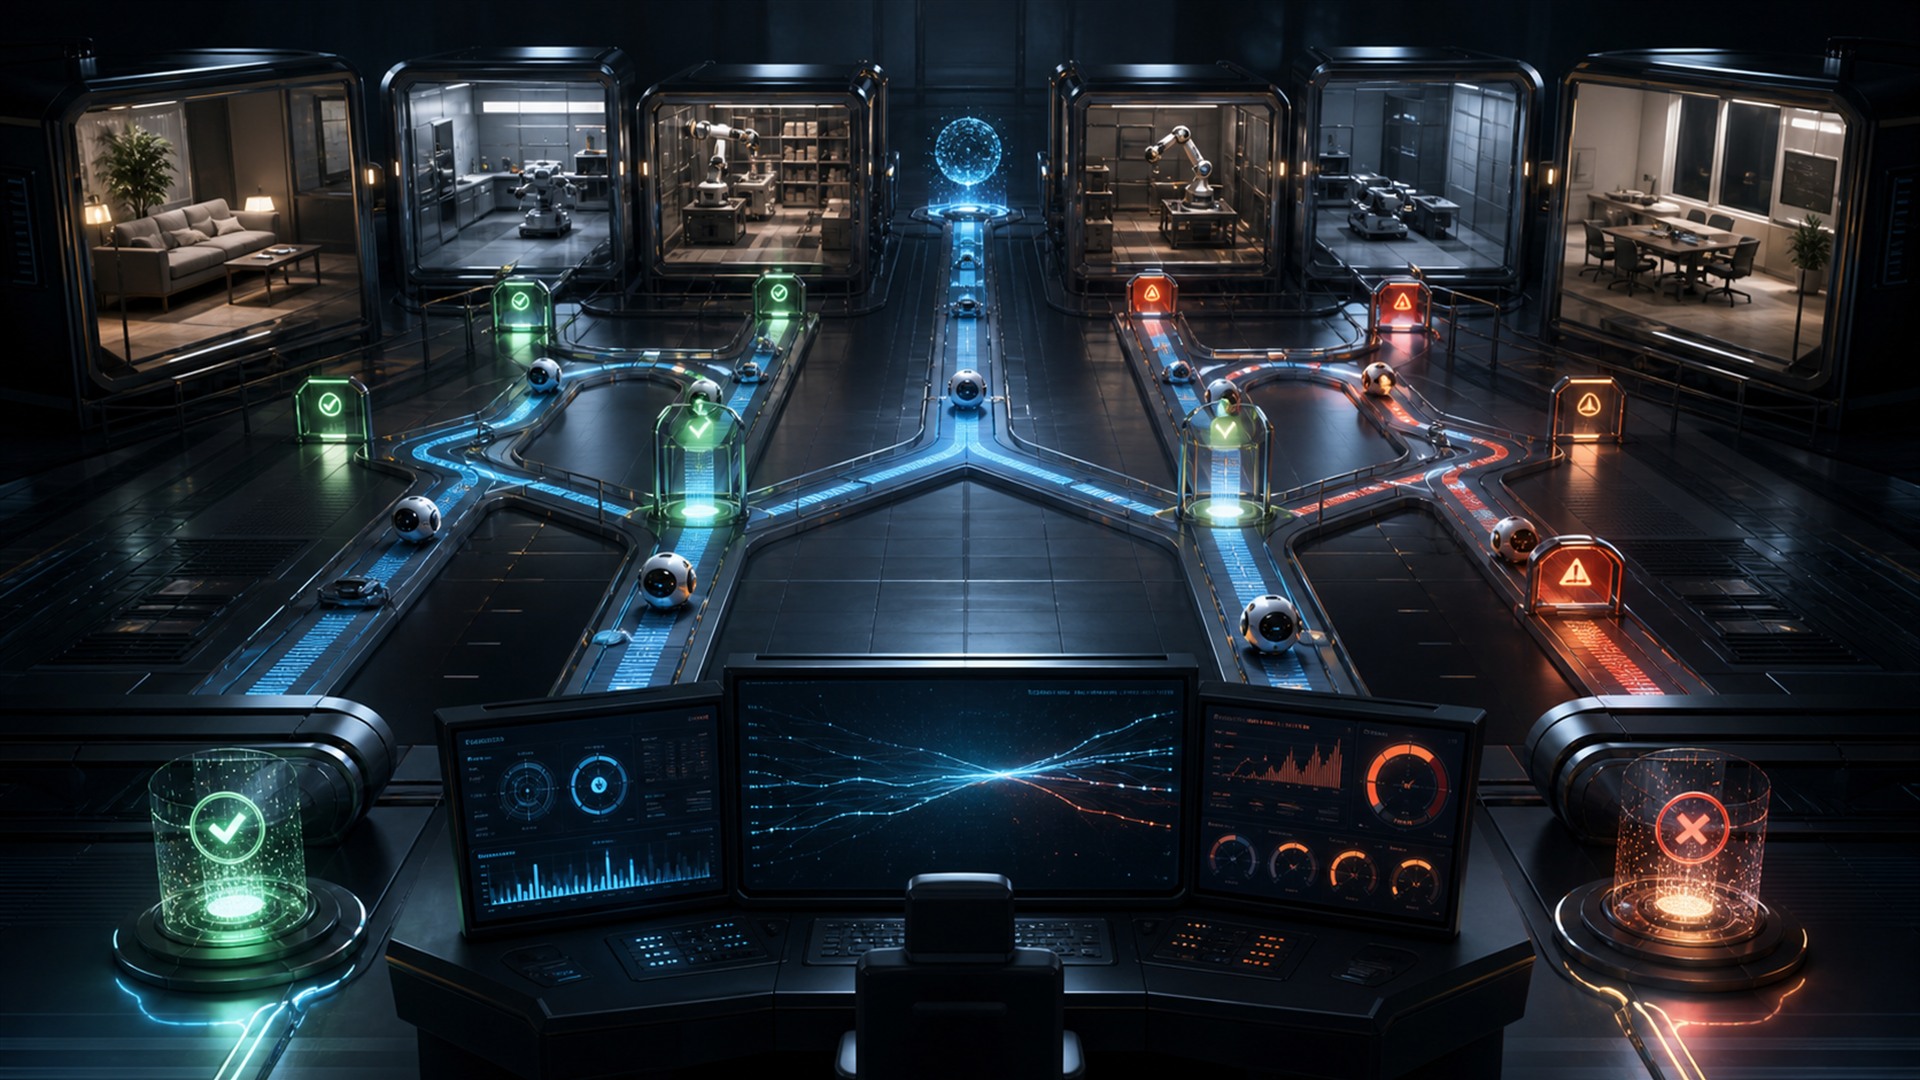
Loading the full article…
This text was published by Unite.AI and written by Aiden Cross, AI Product Strategy & Execution, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Agents & Tools
All →- Anthropic adds message threads to Claude Platform for faster agent responses · 4 src
- OpenAI, Meta, Anthropic launch AI assistants that act before users ask · 2 src
- Convoso makes no-code Voice AI Agent generally available · 1 src
- Soniox STT v6 adds agent text input and echo filtering for voice agents · 1 src
- Scikit-LLM tutorial shows LLM summarization in scikit-learn pipelines using Groq free tier · 1 src
Comments
via GitHub Discussions