Kyutai releases REKI 2.4B vision-language-action model for robot manipulation
Kyutai, together with Inria and École des Ponts, announced REKI, a 2.4 B parameter vision‑language‑action (VLA) model built on a 2.2 B Qwen3.5‑2B backbone plus a 0.2 B flow‑matching action expert. The model is pretrained solely on public data – a mix of 1.0 B video frames and 12.2 M vision‑language samples – and incorporates a cheap three‑frame memory that adds only 0.1 ms to inference.…
Key points
- REKI combines a 2.2 B Qwen3.5‑2B VLM with a 0.2 B flow‑matching action expert, totalling 2.4 B parameters.
- Achieves 90.4 % on LIBERO‑Plus and cuts RoboTwin pose oscillations from 18.6 % to 4.1 %.
- Runs on one NVIDIA H100 at 21.8 ms per action chunk, with only 0.1 ms overhead for a 3‑frame memory cache.
On out‑of‑distribution robot manipulation suites REKI scores 90.4 % on LIBERO‑Plus, the top result among publicly‑pretrained VLAs, and reduces pose‑oscillation failures on RoboTwin from 18.6 % to 4.1 %. Weights are released on Hugging Face under a CC BY‑NC‑SA 4.0 license, with six checkpoints covering the base model and finetunes for LIBERO, RoboTwin and RoboCasa variants. Deployment uses the LeRobot async‑inference gRPC protocol and can run on a UR5 arm after a short finetuning run.
Meet Kyutai REKI: The 2.4B VLA Model Bringing Efficient Memory to Robot Manipulation
MarkTechPost · 17 October 2026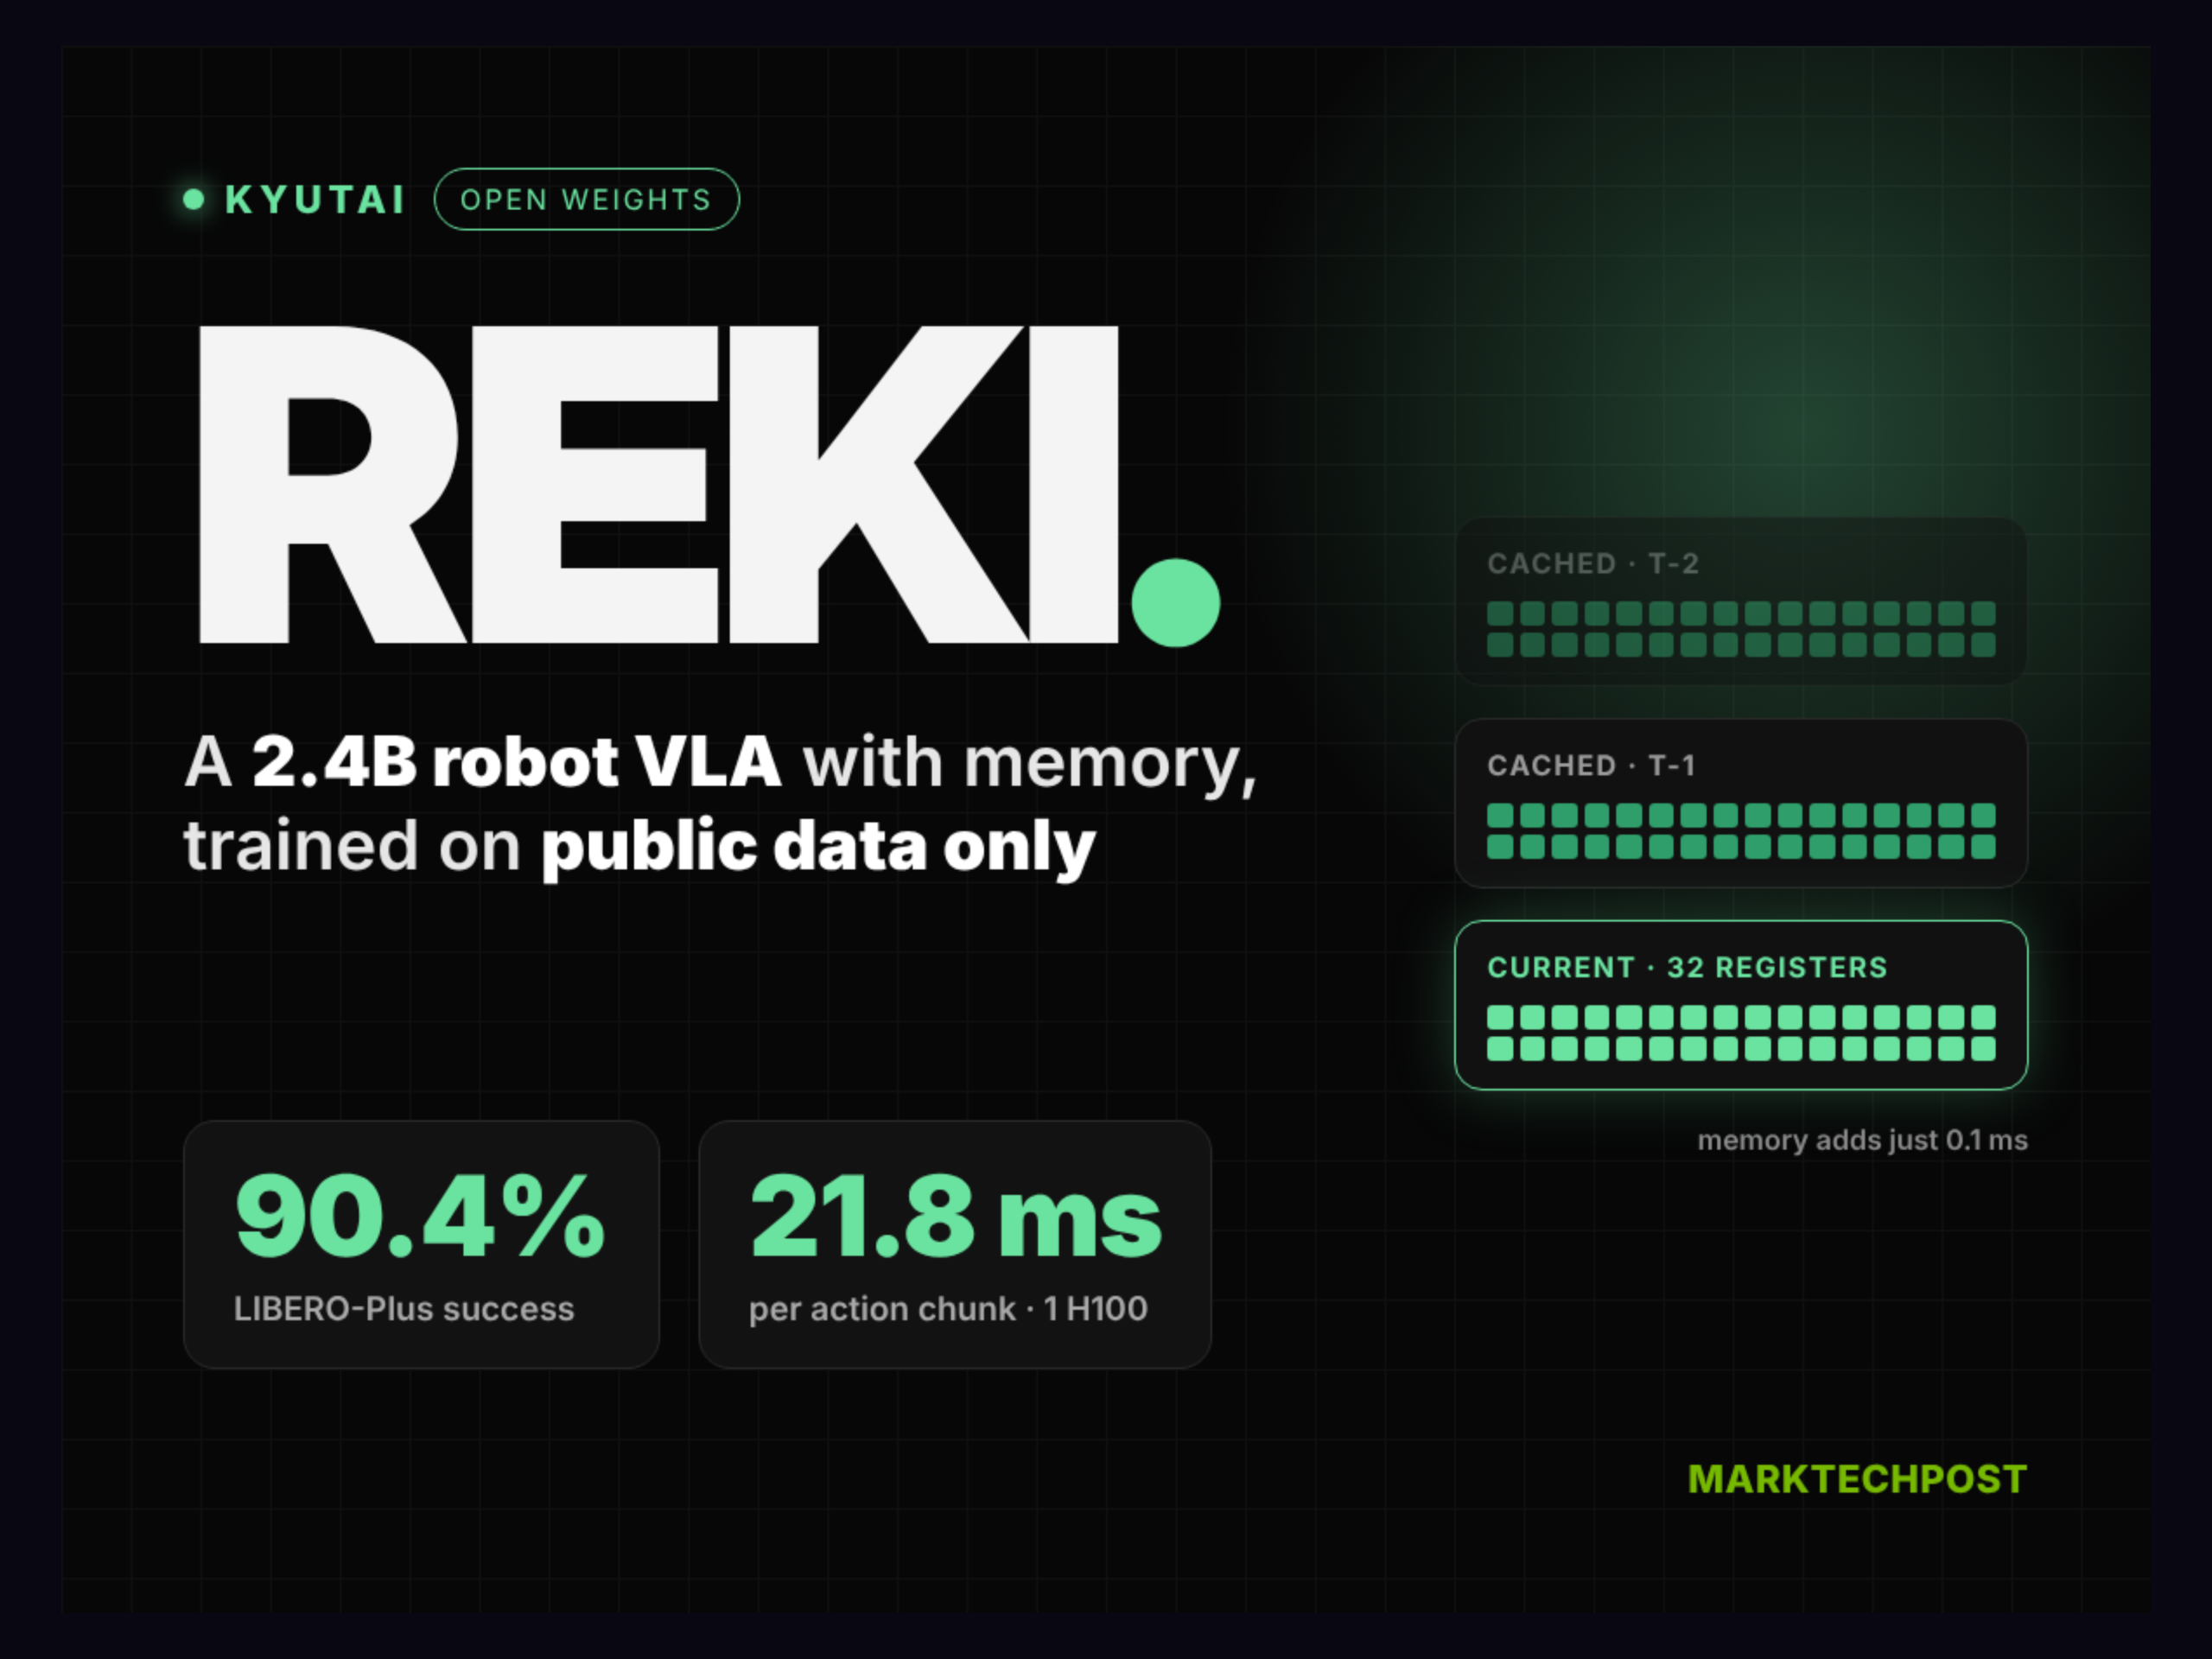
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- Google unveils Gemini 4 Argon with 1 million-token output · 1 src
- DeepSeek releases DeepSeek-V4.1-Flash-1017, scores 77.0 on DeepSWE v1.1 and opens Search and Fetch APIs · 6 src
- Meta releases Muse Spark Open, touted as highest‑performing open‑weights model in US · 1 src
- Meta releases Muse Spark Open, an 816B-parameter open-weight multimodal model with 42B active parameters and 1M-token context · 33 src
- Ggml-org merges CUDA patch to accelerate low-bit MMVQ in llama.cpp · 1 src
Comments
via GitHub Discussions