Linkup Research releases sparseup 149M-parameter sparse embedding model
Linkup Research announced SPARSEUP, an open‑source sparse embedding model built on a 149 million‑parameter ModernBERT backbone. The model is released under the Apache 2.0 license on Hugging Face and can be loaded via Transformers or Sentence‑Transformers with the appropriate flag. It incorporates three engineering fixes – a logit shift of 15, per‑position top‑12 token expansion, and case folding…
Key points
- SPARSEUP is a 149M‑parameter sparse encoder released under Apache 2.0 on Hugging Face.
- It achieves 56.4 nDCG@10 on BEIR‑13, the highest among public sparse models under 150M parameters.
- On MS MARCO it reaches >97% recall in ~380 µs per query with 47 and 190 non‑zero terms.
SPARSEUP scores 56.4 nDCG@10 on the BEIR‑13 benchmark, which Linkup claims is the strongest public vocabulary‑based sparse encoder under 150 M parameters. In the same controlled setting LateOn scores 58.9 and DenseOn 57.9. On MS MARCO the model attains over 97 % recall in roughly 380 µs per query (single‑threaded), with an average of 47 non‑zero terms per query and 190 per document. Training fits on a single H100 GPU and uses LightOn’s fine‑tuning mixture with contrastive learning.
Model page: SPARSEUP →
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
MarkTechPost · 19 September 2026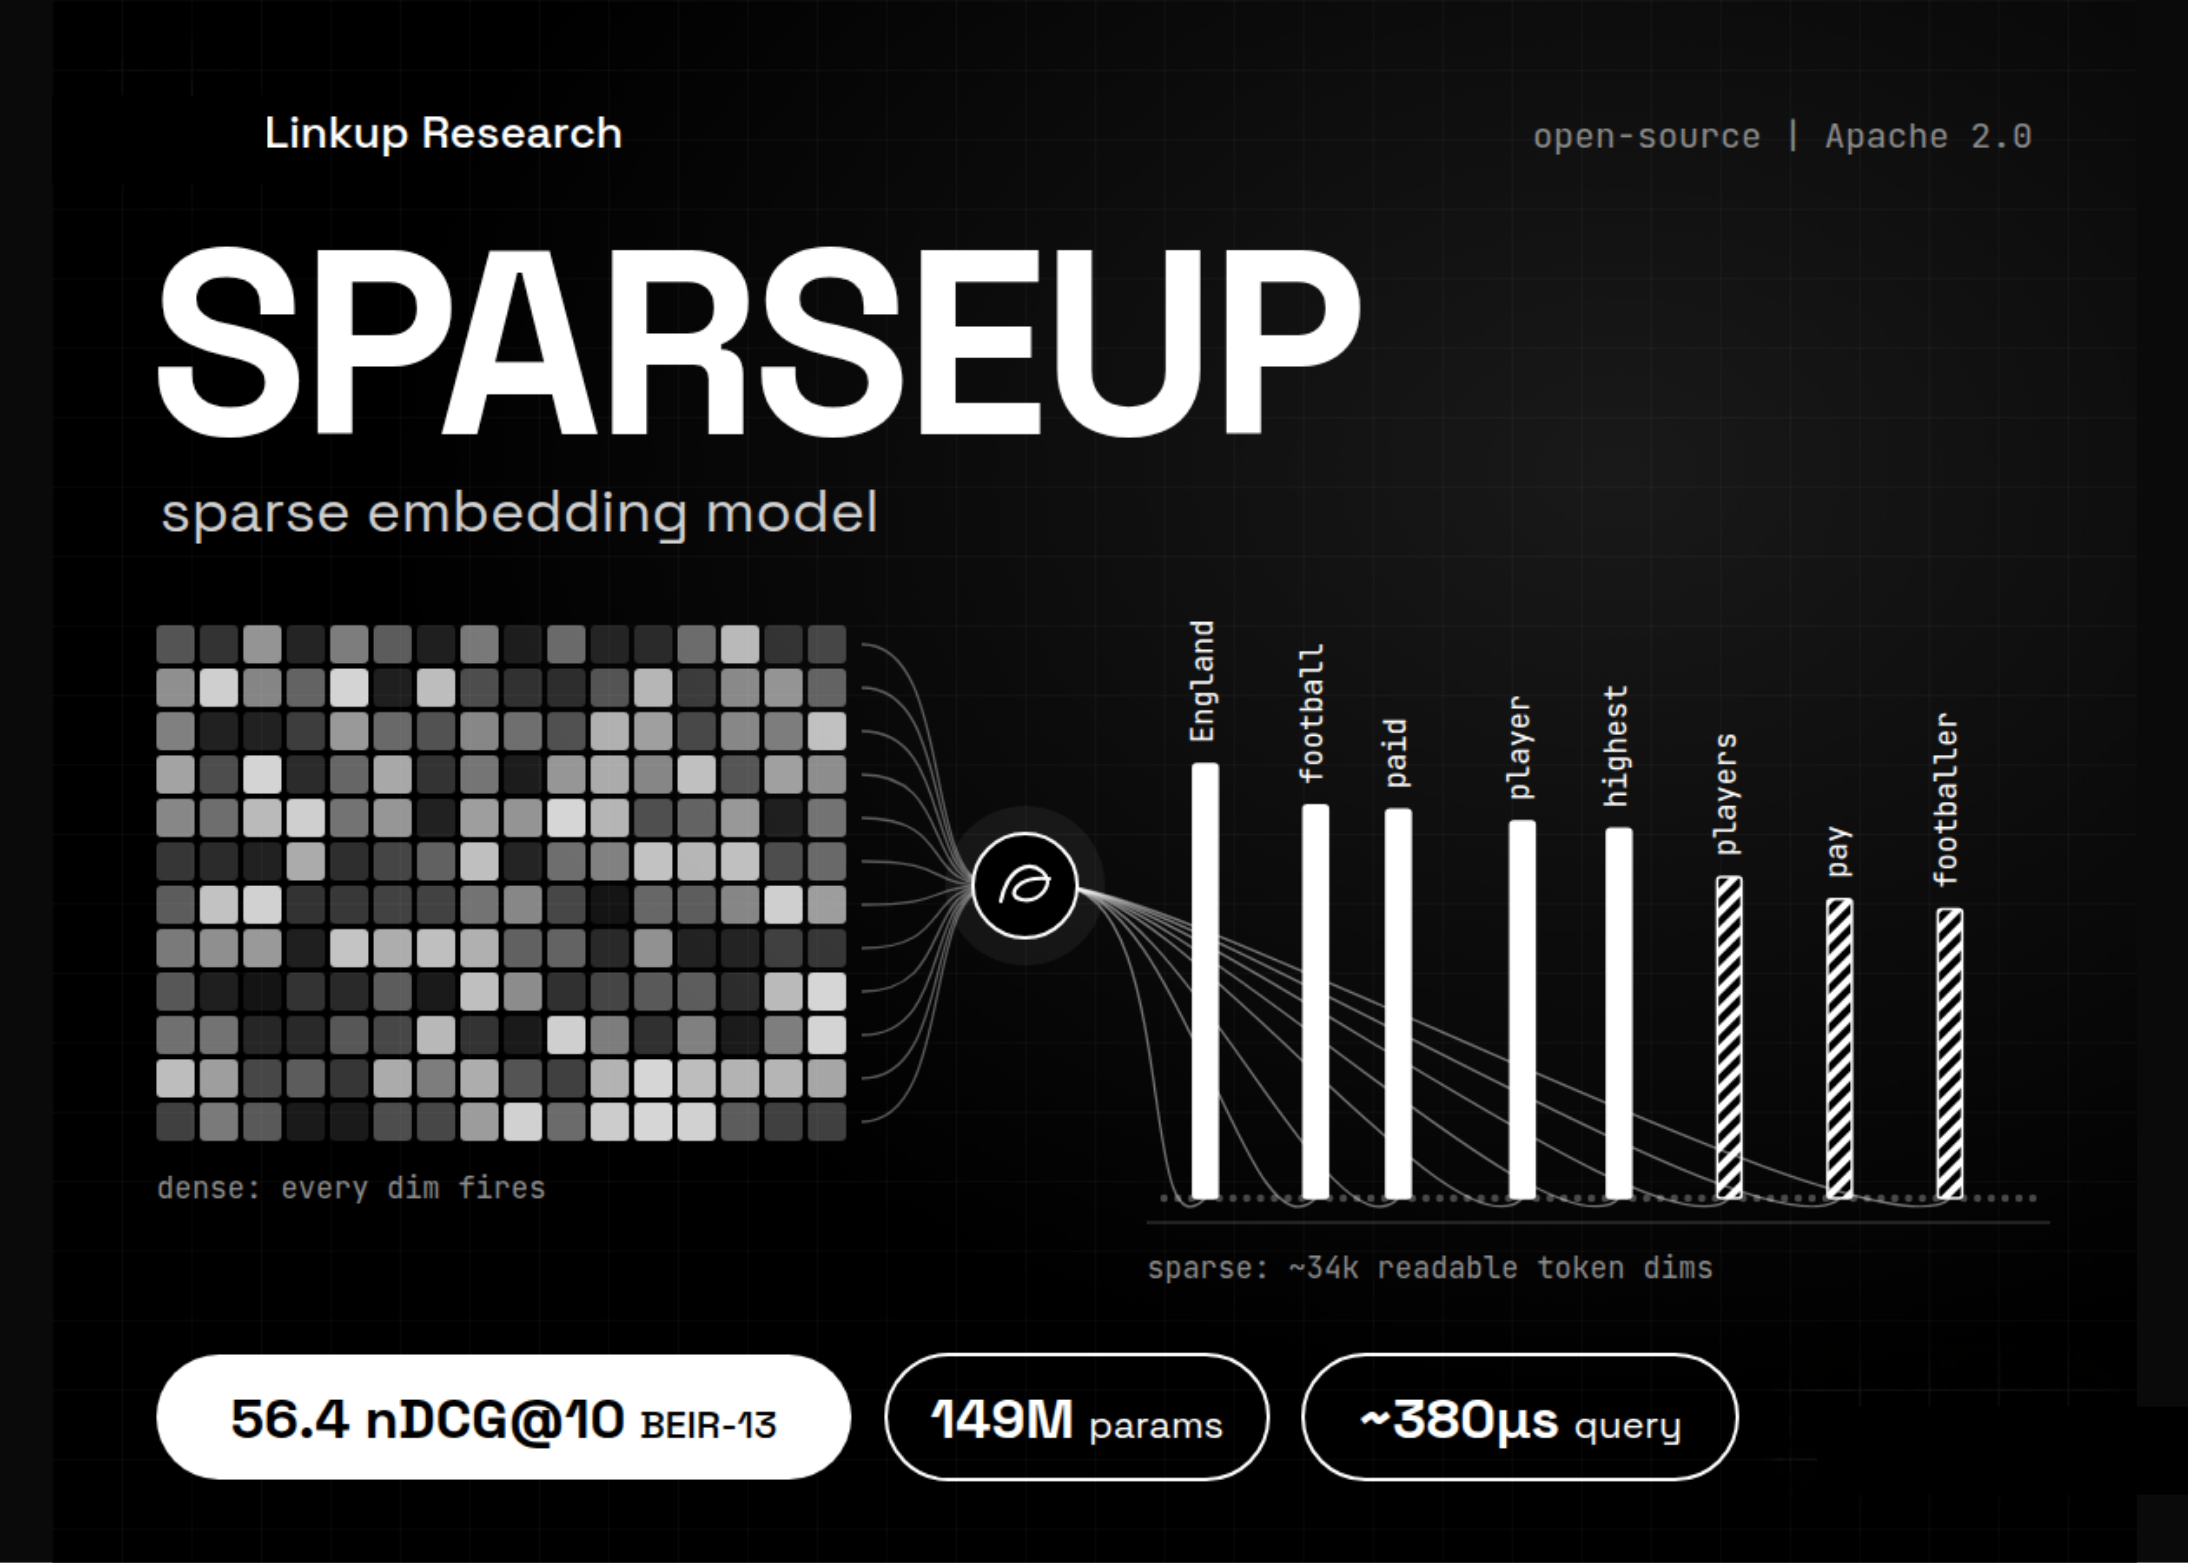
Linkup research team releases SPARSEUP, an open-source learned sparse embedding model. The model runs on a 149M-parameter ModernBERT backbone and ships under Apache 2.0. Linkup team reports 56.4 average nDCG@10 on BEIR-13. It calls this the strongest public vocabulary-based sparse encoder it knows of under 150M parameters.
Is it deployable? Yes. The weights are on Hugging Face under Apache 2.0. The model loads through Transformers or Sentence Transformers with trust_remote_code=True.
Why a Sparse Model, and Why Now
Most open retrieval models are dense: 1 vector per text. Sparse models output weights over a vocabulary instead. Each dimension maps to a real token, so vectors fit inverted indexes and humans can read them. They also tend to match rare words well.
The trigger was LightOn’s DenseOn and LateOn release. LightOn published open data, a training recipe, a dense model and a late-interaction model. SPARSEUP fills the missing sparse slot. It uses the same backbone family and fine-tuning data, so all 3 retrieval styles can be compared side by side.
How is SPARSEUP Built
Training starts from LateOn-unsupervised. That checkpoint had no MLM head, so the team grafted back ModernBERT’s original one. Fine-tuning used LightOn’s fine-tuning mixture with contrastive learning only. Each query gets 7 hard negatives sampled from a pool of 50, and in-batch negatives. There is no cross-encoder distillation, and training fits on a single H100.
A vanilla SPLADE on this backbone produced huge bags full of stopwords. Linkup fixed this with 3 changes:
- Logit shifting: The encoder computes
log(1 + ReLU(x - 15)). ModernBERT’s MLM logits sat too high, saturating the log and making bags dense at initialization. - Per-position top-k: Each input token keeps only its 12 strongest vocabulary dimensions before max pooling. This caps expansion per token, not total vector size.
- Case folding: Byte-level BPE stores
heat,Heat,ĠheatandĠHeatas separate ids. SPARSEUP folds them onto 1 id and keeps the largest weight. Output dimensions drop from about 50k to about 34k.
Queries and documents take [Q] and [D] prefixes, and scoring is a dot product. Evaluation max lengths are 128 tokens for queries and 512 for documents.
Benchmark Results
Against other sparse encoders on BEIR-13 (nDCG@10, without MS MARCO), per the model card:
The controlled comparison is less flattering. With backbone and data fixed, LateOn scores 58.9, DenseOn 57.9 and SPARSEUP 56.4. SPARSEUP uses approximate Seismic search, while LightOn reports exact search. SPARSEUP wins ArguAna and Touché and beats DenseOn on HotpotQA. It lags on more semantic sets, with FiQA showing the largest gap. DBPedia is another weak spot.
On decontaminated BEIR, the gap to DenseOn shrinks to 0.17 points. Linkup warns that decontaminated NQ and MS MARCO have only 21 and 46 queries, so those results are noisy.
Speed and Sparsity
On MS MARCO, SPARSEUP averages 47 non-zero terms per query and 190 per document. SPLADE-v3 averages 25 and 170. With the Seismic inverted index, it reaches over 97% recall against exact search in about 380 microseconds per query, single-threaded. Linkup says inflating vector size could add 1 to 2 BEIR points, but it chose to stay sparse.
Key Takeaways
- SPARSEUP is Linkup Research’s first open model: a 149M-parameter sparse encoder under Apache 2.0.
- It scores 56.4 nDCG@10 on BEIR-13, top among public sparse encoders under 150M, per Linkup.
- 3 fixes drive it: a logit shift of 15, top-12 expansion per token, and case folding.
- With identical data, it trails DenseOn by 1.52 points and LateOn by 2.5 on BEIR-13.
- It reaches over 97% recall in about 380µs per query with Seismic on MS MARCO.
Check out the Model Weights and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us.
More in Generative AI & Models
All →- TypeSafe AI says Jev is 193.6x faster than Claude Sonnet 5 · 3 src
- OpenAI founder launches Jev model promising lower cost and faster processing · 1 src
- Six Jev-inspired models released in two days, from Laya (421M params) to Kev-0.5B · 1 src
- xAI releases Grok Voice Transcribe 2.0 speech-to-text model · 2 src
- Alibaba open-sources Damo Radar model to detect 146 abdominal conditions · 1 src
Comments
via GitHub Discussions