Llama.cpp achieves up to 42x faster prompt lookup drafting
Benchmarks were run on an Apple M4 Pro (14 cores, 48 GB RAM) using the WikiText‑103 corpus (541 MB) and smaller subsets (25 MB‑200 MB). Median latency per drafted token and memory figures were measured over three runs.
Key points
- Up to 42× faster prompt‑lookup drafting reported on Apple M4 Pro hardware
- Switching outer map to ankerl::unordereddense segmentedmap drives most speed gains
The work builds on earlier contributions by Daniel Lemire, Martin Ankerl, and a PR from Johannes Gaessler that added a static cache to llama.cpp. All code and results are publicly available in the repository, and the author emphasizes that acceptance rates remain unchanged compared with the original implementation.
The story so far
2 episodes →- Llama.cpp achieves up to 42x faster prompt lookup draftingthis story
42x Faster Prompt Lookup Drafting in llama.cpp
jadidbourbaki.github.io · 27 September 2026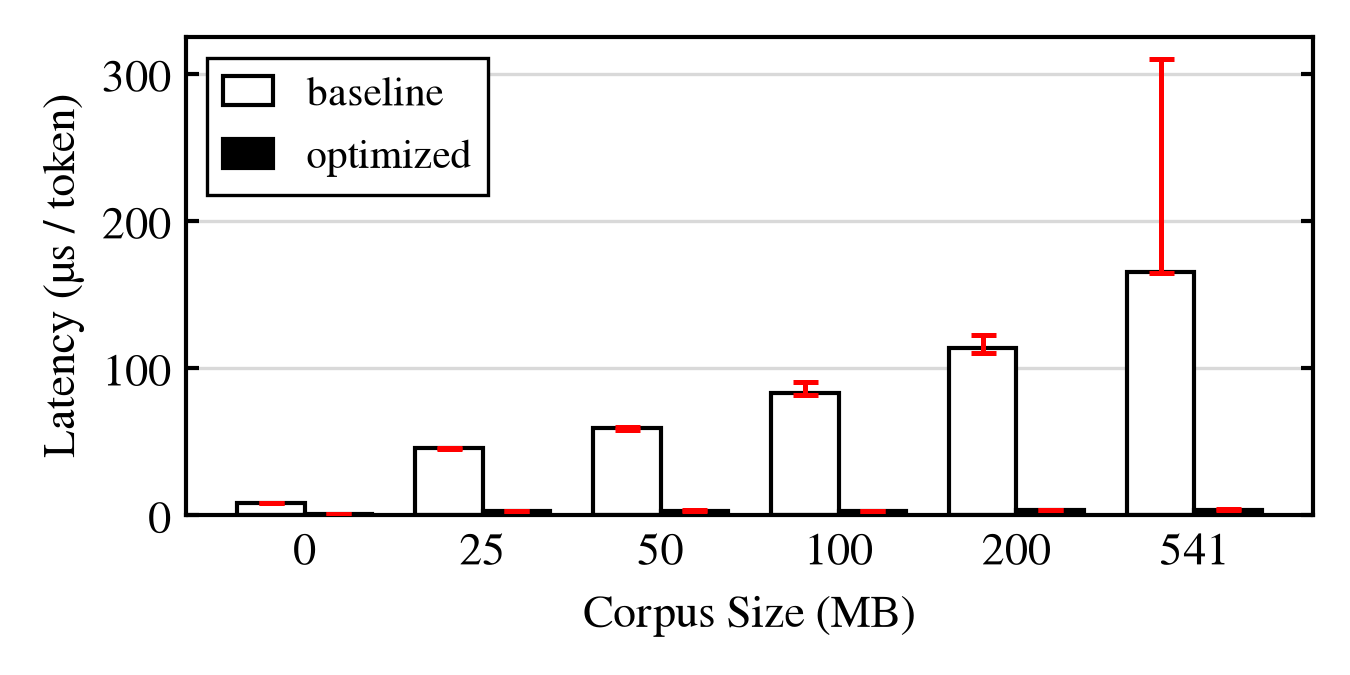
Loading the full article…
This text was published by jadidbourbaki.github.io and written by Hayder Tirmazi. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
1source- Reddit discussionreddit.com
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- Anthropic's Claude begins 'dreaming' to reorganize memory in tests · 1 src
- John Langford quits Microsoft, declares AI Frontiers over · 1 src
- Anthropic releases study on Claude usage in scientific research · 3 src
- MIT and BASF release CheMeleon for low-data molecular prediction · 2 src
- Anthropic tests Claude agents in EVE Online trading and sabotage detection · 1 src
Comments
via GitHub Discussions