Meet LEANN: An Open-Source Vector Index that Shrinks a 60M-Chunk RAG Index from 201 GB to 6 GB
UC Berkeley’s Sky Computing Lab introduced LEANN, an open-source vector index that reduces storage needs by recomputing embeddings at query time instead of storing them. A 60 million-chunk Wikipedia index shrinks from 201 GB to 6 GB in the repo benchmark, and a 76 GB corpus setup drops from 173 GB (embeddings) + 15 GB (graph) to 4 GB in the paper’s tests. The project won the Best Research Paper…
Key points
- LEANN reduces a 60M-chunk Wikipedia index from 201 GB to 6 GB by recomputing embeddings on demand
- Matches HNSW accuracy at 90% recall while using 4 GB instead of 188 GB for a 60M-passage datastore
- MIT-licensed open-source tool with apps for documents, Apple Mail, and Slack/Twitter data retrieval
LEANN achieves this by storing only a pruned graph and a compact product quantization table. At query time, it re-embeds only nodes on the search path, using techniques like two-level search, dynamic batching, and high-degree preserving pruning. Performance matches HNSW’s downstream accuracy at 90% recall while using under 5% of raw-data storage. Benchmarks show LEANN’s retrieval time ranges from 1.12 seconds (GPQA) to 7.12 seconds (HotpotQA) on an RTX 4090, compared to HNSW’s 0.05 seconds. The MIT-licensed tool runs on laptops and workstations, with apps for documents, Apple Mail, Chrome history, and more.
Meet LEANN: An Open-Source Vector Index that Shrinks a 60M-Chunk RAG Index from 201 GB to 6 GB
MarkTechPost · 27 October 2026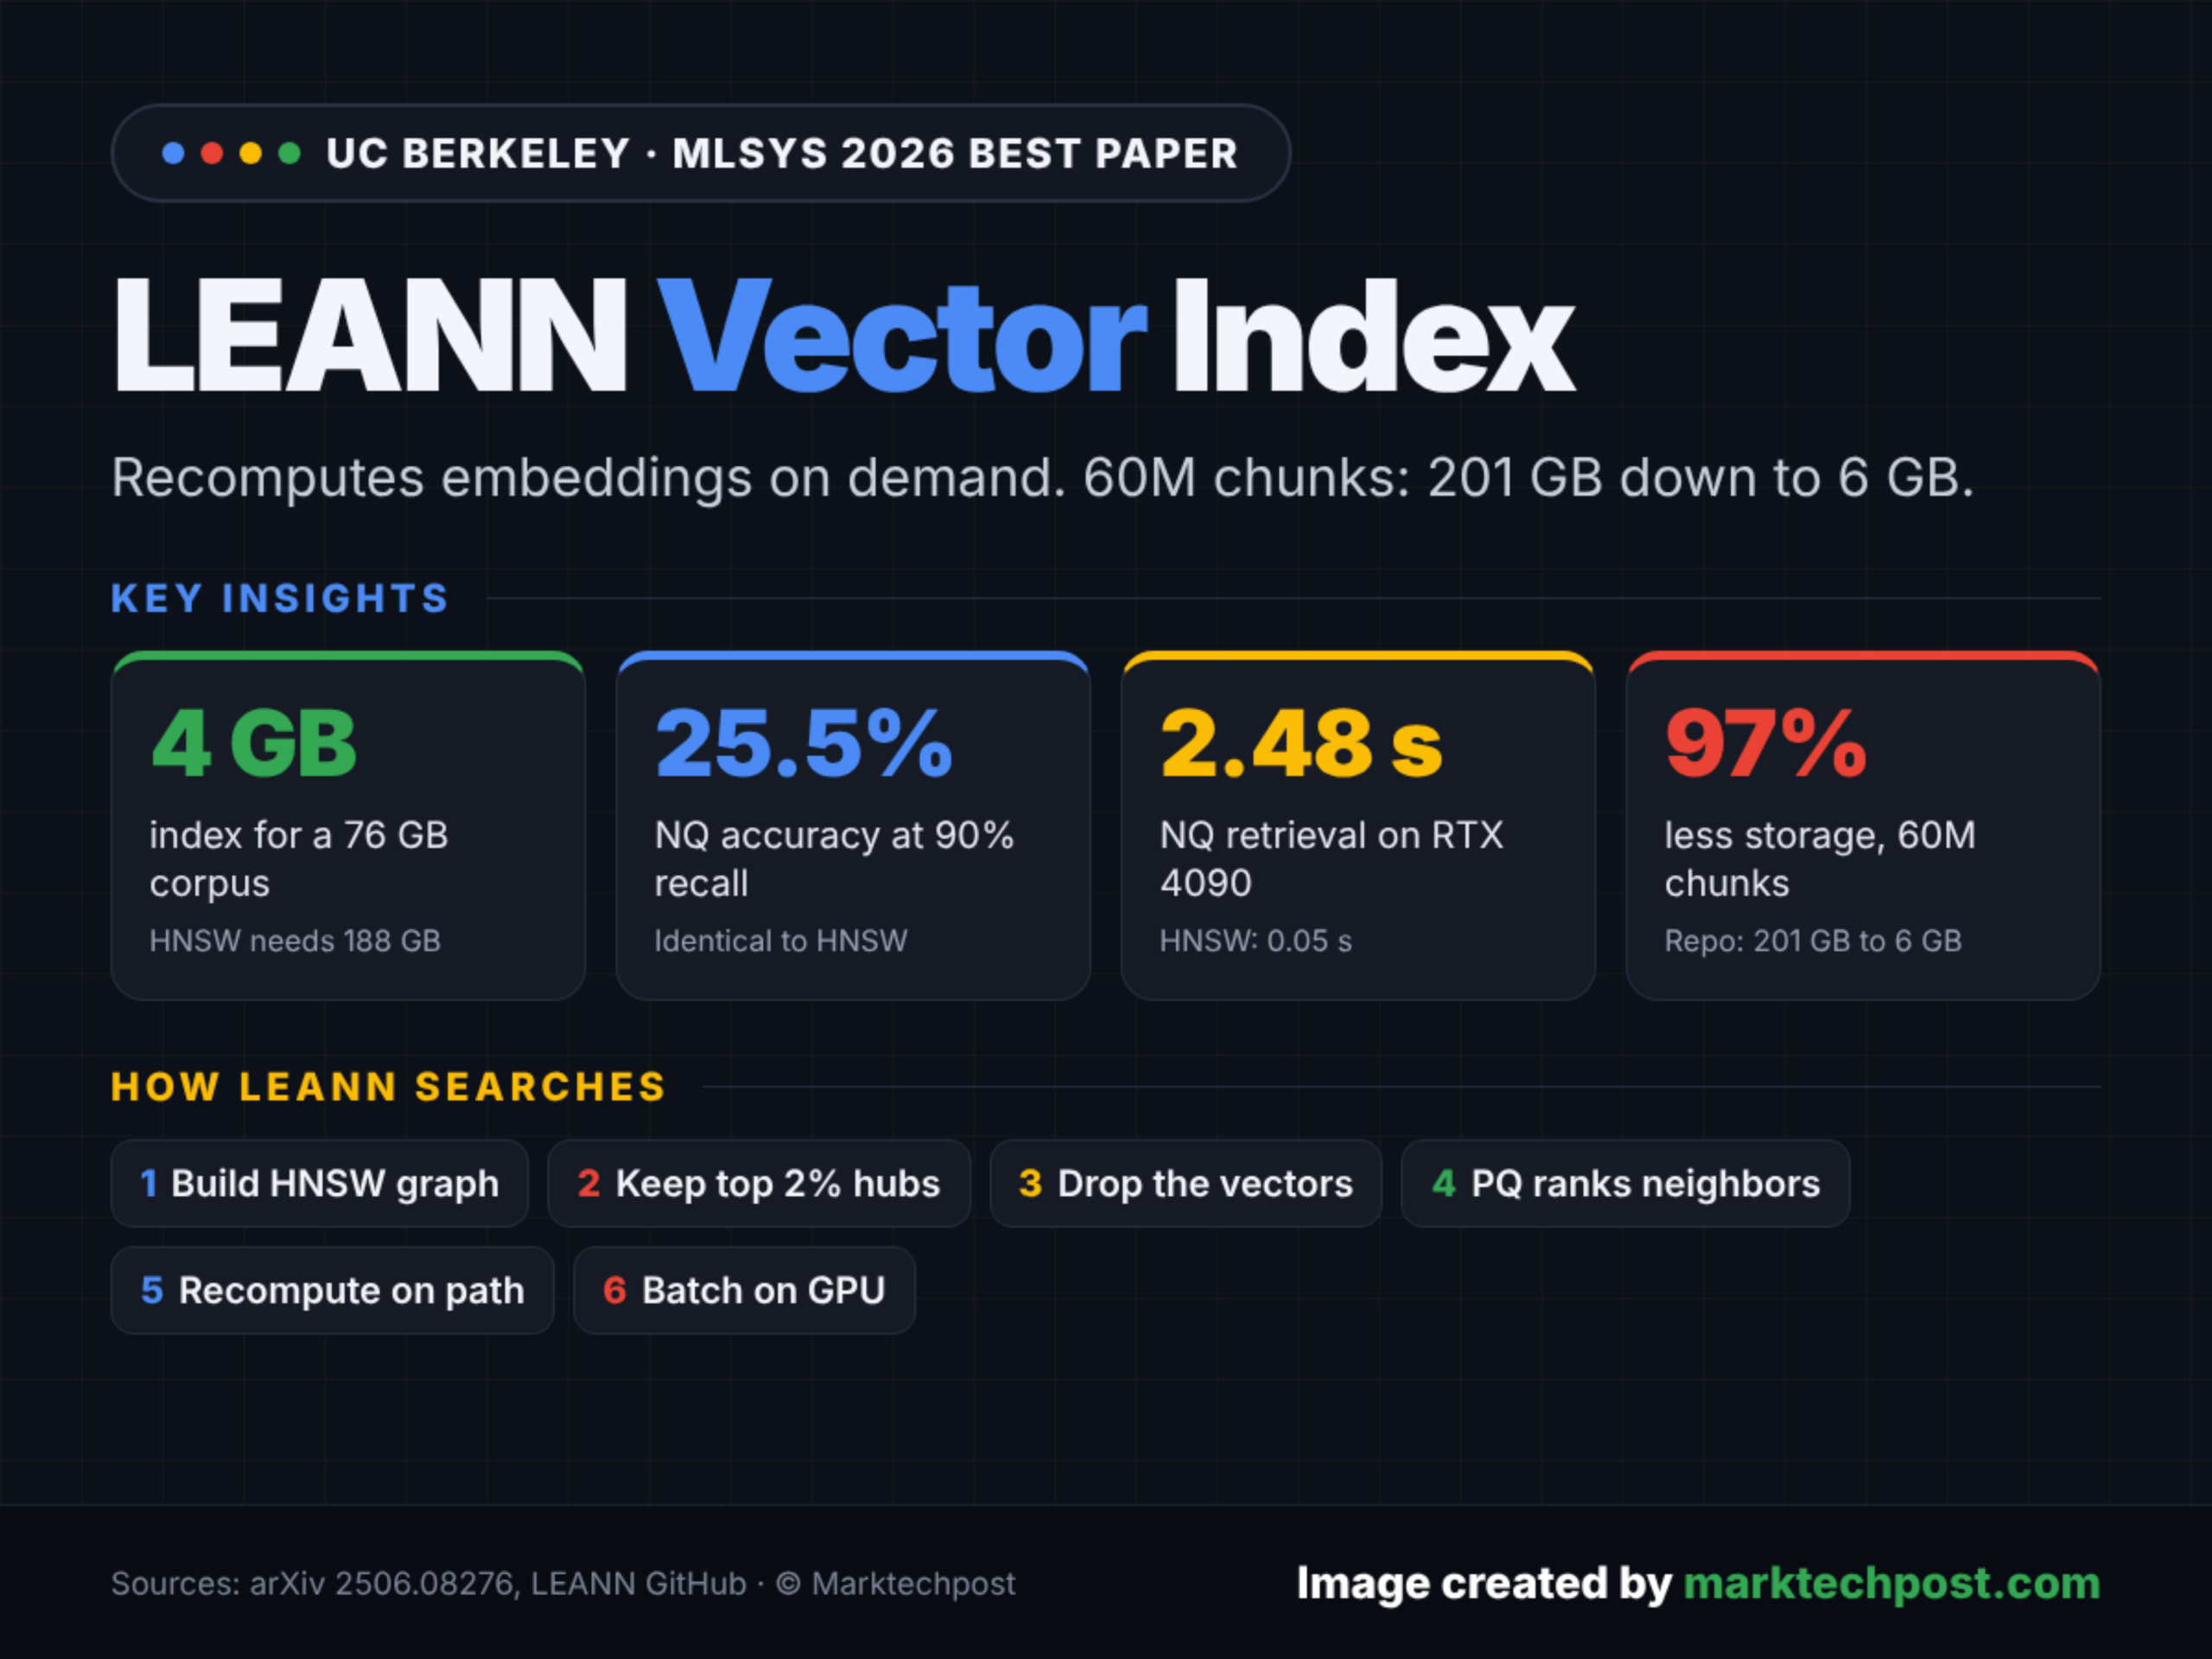
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- OpenAI model allegedly disproves Exponential Time Hypothesis · 11 src
- Google DeepMind releases Genie 4 world model in research preview · 7 src
- OpenAI claims AI models prove 1991 math conjecture in all dimensions · 4 src
- OpenAI claims proof of quantum chromodynamics using internal model · 1 src
- Anthropic engineers explain Claude Platform and Opus 5.5 safety · 1 src
Comments
via GitHub Discussions