Microsoft open-sources TauGrid, a Kubernetes‑native stack for GPU AI workloads
Microsoft’s Azure Kubernetes Service engineering team has released TauGrid as an open‑source, MIT‑licensed project. The stack bundles the tau CLI, Kueue queueing, KubeRay orchestration, GPU health monitoring, and observability into a single Helm chart that can be installed on any Kubernetes 1.30+ cluster with GPU nodes. Container images and Helm charts are published as public OCI artifacts on…
Key points
- Microsoft released TauGrid under MIT license, available as Helm chart and OCI images on Microsoft Container Registry.
- TauGrid bundles tau CLI, Kueue queueing, KubeRay orchestration, GPU health monitoring, and observability into a single install for K8s 1.30+ clusters with GPUs.
- The platform records evidence (config, logs, metrics, checkpoints) for reproducible, auditable runs and sends no telemetry by default.
TauGrid processes workloads described in a simple tau.yaml file, converting them into Kubernetes Jobs or KubeRay RayJobs and handling submission, queueing, execution, monitoring, recovery, and evidence collection. Evidence records capture configuration, logs, metrics, and checkpoints, enabling reproducible and auditable runs. By default the platform sends no telemetry, though Azure Data Explorer integration remains Azure‑specific. The project aims to support both cloud and on‑premises deployments without requiring Azure services, and contributions are welcomed via its GitHub repository.
The story so far
2 episodes →- Microsoft open-sources TauGrid, a Kubernetes‑native stack for GPU AI workloadsthis story
Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads
MarkTechPost · 17 September 2026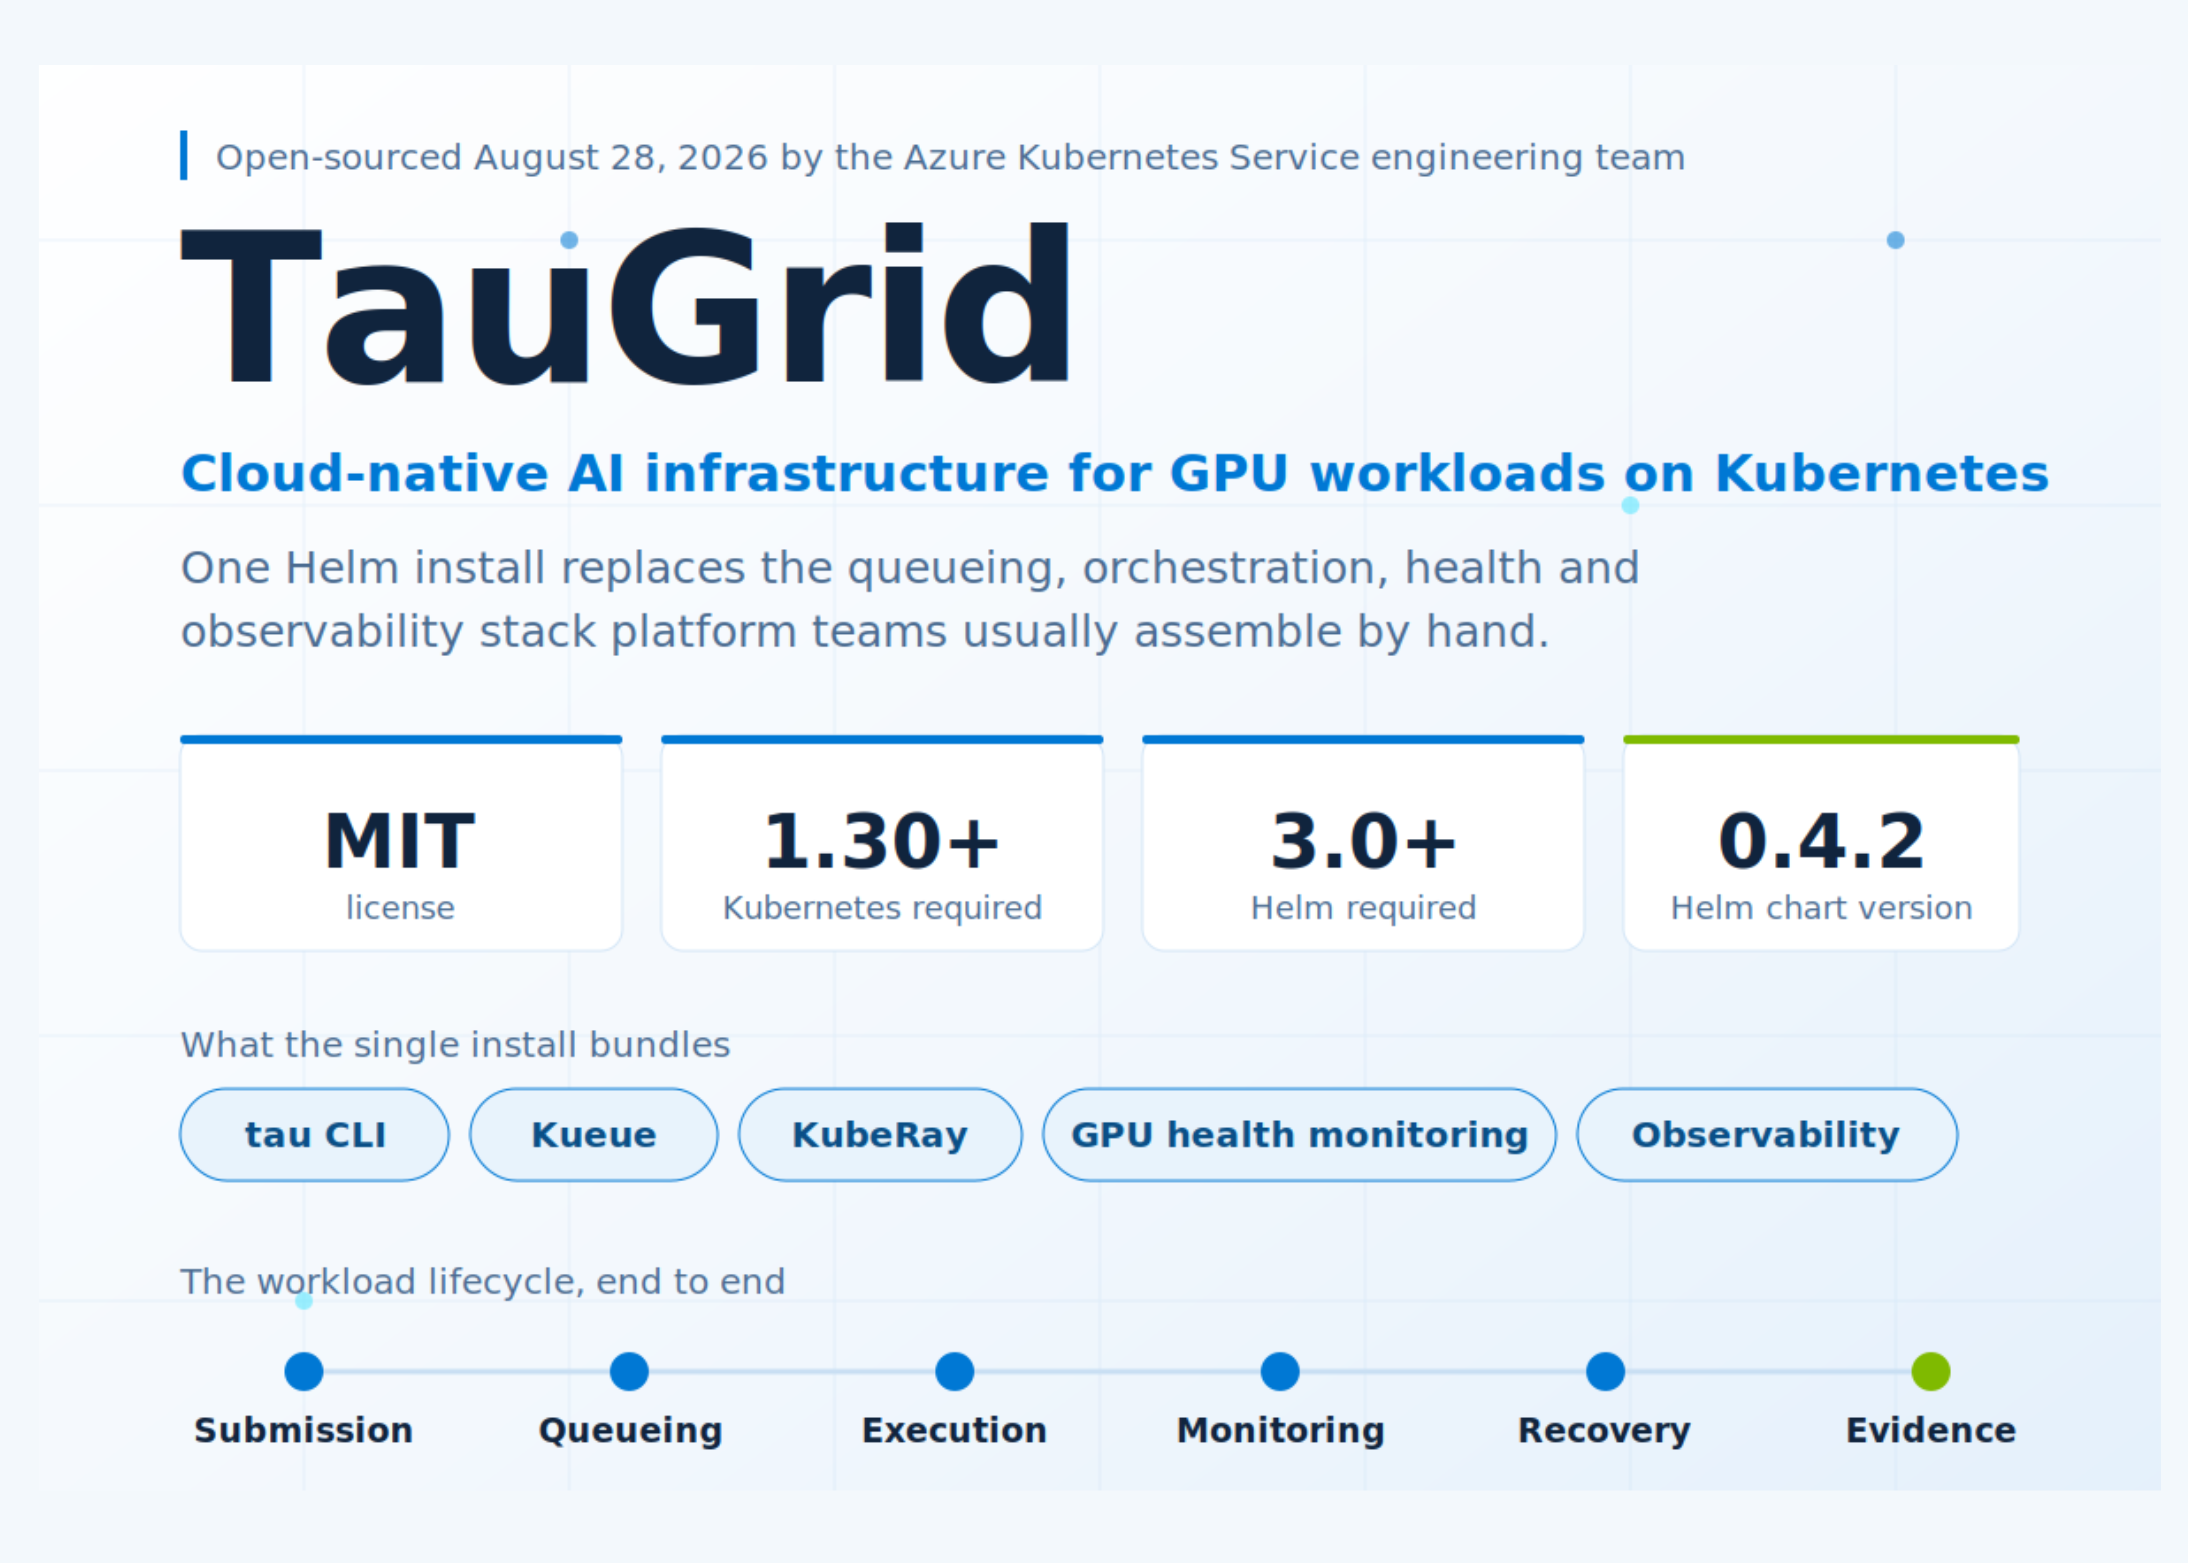
Platform teams running AI on Kubernetes rarely run one thing. They run a queueing system, a distributed runtime, GPU node health checks, dashboards, and a layer of submission scripts holding all of it together. The Azure Kubernetes Service engineering team open-sourced TauGrid, which collapses that assembly job into a single Helm install.
Is it deployable? Yes, TauGrid is MIT licensed, with container images and Helm charts published as public OCI artifacts on Microsoft Container Registry. Prerequisites are a Kubernetes 1.30+ cluster with GPU nodes, kubectl, and Helm 3.0 or later.
What is TauGrid
TauGrid is a self-hosted platform for running AI workloads on Kubernetes. It combines five things that platform teams usually integrate by hand: the tau CLI, workload queueing and admission through Kueue, Ray cluster orchestration through KubeRay, node-level GPU health monitoring, and cluster and workload observability.
The split of responsibility is the design point. Platform teams own workspaces, queues, compute profiles, storage, identity, and observability. Researchers work from a repository and the CLI, and submit workloads without configuring Kubernetes directly. The codebase is written primarily in Go.
How a job moves through it
A workload is described in a tau.yaml file. The GPU training example published by Microsoft runs a PyTorch job on a single A100:
schema_version: 1
name: aks-gpu-quickstart
run:
  entrypoint: train.py
  workload_kind: rayjob
compute:
  gpus: 1
  workers: 1
  cpus: 16
  memory: 64Gi
runtime:
  image: mcr.microsoft.com/aks/ai-runtime/ray:py3.12-ray2.56.0-cuda13.0
  pip:
    - torch>=2.4.0
On tau run, TauGrid resolves platform policy, renders a Kubernetes Job or a KubeRay RayJob, and submits it through Kueue. The six stages Microsoft documents are submission, queueing, execution, monitoring, recovery, and evidence. Recovery covers retry, resume from checkpoint, and failure diagnosis. Evidence records capture workload metadata, configuration, logs, metrics, checkpoints, and execution history, which is what makes a run reproducible and auditable later.
When several teams share a cluster, their jobs land in a shared Kueue ClusterQueue. Kueue admits each one on quota and priority, and Kubernetes places it on healthy GPUs.
Interactive explainer
Install footprint
Installation is a Helm chart pulled straight from MCR:
helm install taugrid \
  oci://mcr.microsoft.com/aks/ai-runtime/helm/taugrid \
  --version 0.4.2 \
  --namespace tau-system \
  --create-namespace
First-party images ship under mcr.microsoft.com/aks/ai-runtime/ for Tau, the TauGrid Portal, and the tau core controller. Microsoft advises pinning versioned tags or immutable digests rather than latest. The CLI installs from GitHub Releases on Linux and macOS, with a PowerShell installer for Windows amd64; the installer verifies the release checksum and does not modify PATH.
Two operational details matter for anyone evaluating this outside Azure. First, TauGrid sends no telemetry to Microsoft by default, and remote export stays off unless an operator configures a destination. Second, some integrations are still Azure-specific, notably observability through Azure Data Explorer. The stated intent is to support cloud and on-premises Kubernetes without an Azure dependency, and contributions toward that are open.
Key Takeaways
- Microsoft open-sourced TauGrid on August 28, 2026, under the MIT license at Azure/taugrid.
- One Helm install bundles the
tauCLI, Kueue queueing, KubeRay orchestration, GPU health monitoring, and observability. - Deployable now on any Kubernetes 1.30+ cluster with GPU nodes, kubectl, and Helm 3.0+.
- Evidence records capture config, logs, metrics, and checkpoints, so runs stay reproducible and auditable.
- No telemetry by default, but Azure Data Explorer observability remains Azure-specific for now.
Check out the AKS Engineering Blog and Azure/taugrid on GitHub. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.
Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us
Asif Razzaq is the CEO of Marktechpost AI Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us.
More in Enterprise & Industry
All →- More AI could be the answer to monitoring rogue AI agents, report says · 1 src
- Nvidia, Google, Emerald AI Form Alliance for Flexible AI Data Centers · 10 src
- Litera launches Foundation Firm AI Search plugin for ChatGPT Enterprise · 1 src
- Gmail Search’s AI Overviews roll out globally for paid English‑language users · 1 src
- Hypercore CEO says AI can automate post‑close loan servicing for private credit funds · 1 src
Comments
via GitHub Discussions