NVIDIA boosts MoE inference speed 42.5% on DGX Spark with Ling-3.0-flash
NVIDIA detailed three optimizations for Mixture-of-Experts (MoE) inference on its DGX Spark system, improving decode throughput by 42.5% for Ant Group’s inclusionAI Ling-3.0-flash model. The 124B-parameter model, with 5.1B active parameters per token, ran on a single DGX Spark (GB10, 128GB unified memory) using batch size one. The optimizations—Humming MXFP4 MoE kernels, an FP8 output layer, and…
Key points
- NVIDIA’s optimizations boost Ling-3.0-flash GSM8K decode throughput 42.5% on DGX Spark
- Humming kernels and FP8 LM head cut per-step costs; speculative decoding reduces step count
- Model activates 5.1B of 124B parameters per token, runs on single DGX Spark with 128GB memory
The optimizations address memory bottlenecks: Humming kernels compile at runtime for specific shapes, cutting MoE computation time, while FP8 quantization halves reads of the LM head. Speculative decoding drafts three tokens and verifies four at once, though it requires careful integration to avoid silent fallbacks. NVIDIA warns that combining FP8 LM head and speculative decoding demands a shared LM-head module. Ling-3.0-flash, released under the MIT license, is designed for low per-token costs via sparse MoE and hybrid linear attention, with native 256K context support. Its benchmarks include 56.6 on SWE-Bench Pro and 93.2 on MathArena AIME 2026.
The story so far
3 episodes →- NVIDIA boosts MoE inference speed 42.5% on DGX Spark with Ling-3.0-flashthis story
NVIDIA Shows 3 Ways to Speed Up MoE Inference on DGX Spark, Lifting Ling-3.0-flash Throughput 42.5%
MarkTechPost · 3 November 2026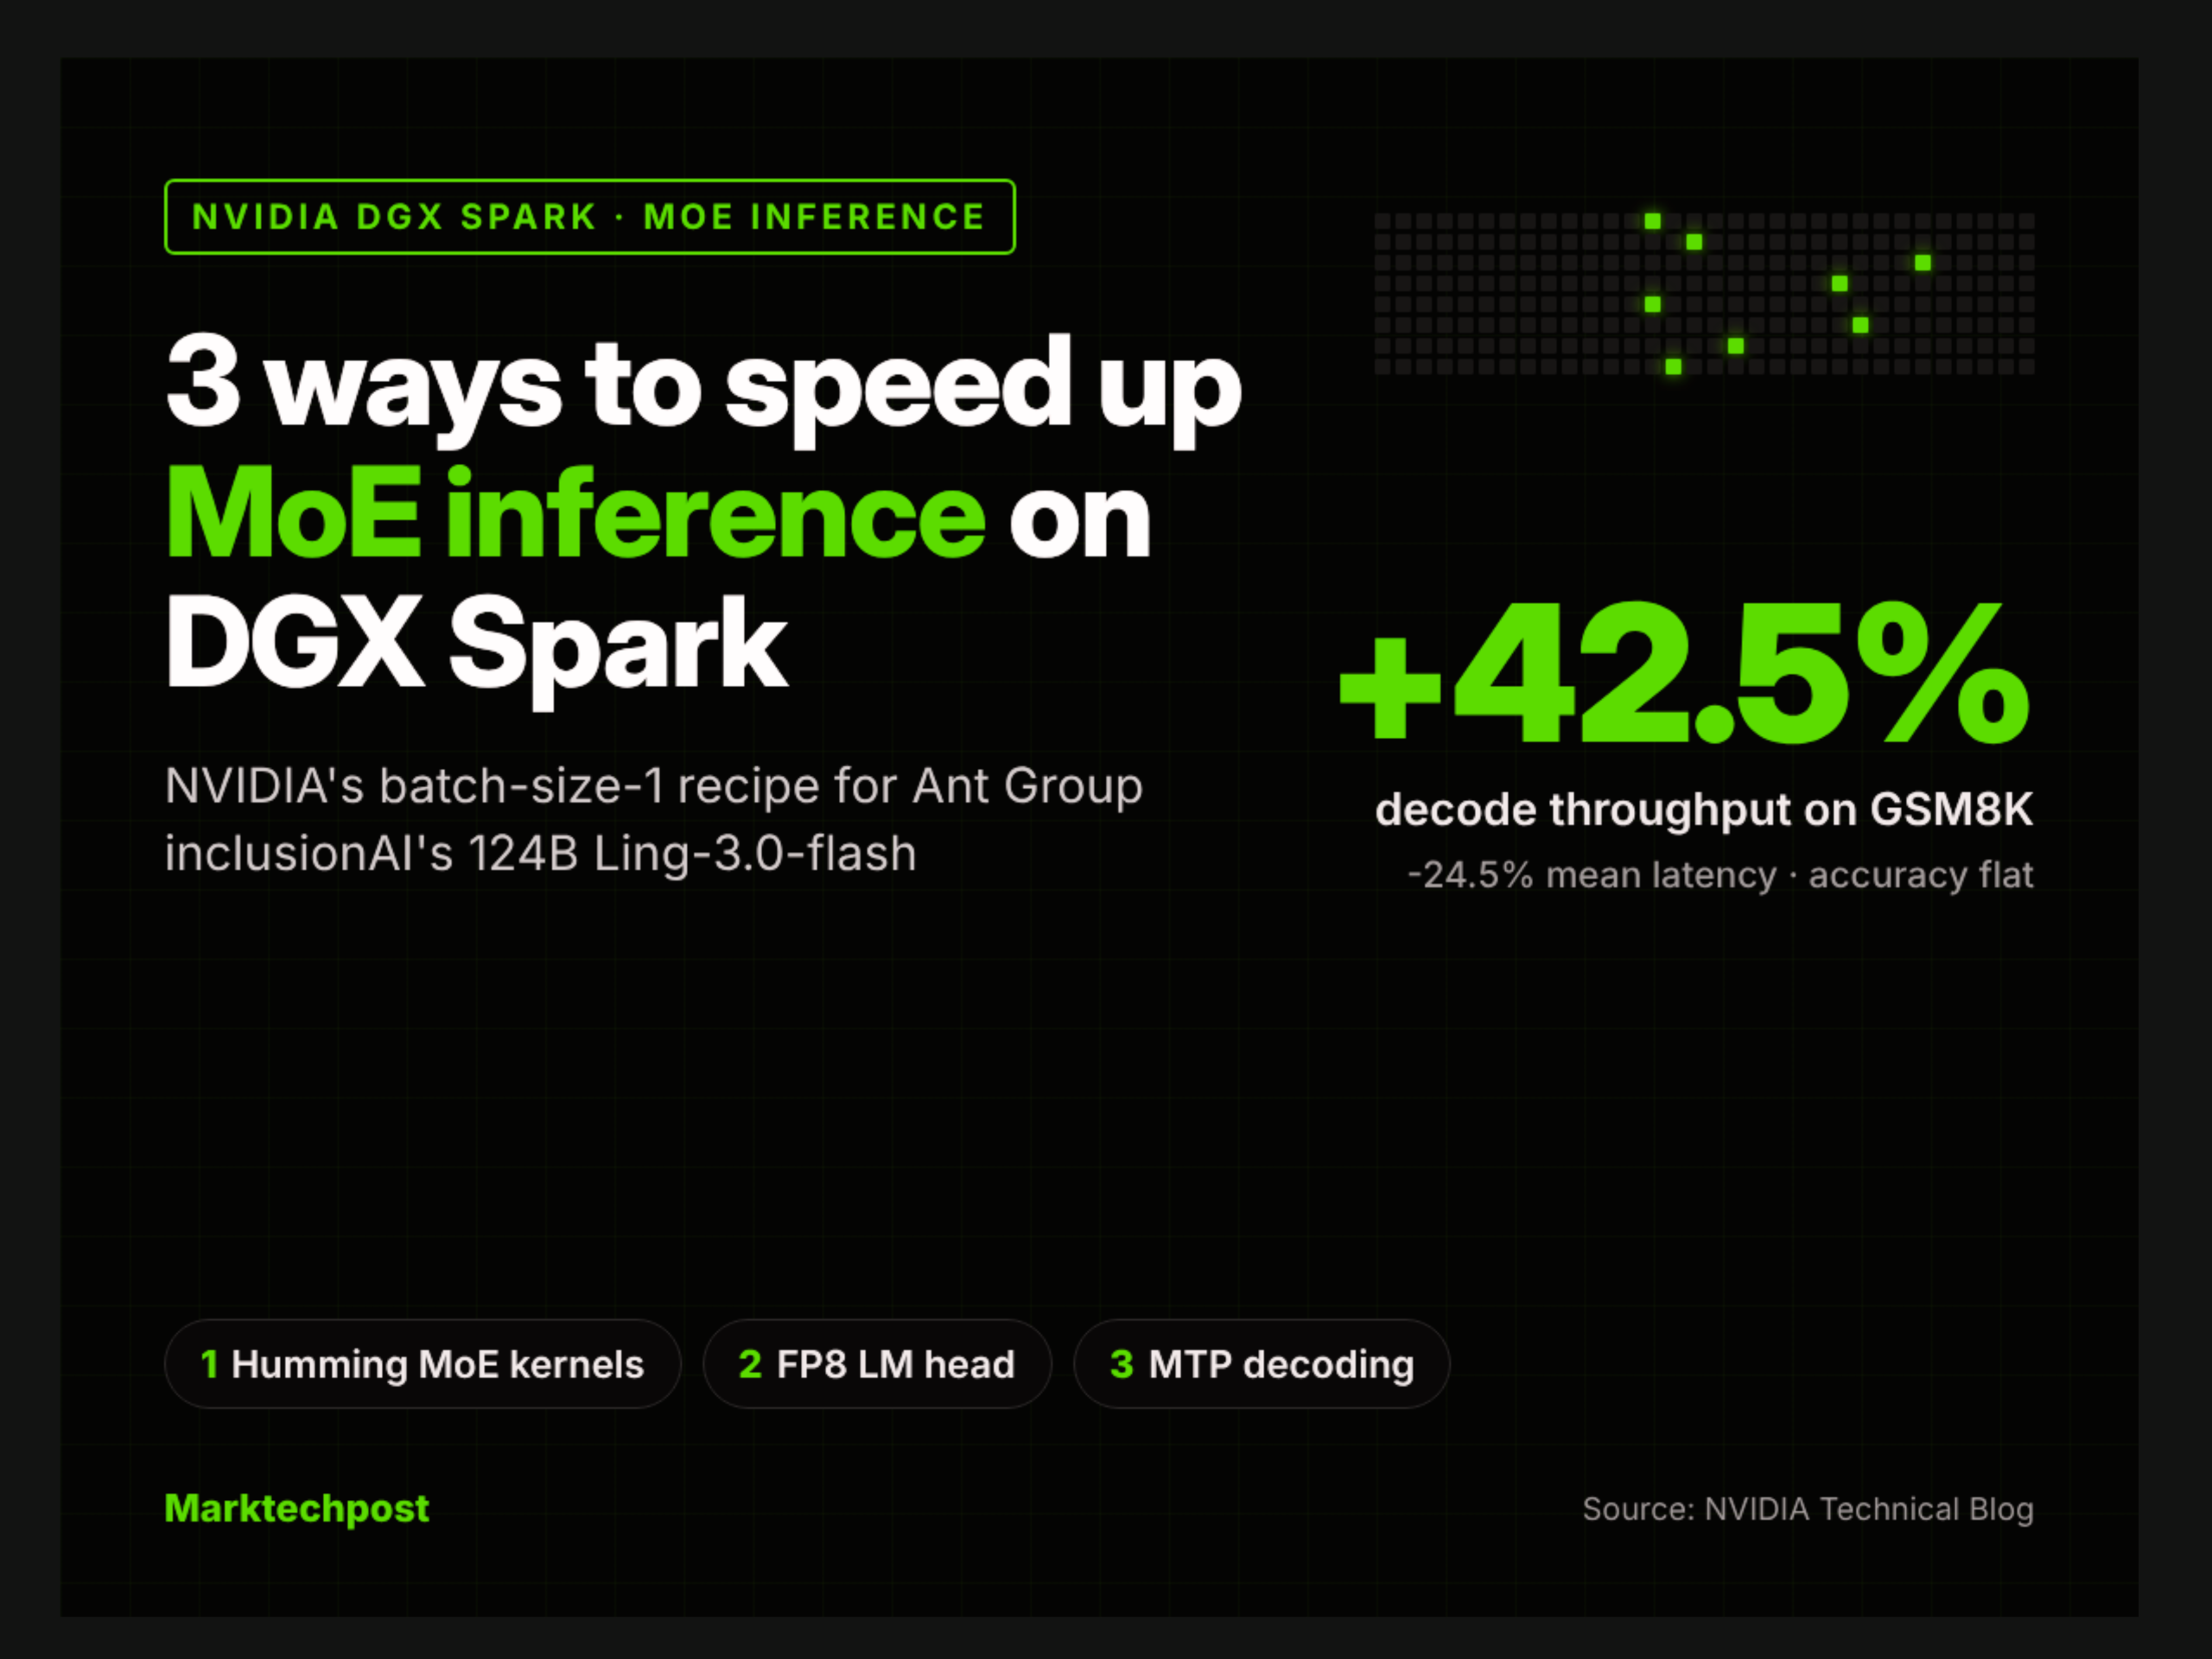
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Hardware & Compute
All →- NTT DATA opens 12MW Jakarta data center and launches APN Connect photonic network · 1 src
- NVIDIA adds DLSS 5 to RTX Remix for older games on October 23 · 1 src
- Amazon Echo Show users can disable AI-generated 'Created For You' slides · 1 src
- WhiteFiber buys two North Carolina sites for $60 million · 1 src
- Revolut cuts AI coding costs 10x by self-hosting GLM-5.3 instead of Claude · 1 src
Comments
via GitHub Discussions