OpenAI, Google, Microsoft propose common robots.txt rule to block AI training
OpenAI, Google, Microsoft, and Anthropic announced on October 30, 2026, a draft policy to let website owners signal whether their content can be used for AI training via an updated robots.txt file. The mechanism, still in development by the IETF, would allow publishers to add a line like Disallow: / under User-Agent: usageai-training to refuse training access—though it does not yet block all AI…
Key points
- OpenAI, Google, Microsoft, and Anthropic propose a draft robots.txt rule to block AI training on websites
- Publishers can add `User-Agent: usageai-training Disallow: /` to refuse training access, but no company enforces it yet
- Implementation timelines vary: OpenAI aims for months, Google and Microsoft for 2027, Anthropic is actively supporting
The move addresses growing concerns among bloggers and publishers about unauthorized use of their content for training models like ChatGPT. However, the mechanism does not resolve copyright disputes or guarantee compliance from all crawlers. Users on platforms like note may also face limitations, as they often lack direct access to edit robots.txt files. The proposal distinguishes AI training opt-outs from search engine crawling rules, clarifying that refusing training does not necessarily remove content from search results—though some AI-generated search features may still reference it.
The story so far
2 episodes →- OpenAI, Google, Microsoft propose common robots.txt rule to block AI trainingthis story
[Latest AI News] Preventing AI from training on your articles!? OpenAI, Google, and others to adopt new common rules
note.com · 1 November 2026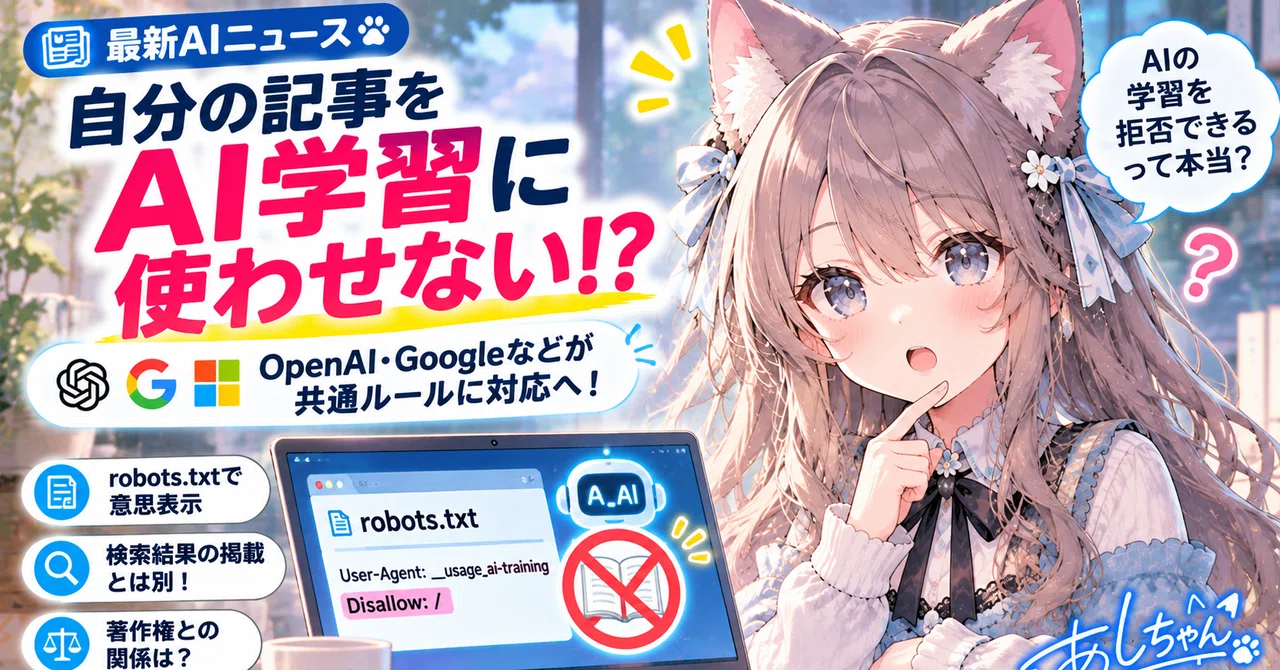
Loading the full article…
This text was published by note.com and written by AI編集長あしちゃん. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Policy & Regulation
All →- OpenAI plans post-midterm PR blitz to rebrand data centers as 'AI compute campuses' · 6 src
- Palantir’s NHS data platform reportedly unused by 29 trusts that claim benefits · 1 src
- Anthropic warns AI risks in IPO filing as it prepares for record stock listing · 2 src
- Google DeepMind's PlanAssist to expand to 12 more UK councils · 1 src
- Anthropic restricts Opus 5.5 from cloning video games · 1 src
Comments
via GitHub Discussions