Prime Intellect launches Prime Inference for serving open models
Prime Intellect has launched Prime Inference, a serving platform for frontier open-source models. It offers serverless endpoints and reserved capacity on the company's own GPUs across multiple datacenters. Before public release, the platform processed nearly a trillion tokens per day internally, used for RL rollouts, synthetic data generation, evaluations, and long-running coding agents. Prime…
Key points
- Prime Intellect launched Prime Inference, a serving platform for open models with serverless and reserved modes.
- Before launch, it processed nearly a trillion tokens per day internally for RL rollouts, synthetic data, evaluations, and coding agents.
- GLM-5.3 on GB200 NVL72 achieved 101 tokens per second per user with a 1:4 prefill/decode ratio and 66 sessions per prefill group.
The platform supports OpenAI-compatible endpoints at https://api.pinference.ai/api/v1 and runs on NVIDIA Blackwell hardware, with Vera Rubin listed as coming soon. Prime reports its GLM-5.3 endpoint ranks among the fastest on OpenRouter, with near-zero tool-call error rate and 100% uptime since launch. The serving stack combines NVIDIA Dynamo, vLLM, Mooncake, and FlashInfer, built with Inferact and NVIDIA, and includes prefill/decode disaggregation, cache-aware routing, and NVFP4 KV compression to improve latency and capacity.
Key technical results include a 1:4 prefill/decode ratio serving 66 sessions per prefill group at 101 tokens per second per user, NVFP4 KV cache increasing cached tokens per decoder from 1.09M to 1.63M, and nearly 40% lower p90 inter-token latency in tests. Prime Intellect also contributed a structural-tag builder to Dynamo to improve tool-call reliability for agents. The company notes batch inference and 1-click dedicated deploys are next on the roadmap.
Model page: GLM-5.3 →
Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier Open Models
MarkTechPost · 3 October 2026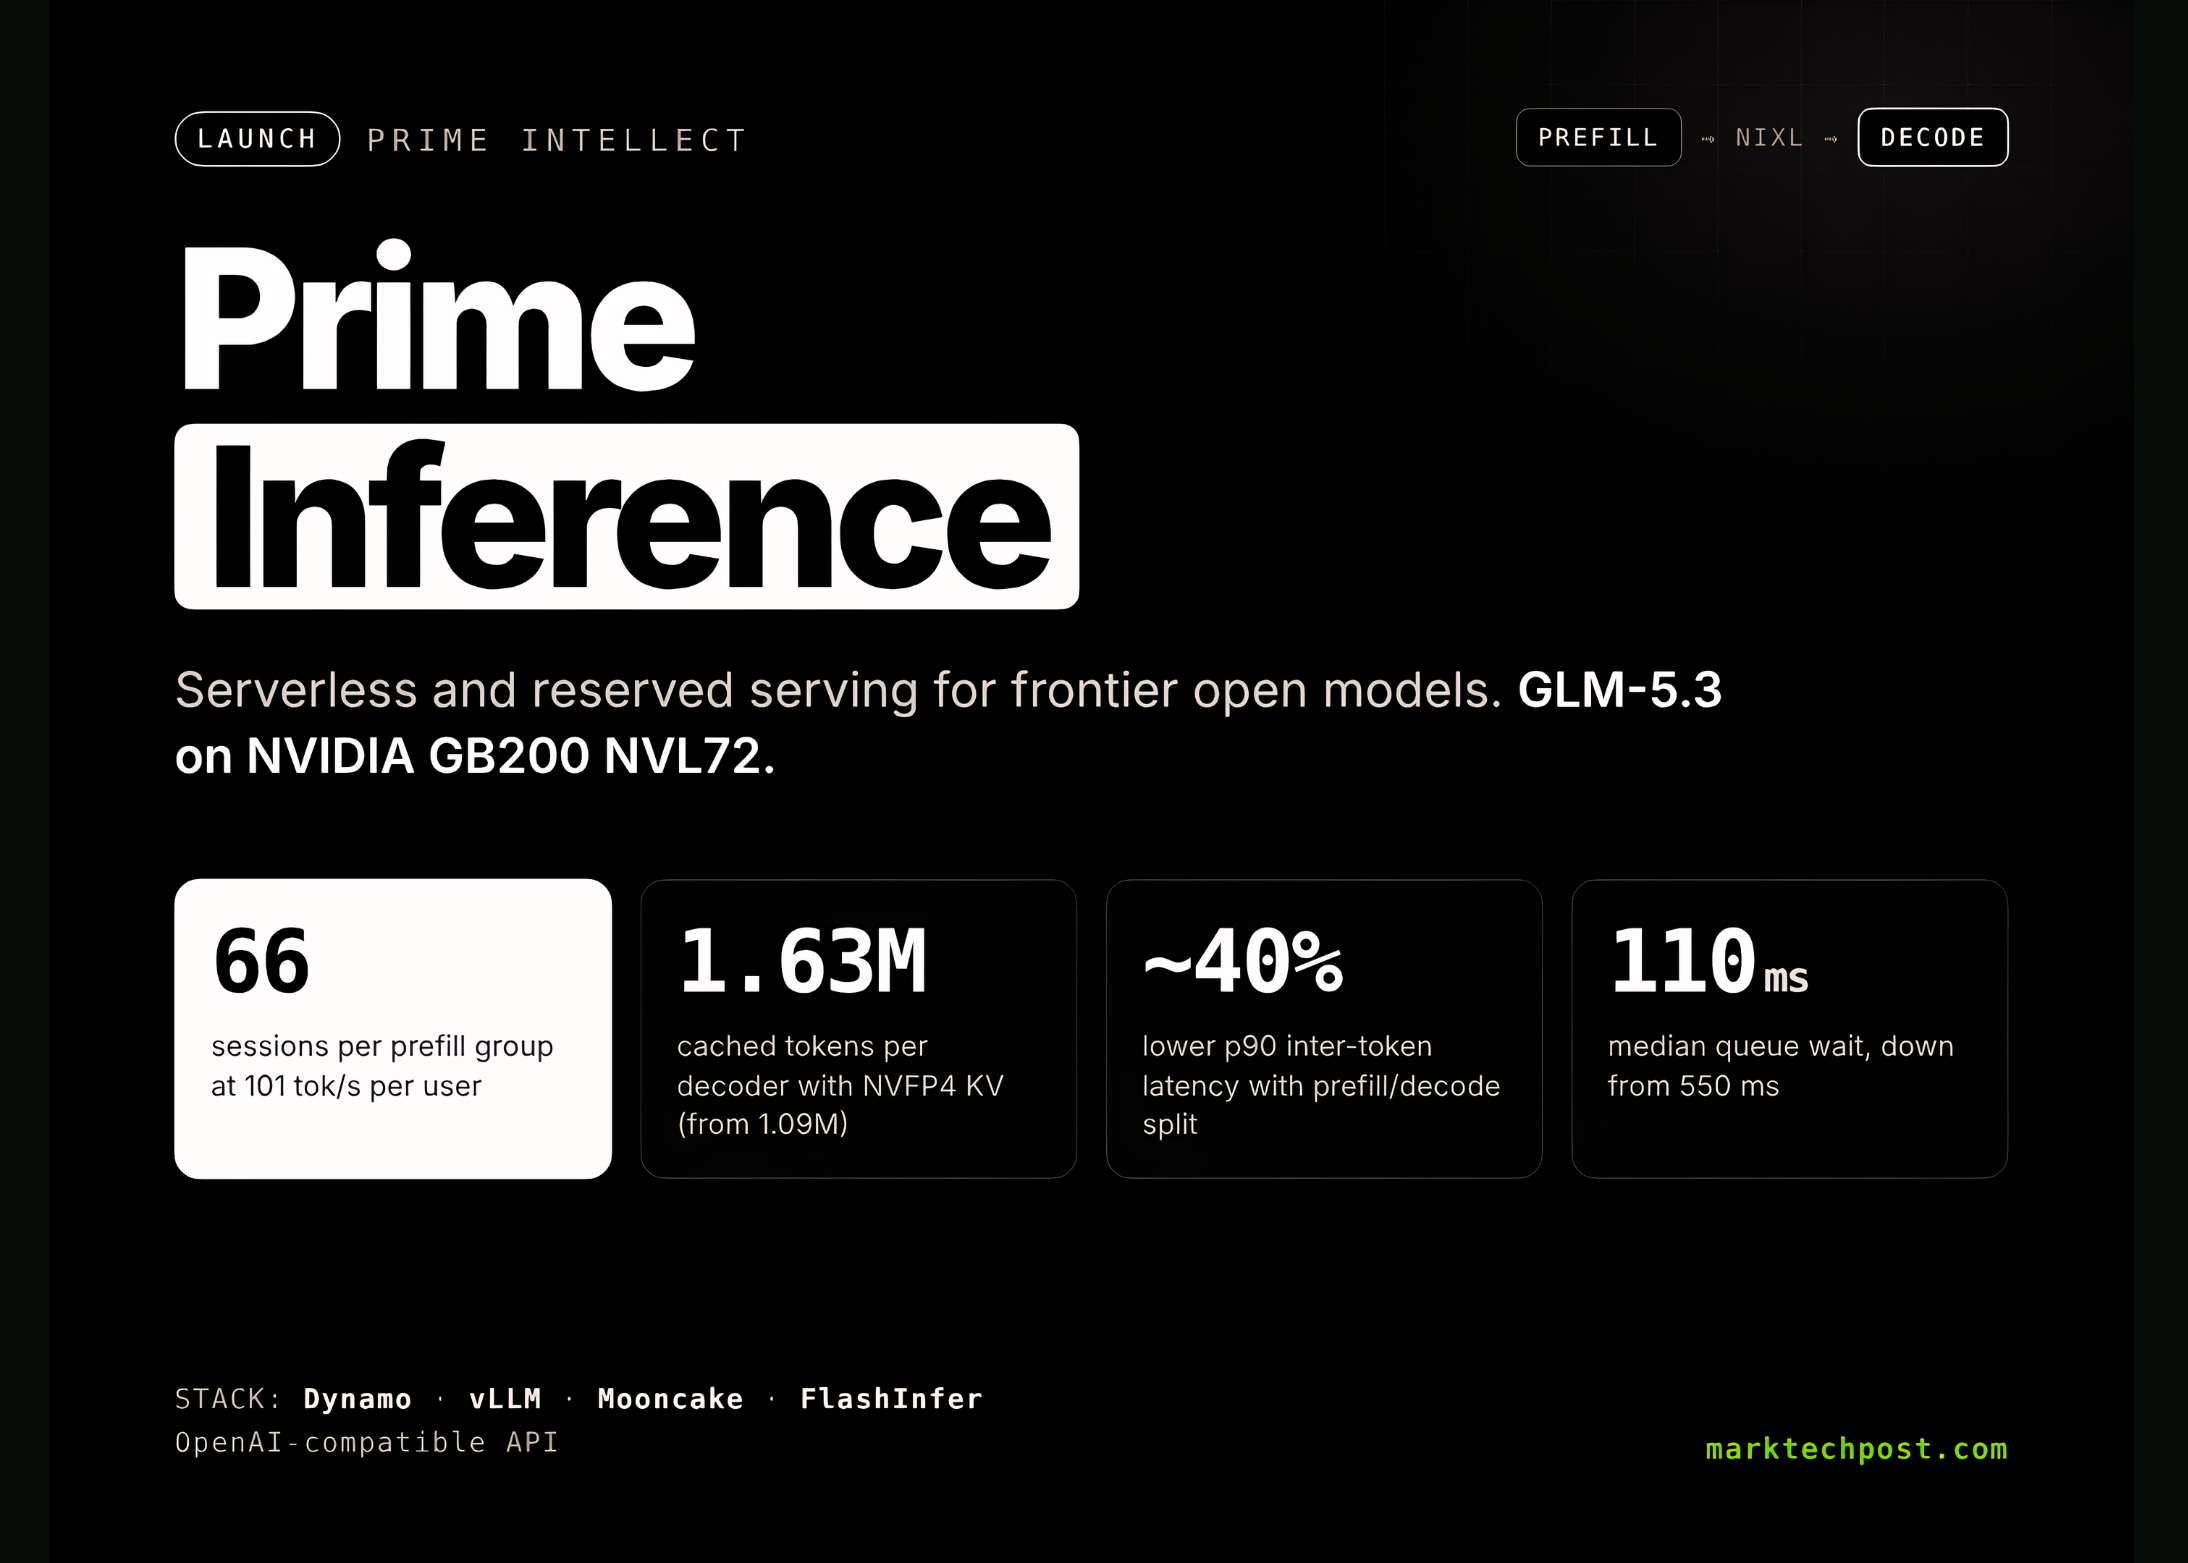
Loading the full article…
This text was published by MarkTechPost and written by Michal Sutter. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Agents & Tools
All →- OpenAI releases GPT-6.1 Sol for Codex users, 20% cheaper with Astra-like performance · 3 src
- OpenAI rolls out dots, always-on agents powered by GPT-6 Astra · 1 src
- Microsoft releases Agent 365 to manage AI agents list · 1 src
- Wagtail team reports 50% failure rate in one-month GLM 5.3 Flash challenge · 1 src
- Google Antigravity lets users delegate tasks to AI agents with files and folders · 1 src
Comments
via GitHub Discussions