Self-Attention explained: how transformers build context
Self‑attention is a mechanism that lets each token in a sequence build a context‑sensitive representation by weighting information from other tokens. The guide explains the concept, its boundaries, and why it matters for modern AI systems. It outlines a five‑stage operating map that separates the core transformation from the surrounding stack.
Key points
- self‑attention lets each token build a context‑sensitive representation by weighting other tokens
- five‑stage map: project, compare, scale, combine, repeat across heads and layers
- cost grows quickly with sequence length and attention weights are not a full explanation of reasoning
The stages are: 1) project tokens into queries, keys, and values; 2) compare each query with relevant keys; 3) scale and normalize the scores; 4) combine values using those weights; 5) repeat across heads and layers. The article stresses that each stage should have an owner, input, output, and a test, and that tracing uncertainty and resource use helps detect failures.
The main limitation is that cost grows quickly with sequence length and attention weights are not a full explanation of reasoning. The guide recommends evaluating self‑attention by measuring latency, memory, cost, and quality on representative slices, and by setting explicit stop conditions before deployment. Understanding these details helps teams optimize performance, security, and accountability in transformer‑based models.
What Is Self-Attention? The Mechanism That Powers Transformers
Unite.AI · 5 October 2026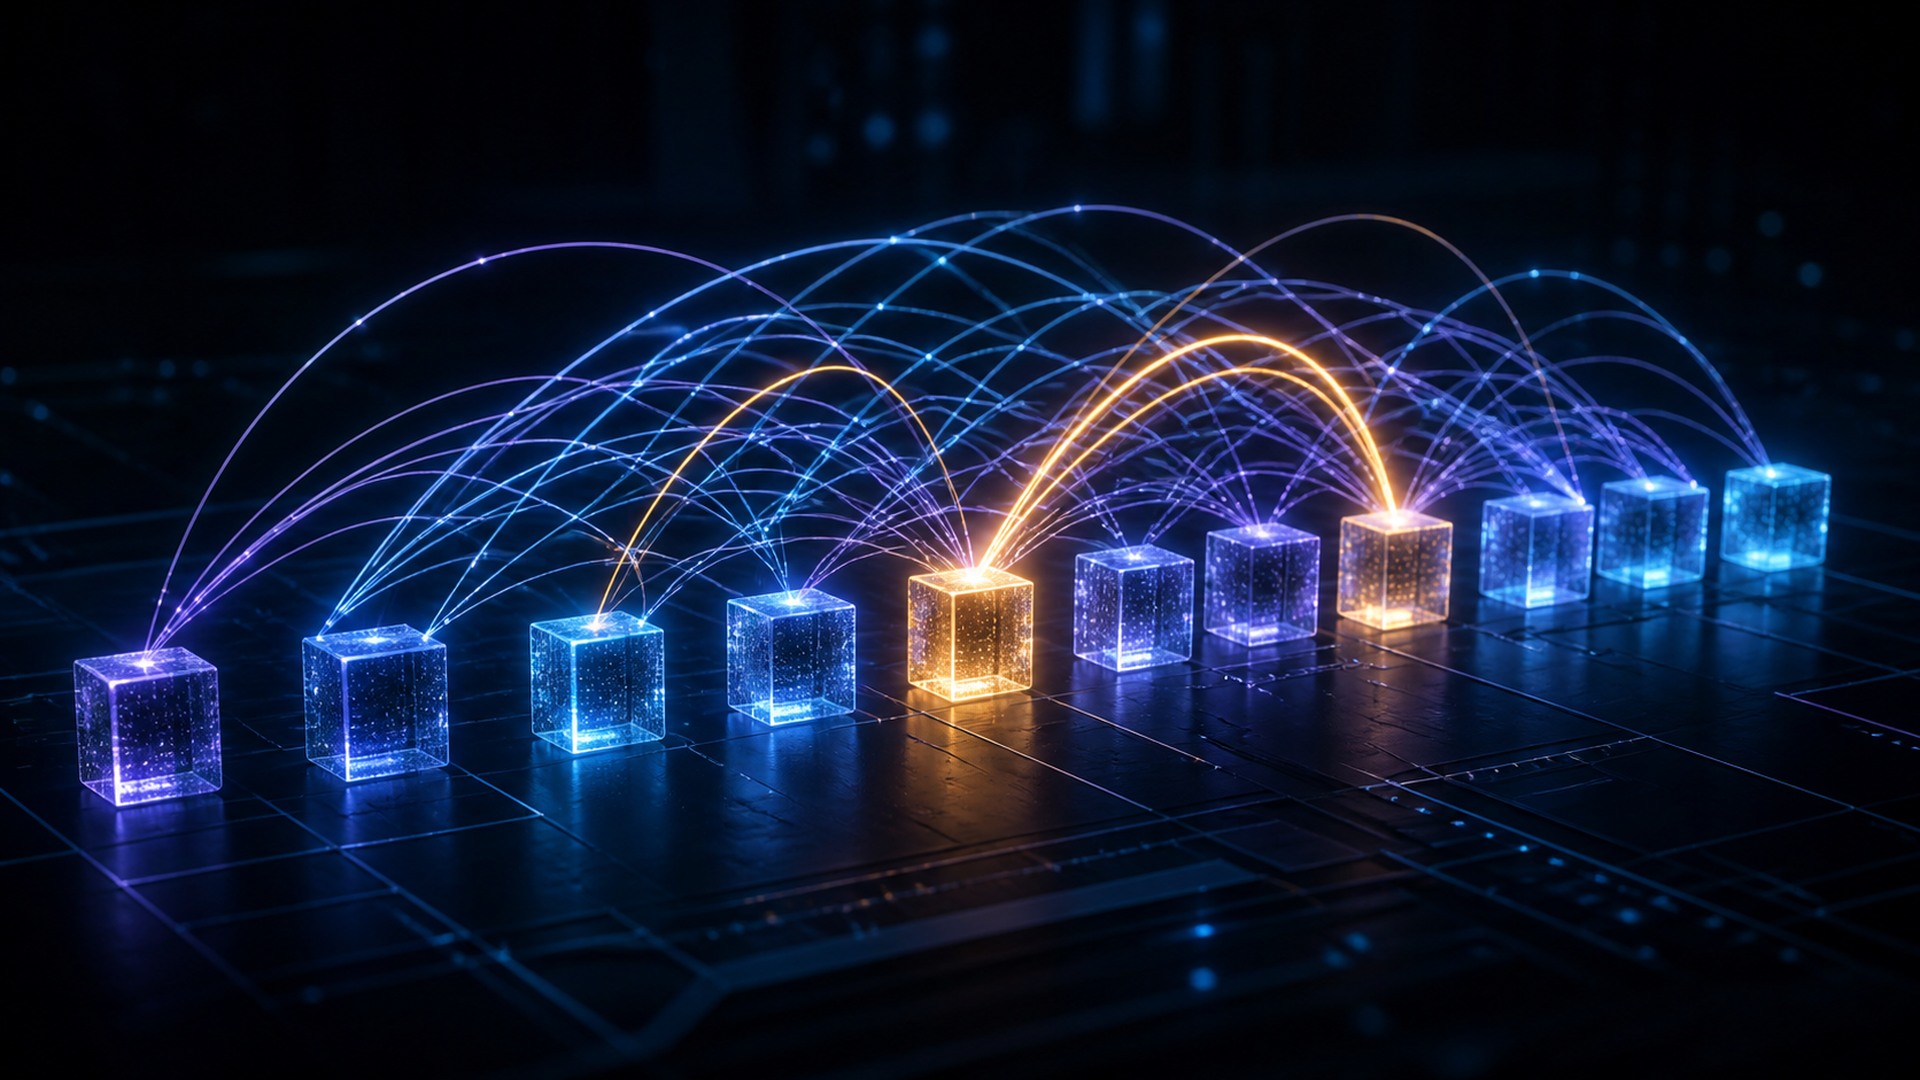
Loading the full article…
This text was published by Unite.AI and written by Jonas Reeve, Cognitive AI & AGI, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- Google VP Yossi Matias says AI’s biggest impact may come from intersecting fields · 1 src
- Researchers adapt speech language model for simultaneous translation using prefix supervision · 1 src
- Study finds inductive prompting most consistent for LLM generalization in temporal extraction · 1 src
- AraBERT-based framework reaches 96.88% accuracy on Arabic DP ambiguity · 1 src
- Researchers introduce APDMem hierarchical memory for long-context LLM assistants · 1 src
Comments
via GitHub Discussions