Wagtail team reports 50% failure rate in one-month GLM 5.3 Flash challenge
The Wagtail team documented a one-month experiment in September where they attempted to use only the open-source model GLM 5.3 Flash for their coding work. The challenge was technically a failure, as only 50% of the 2B tokens used went to the target model, with the remaining 1B tokens consumed by other models during the second half of the month. Total energy usage reached 35 kWh, significantly…
Key points
- Wagtail team used 2B tokens in September, with only 50% going to the target model GLM 5.3 Flash.
- A vibe-coded prototype consumed 450M tokens and $150 overnight due to incorrect model selection.
- Infrastructure issues and high demand forced the team to switch to DeepSeek V4.1 Flash and Qwen 3.8 Flash.
Key hurdles included the high cost of "vibe coding" a prototype for their Wagtail MCP server, which consumed 450M tokens and $150 almost overnight due to poor model selection. Additionally, the team faced infrastructure availability issues, noting performance degradation with GLM 5.3 Flash because of high demand on inference providers. This forced them to switch to alternative models like DeepSeek V4.1 Flash and Qwen 3.8 Flash. The team also emphasized the need to continue experimenting with a wide range of models to benchmark performance on specific tasks.
Despite the failure, the team identified several lessons for October, including the need for constant local usage measurement, better budgeting for experimentation, and improved prompt selection using multi-agent techniques. They concluded that while focusing on one or two efficient flash-tier models is viable for day-to-day work, the majority of AI inference should be measured by cost or energy use rather than token count. The team plans to share these findings at Wagtail Space 2026 in November.
Model page: DeepSeek-V4.1-Flash →
One month coding with GLM 5.3 Flash
wagtail.org · 2 October 2026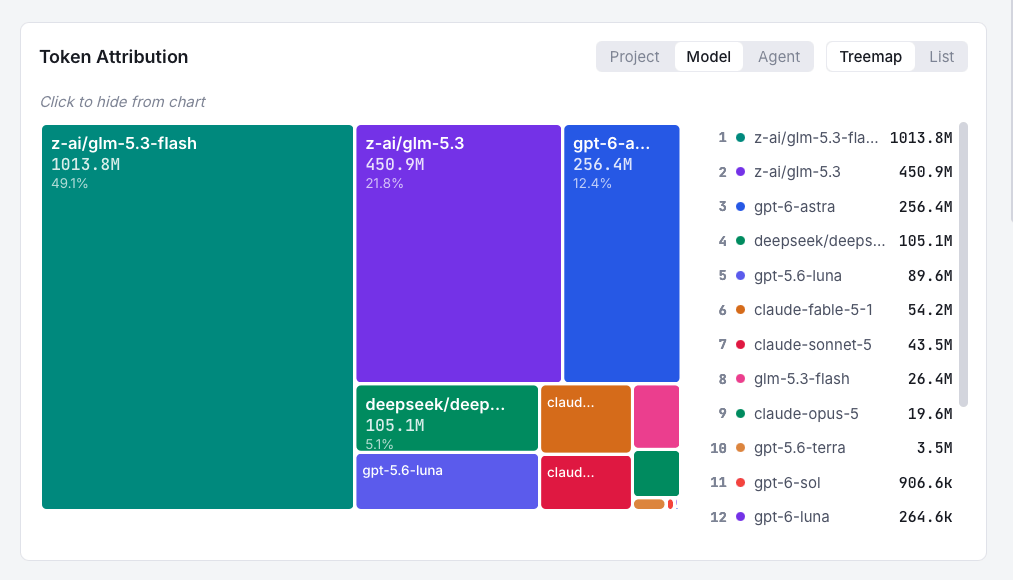
Loading the full article…
This text was published by wagtail.org. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
Coverage and discussion
1source- Hacker News discussion · 41 pointsnews.ycombinator.com
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Agents & Tools
All →- OpenAI launches Dots, always-on AI agents in ChatGPT · 63 src
- Llama.cpp adds decision models for routing and scoring tasks · 1 src
- Anthropic introduces mods for Claude Code · 1 src
- Microsoft adds Copilot Home, Code, and Autopilot to automate work tasks · 2 src
- Earendil releases Pi 1.0 agent harness with default MCP support · 2 src
Comments
via GitHub Discussions