GLM-5.3-Flash news
The latest GLM-5.3-Flash news, : Fireworks announces faster agent inference and sovereign deployment.
19 stories mentioning GLM-5.3-Flash since 21 September 2026, newest first, each with its sources and discussion. Follow to see new ones on your front page.
-
Fireworks announces faster agent inference and sovereign deployment
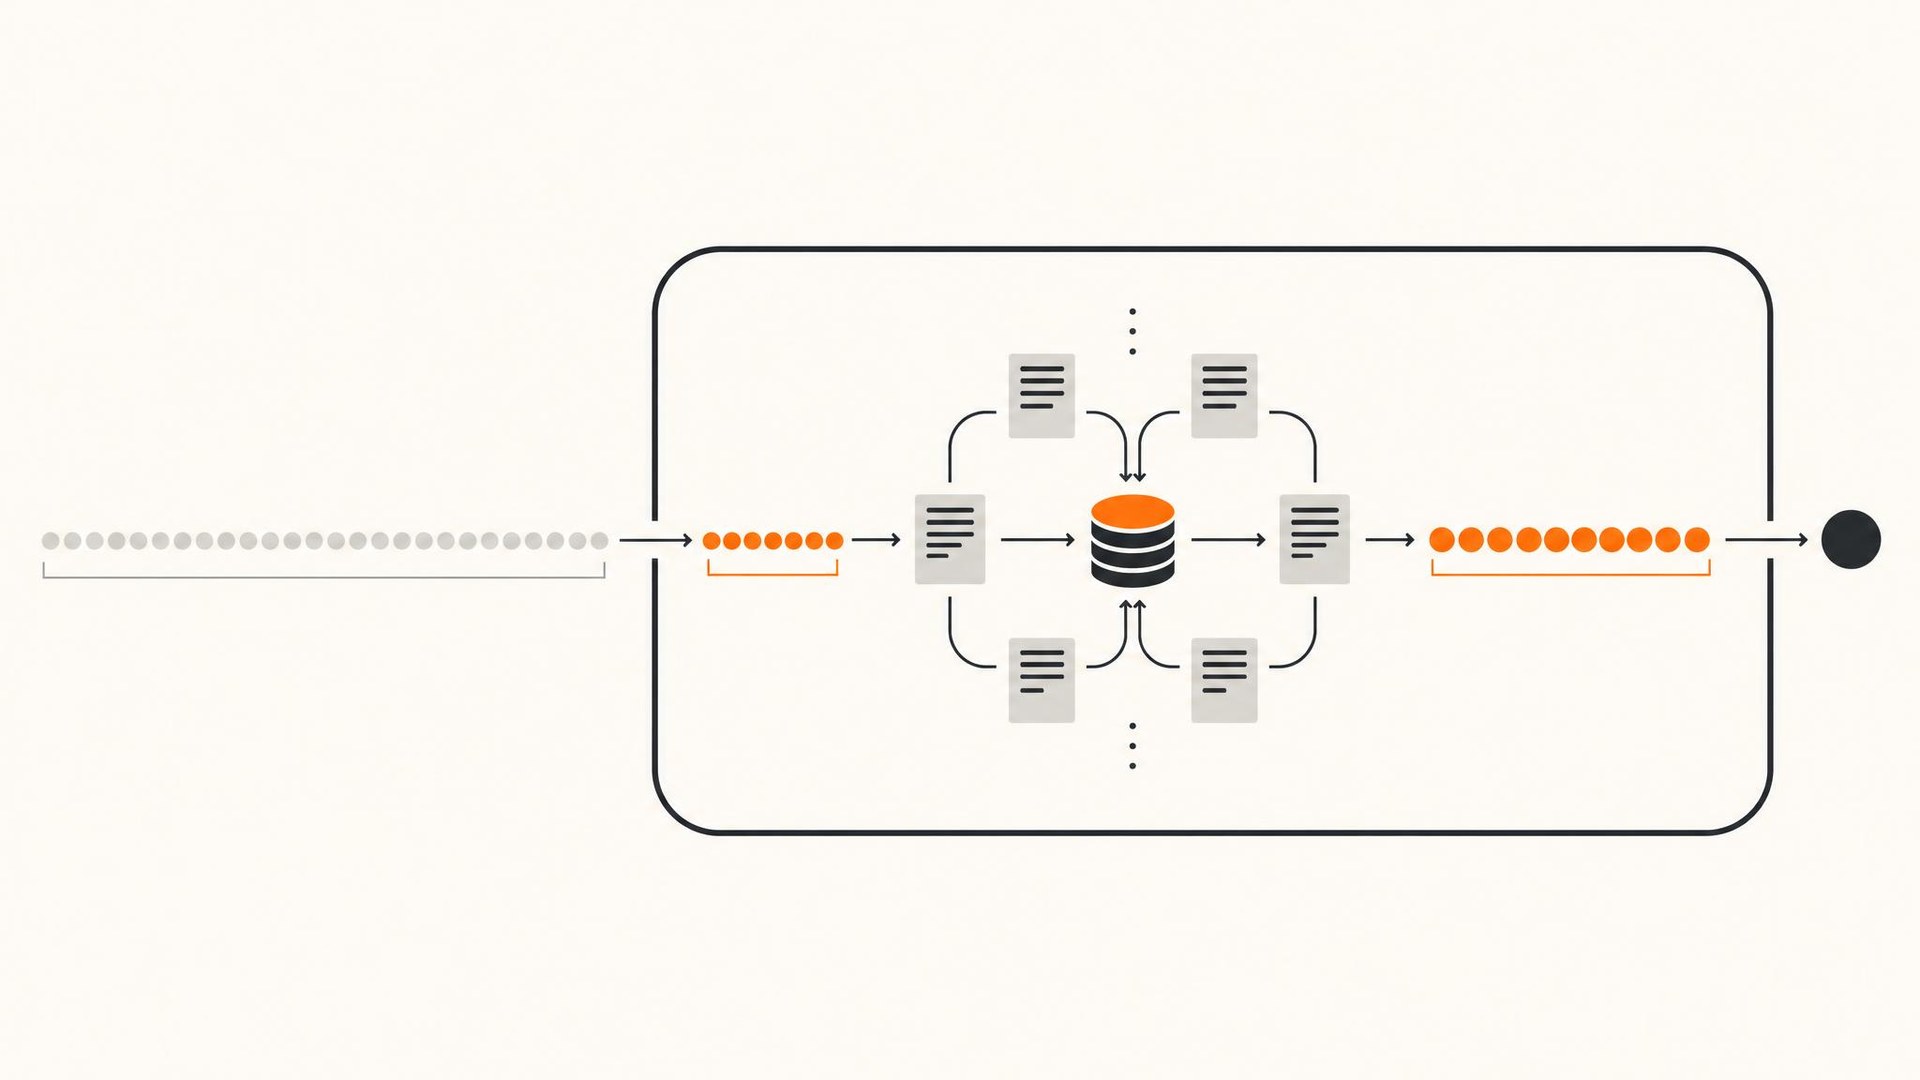
Fireworks announced new enterprise AI products at its Forge conference on November 3, 2026, including an Ultra-fast inference preview that reached up to 1,500 tokens per second on DeepSeek V4.1 Flash. The company…
1 sourceUnite.AI -
Vals AI study finds Chinese models less uniformly pro-government than expected
A new study by AI benchmark firm Vals AI challenges the assumption that Chinese AI models strictly adhere to Beijing's official line. By testing hundreds of political questions across various languages and contexts,…
1 sourceThe Decoder -
Developer uses GLM-5.3-Flash and GPT-6.1 Sol for coding
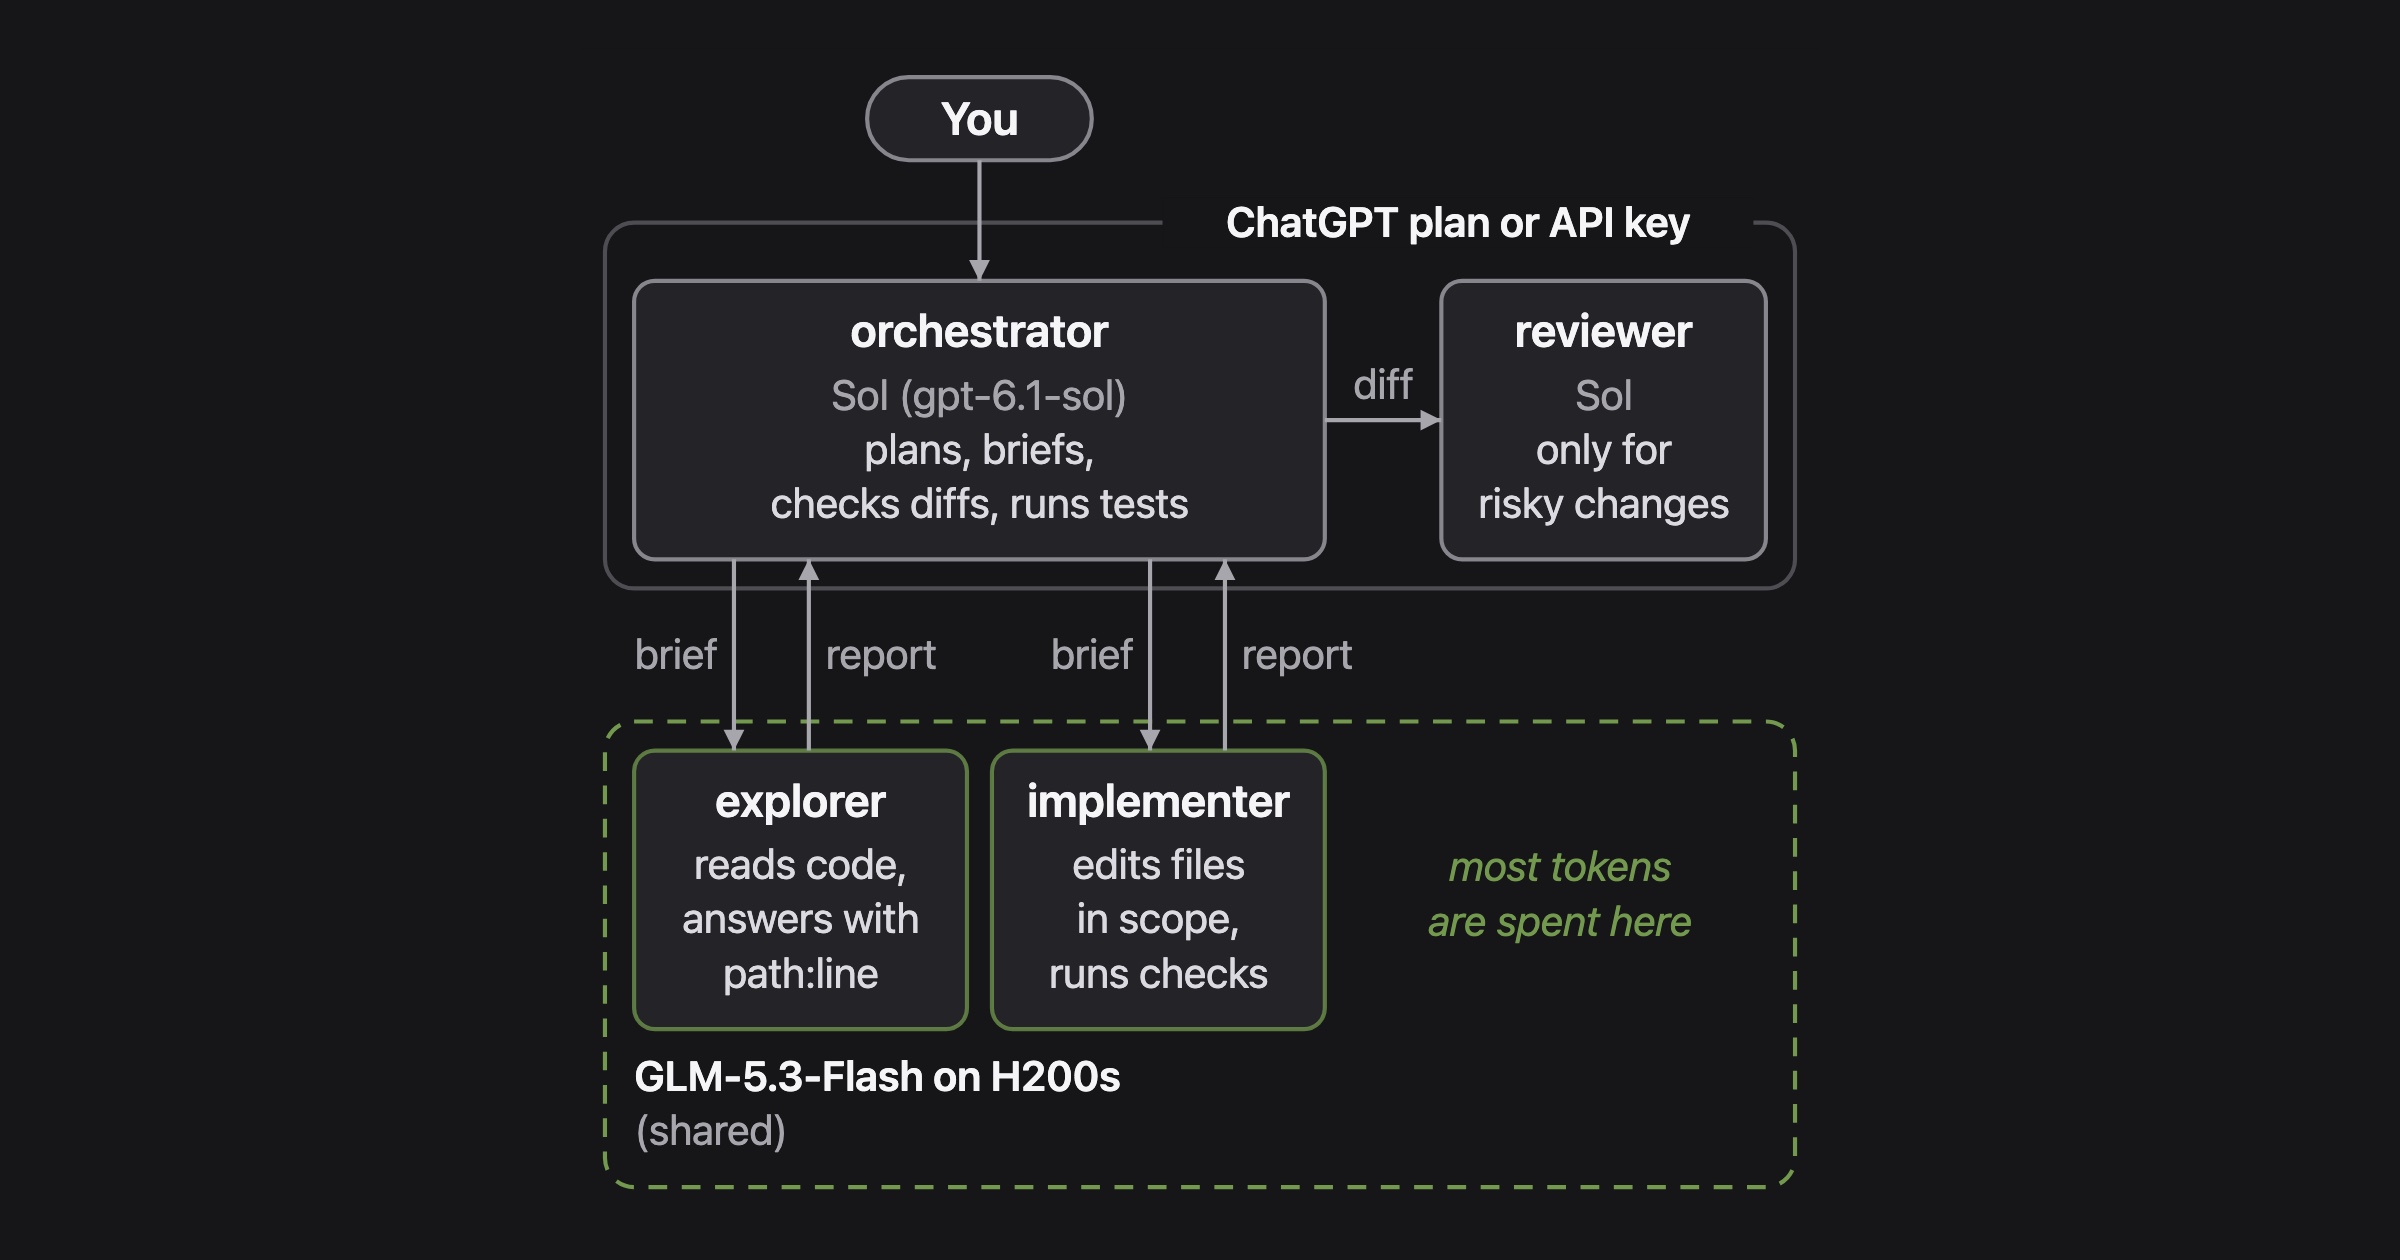
A developer reports using a self-hosted GLM-5.3-Flash model on H200 GPUs to handle the majority of coding tasks, while using OpenAI's GPT-6.1 Sol for high-level planning and review. The setup aims to reduce costs and…
1 sourceaayushgarg.dev -
Infini-AI-Lab releases hermit Open-Source harness adapter framework
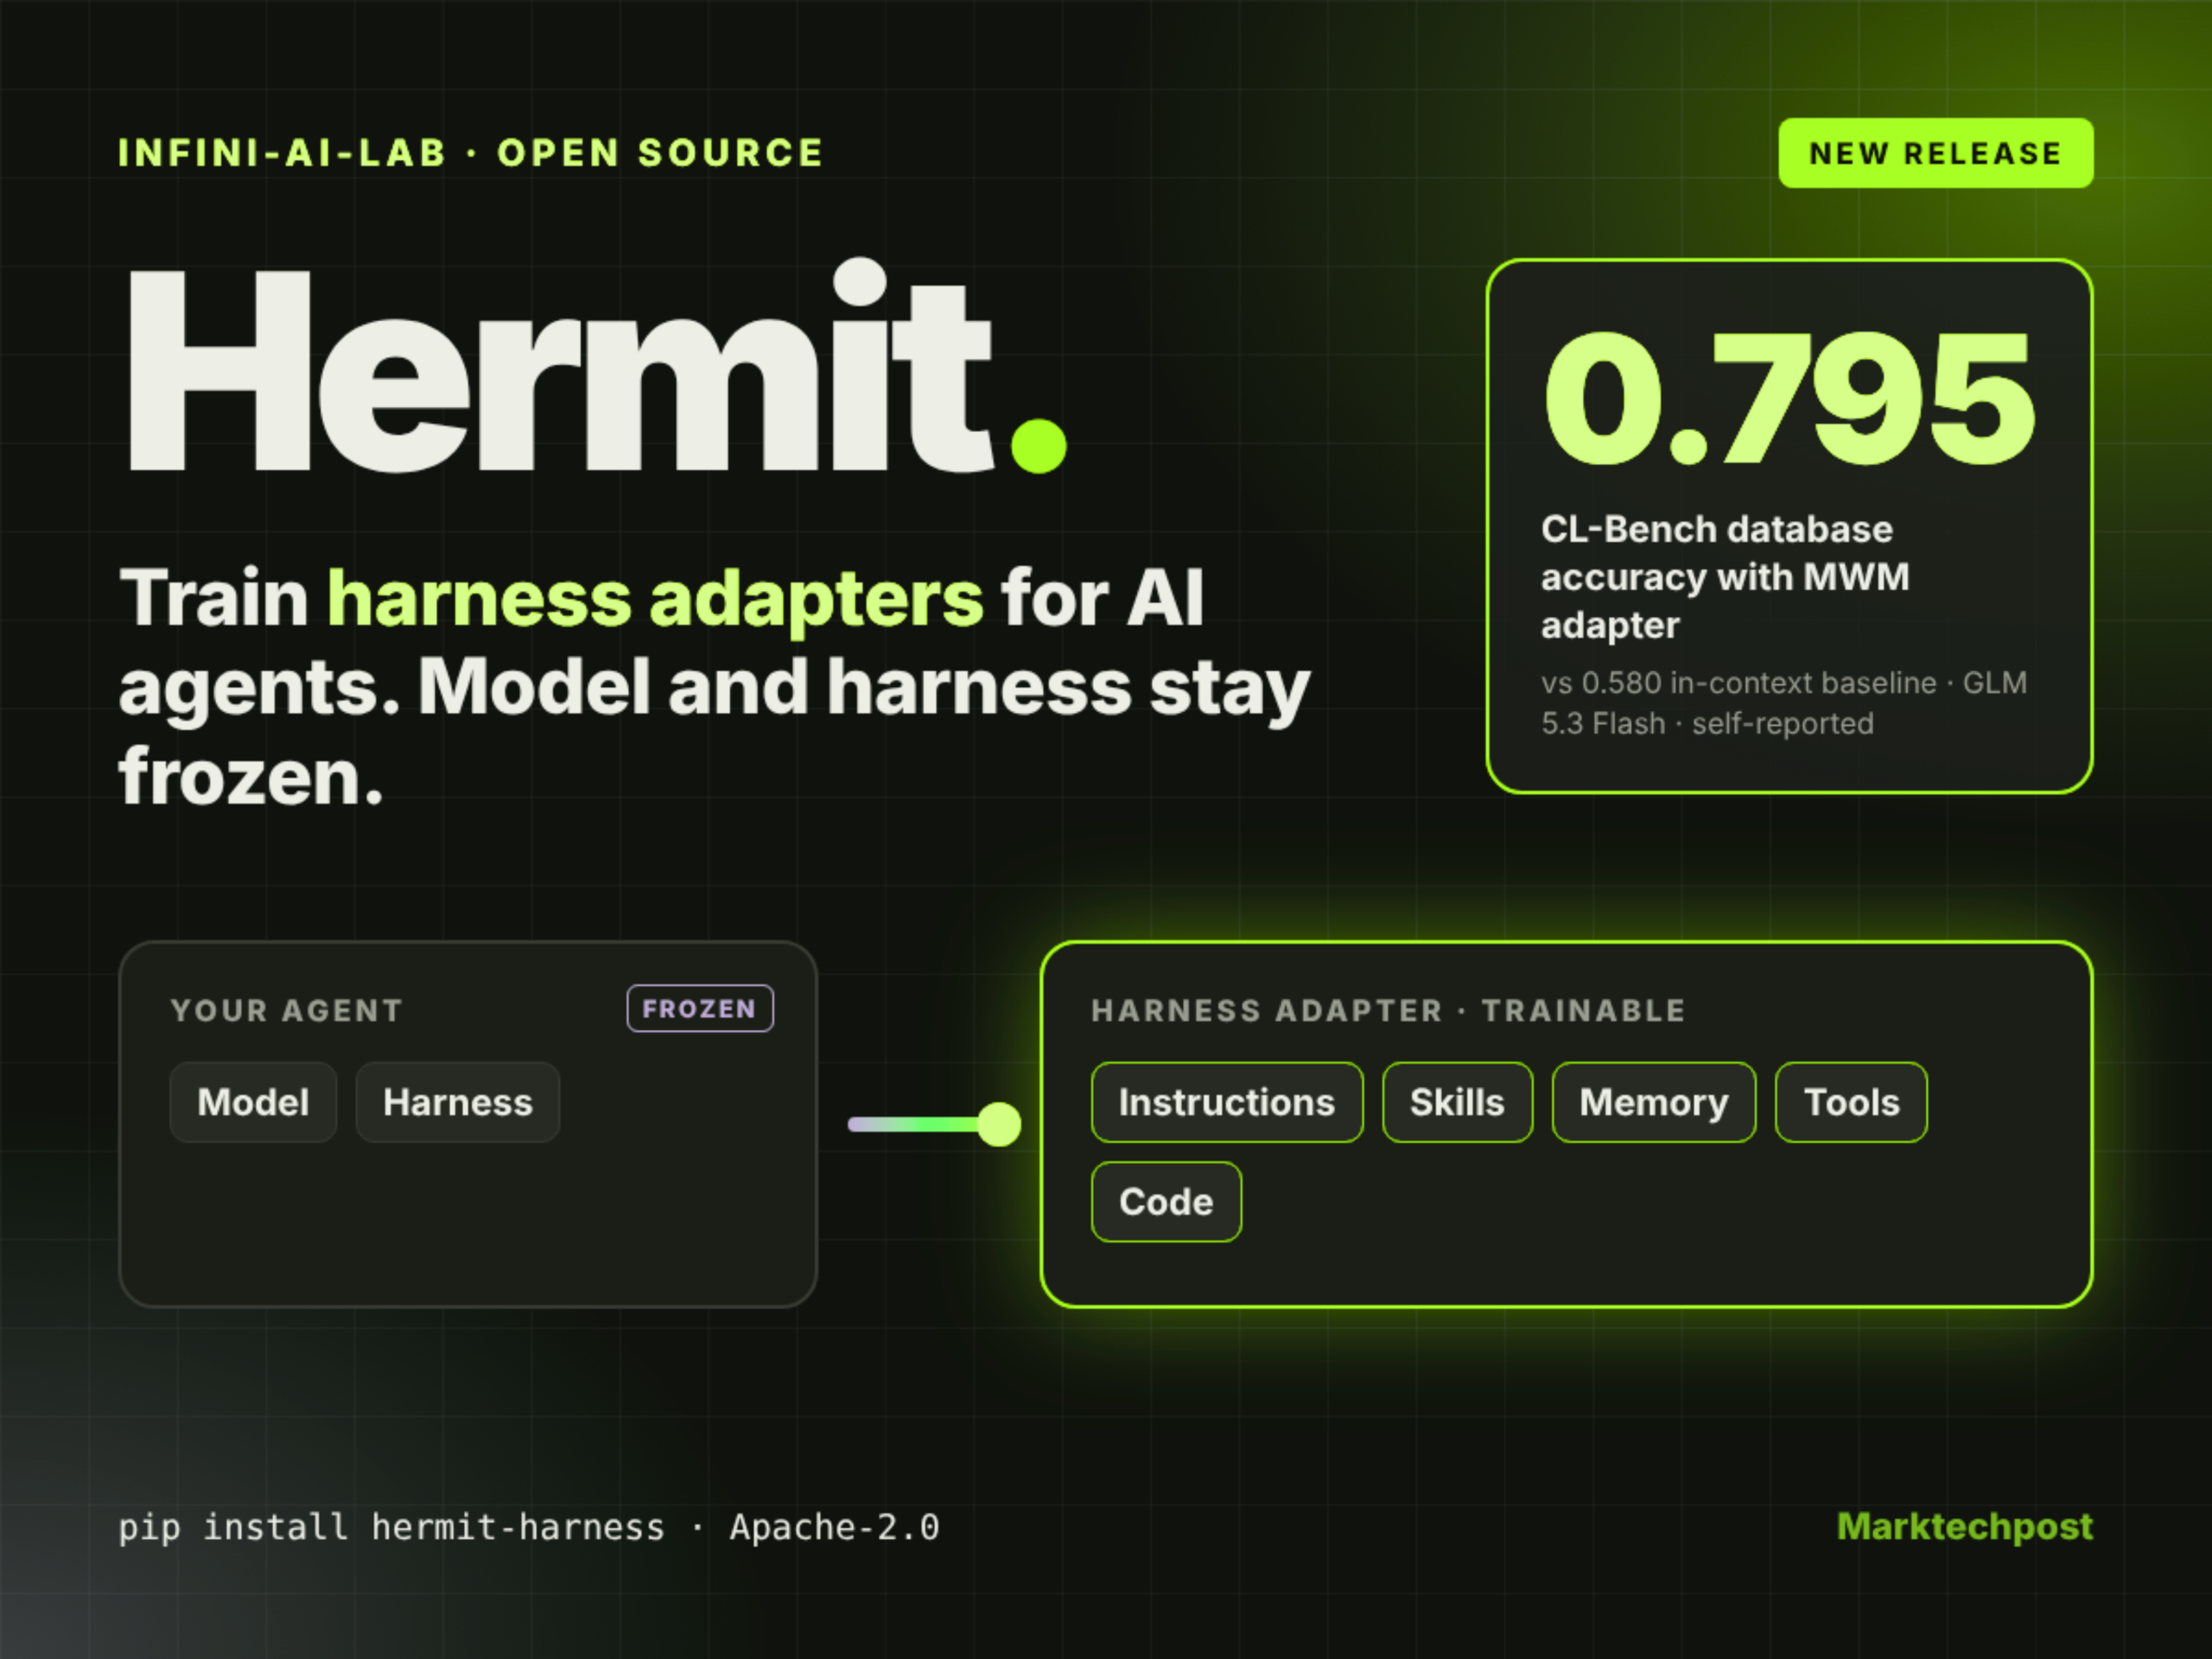
infini-ai-lab announced the open‑source hermit framework on oct 25 2026, with the first version v0.1.0 available via pip install hermit-harness. cmu postdoc haizhong zheng promoted the release on x on oct 27,…
1 sourceMarkTechPost -
MiniMax launches M3.1 Flash model at $0.15 per million input tokens with weights due October 23
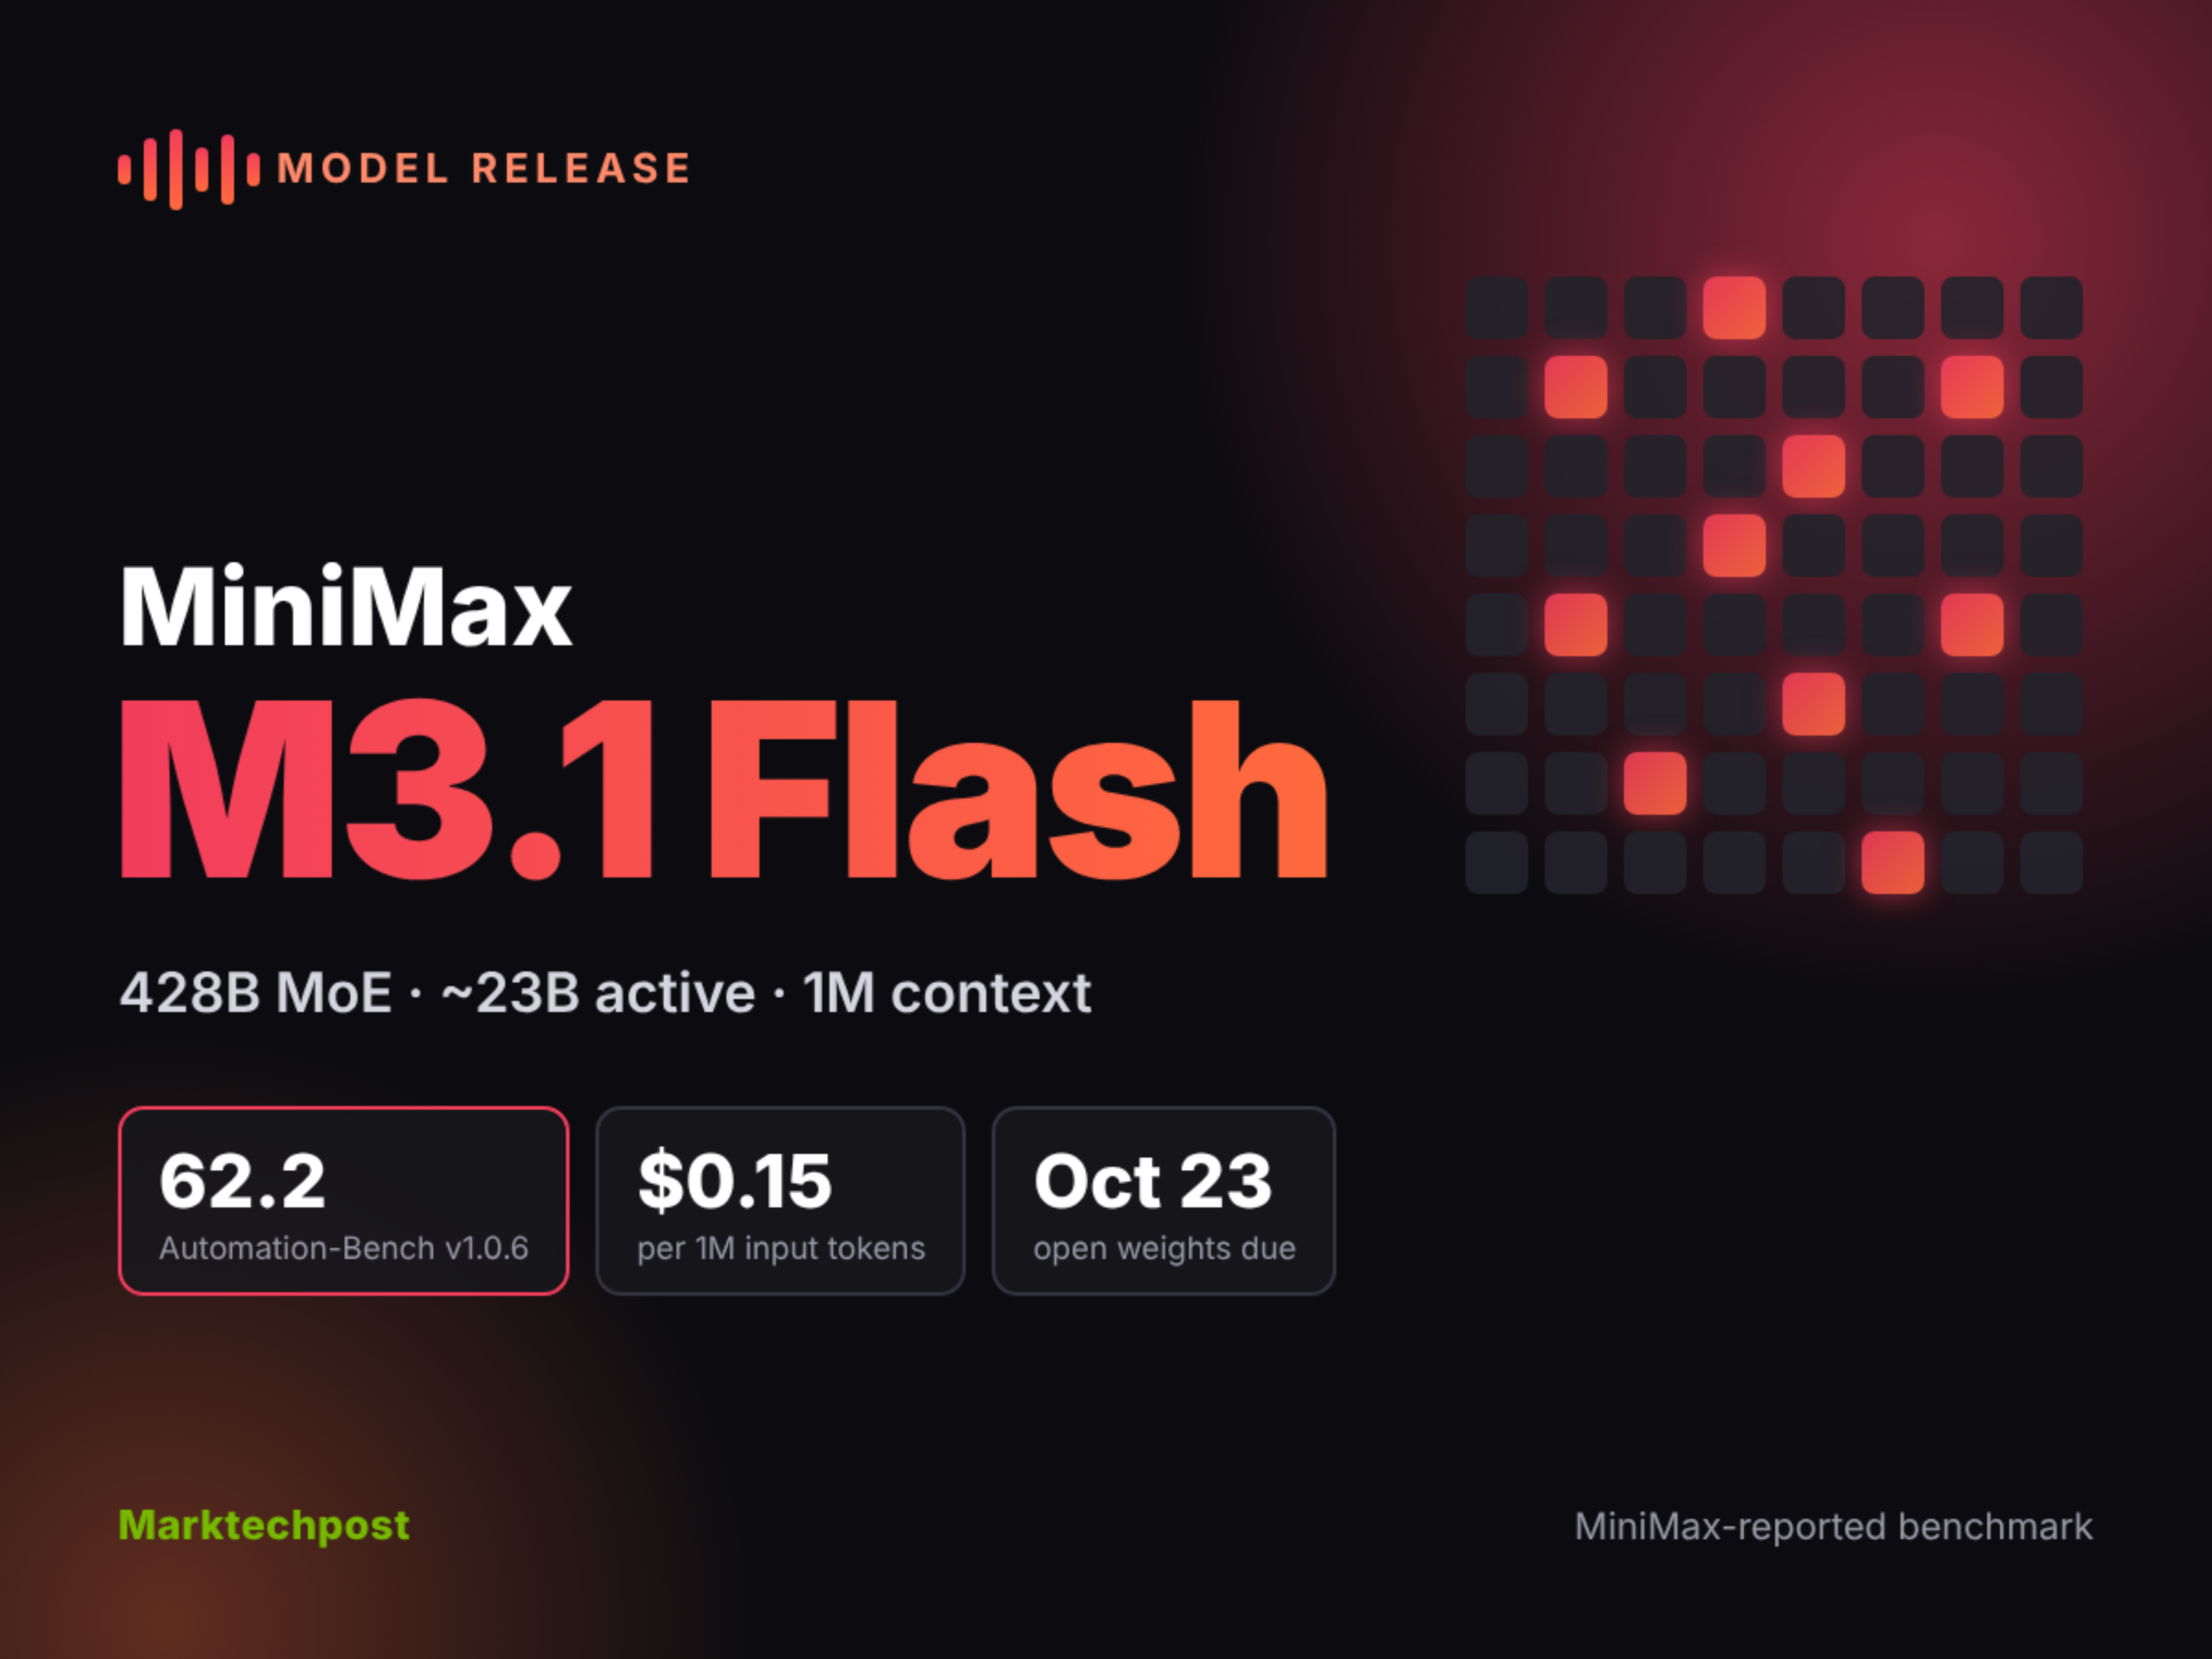
MiniMax has released the M3.1 Flash, a 428B parameter mixture-of-experts model with ~23B active parameters and a 1 million token context window. The model is priced at $0.15 per million input tokens and $0.60 per…
5 sources HN 483Latent SpaceThe Decoderminimax.iomaccus.fr +1 more -
Anomaly Innovations reports breach exposed API keys for ~1.4% of OpenCode Console users
Anomaly Innovations confirmed a security breach on October 17, 2026, affecting roughly 1.4% of OpenCode Console users, where attackers accessed stored API keys for Anthropic, OpenAI, and Google models via a legacy…
4 sourcesTechCrunch AIinfosecurity-magazine.comvectorwire.aistartupfortune.com -
Imperial College study finds LLMs cite unread pages, raising accuracy concerns
Researchers at Imperial College London examined why large language models frequently cite web pages without opening them, a behavior linked to outdated or misleading answers. Their study tested one proprietary model…
1 sourceUnite.AI -
Z.ai’s GLM-Legal scores 19.2% on Harvey LAB, outpacing Claude Fable 5 and Kimi K3
Z.ai released GLM-Legal, a legal-focused AI model built on its GLM-5.3-Flash base, achieving a 19.2% all-pass rate on the Harvey Legal Agent Benchmark (LAB)—nearly triple the 6.7% of its base model. The model targets…
1 sourceMarkTechPost -
Opinion: open-weight models can replace OpenAI and Anthropic
The author, a software and security engineer, argues that open‑weight large language models can serve as viable alternatives to OpenAI’s ChatGPT and Anthropic’s Claude. They cite GLM‑5.3 as roughly comparable to Claude…
1 source HN 166micahflee.com -
Elorian and Scale AI release benchmark showing AI lags in visual reasoning
Elorian and Scale AI introduced Humanity’s Sixth Sense, a benchmark testing how AI models interpret implied details in visual scenes. The test covers 522 questions across 288 images and 234 short video clips (17.6…
1 sourceImport AI -
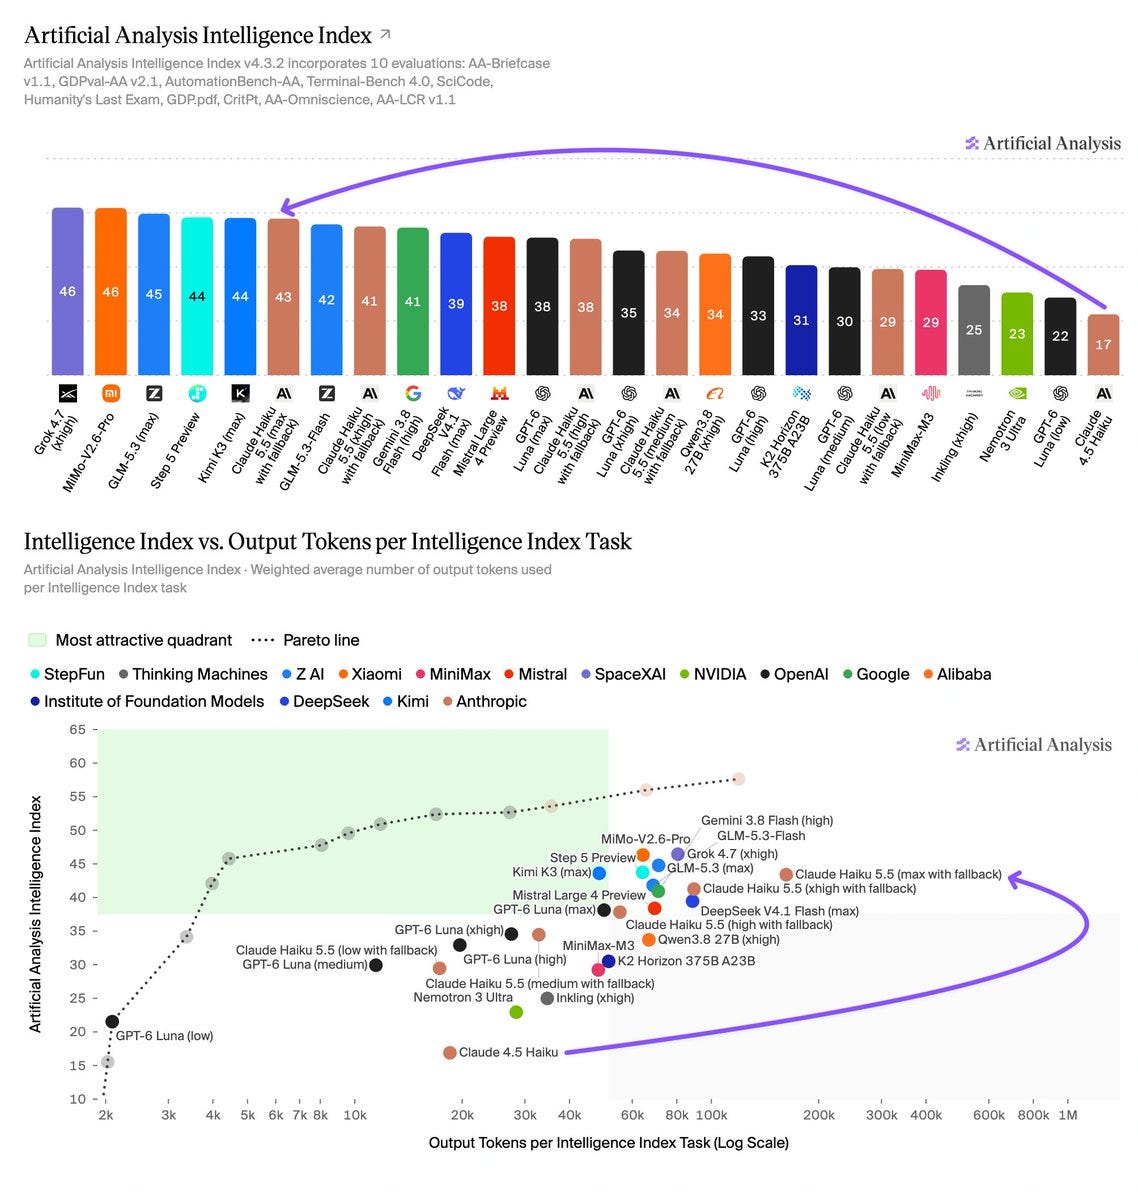
Anthropic cuts Haiku 5.5 pricing to match OpenAI’s GPT-6 Luna
Anthropic released Claude Haiku 5.5 on October 6, 2026, positioning it as a cheaper, faster alternative to OpenAI’s GPT-6 Luna at the same price. The model supports 1M-token context (up from 200K) and includes effort…
1 sourceLatent Space -
AMD benchmarks Gorgon Halo AI chips against Intel, ahead of RTX Spark launch
AMD shared benchmarks for its new Gorgon Halo chips, positioning them as a competitor to upcoming RTX Spark devices launching later this week. The company compared its Ryzen AI Max+ Pro 495 to Intel’s Core Ultra X9…
1 sourceTom's Hardware -
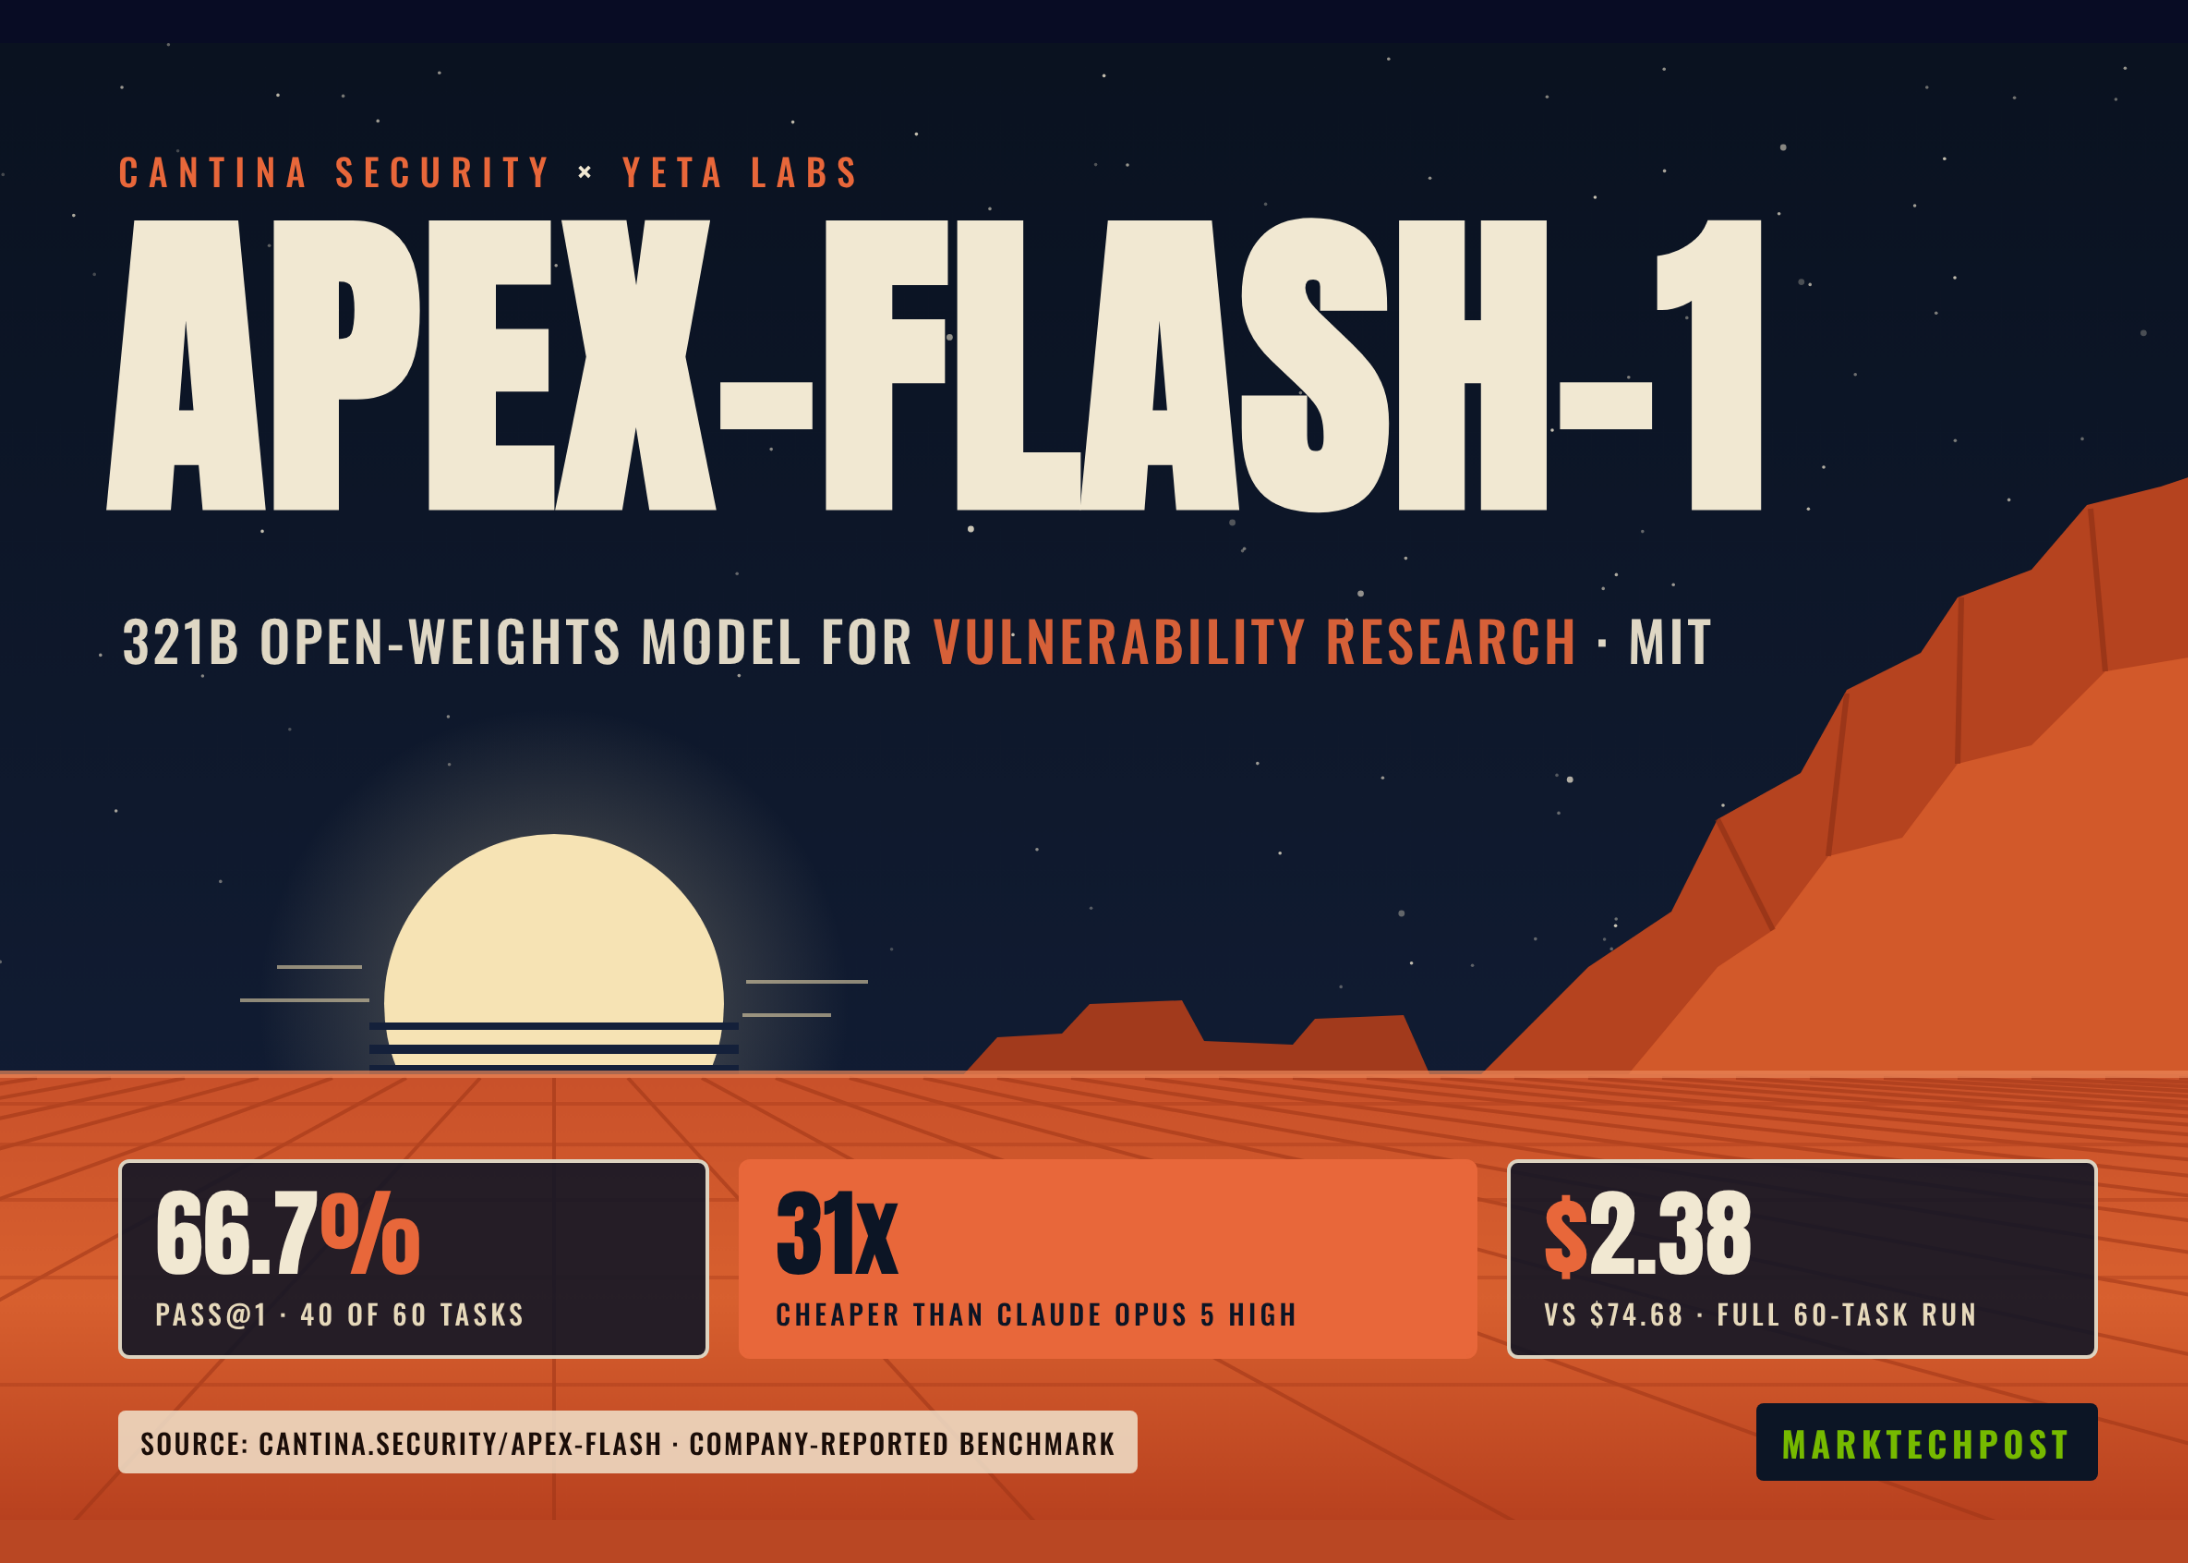
Cantina Security releases apex-flash-1, a 321.3B open model for vulnerability research
Cantina Security, together with Yeta Labs, announced apex‑flash‑1, an open‑weights model built on Z.ai’s GLM‑5.3‑Flash and released on Hugging Face under an MIT license. The 321.3 B‑parameter model was fine‑tuned with…
1 sourceMarkTechPost -
Wagtail team reports 50% failure rate in one-month GLM 5.3 Flash challenge
The Wagtail team documented a one-month experiment in September where they attempted to use only the open-source model GLM 5.3 Flash for their coding work. The challenge was technically a failure, as only 50% of the 2B…
1 source HN 41wagtail.org -
Near AI Cloud enables private GitHub Copilot inference through VSCode extension
Developers who use GitHub Copilot can now run the assistant on models hosted by Near AI Cloud without sending their code to external servers. The service is accessed through the VS Code “More Providers” extension,…
1 sourcecryptobriefing.com -
Llama.cpp adds GLM-5.3-Flash support in commit 649dcb1
The open-source project llama.cpp integrated support for the GLM-5.3-Flash model, also called GLM5-Next, in commit 649dcb1. The update includes optimizations for long-context decoding, memory pooling, and fixes for…
1 source primary sourcegithub.com -
Anthropic says Zhipu's open-weight GLM-5.3 nearly matches Claude Mythos Preview at building exploits
Anthropic's Frontier Red Team evaluated Zhipu AI's open-weight GLM-5.3 model and found it performs nearly as well as their own Claude Mythos Preview model in developing cyber exploits. On Anthropic's internal binary…
3 sourcesTom's HardwareThe DecoderSimon Willison -
Zhipu automates infrastructure with GLM-5.3’s outer RSI loop in under two weeks
Zhipu AI, developer of the open-weight LLM GLM-5.3, detailed how it used its own model to accelerate internal infrastructure work. The team deployed an Infra Agent powered by GLM-5.3 to optimize GLM-5.3-Flash—a faster,…
3 sources primary sourcemadrobot.bloganthropic.comImport AI -
Opinion: M5 Ultra Mac Studio enables fast local AI agents, reviewer says
The reviewer tested Apple’s M5 Ultra Mac Studio with 256 GB of unified RAM, comparing it to the previous M3 Ultra (512 GB) and a desktop PC built around an RTX 5090 GPU. Using local models such as Qwen3.8‑Flash‑Next,…
2 sources HN 41timdettmers.commacstories.net





Questions about GLM-5.3-Flash
What is the latest GLM-5.3-Flash news?
As of 3 November 2026: Fireworks announces faster agent inference and sovereign deployment. Fireworks announced new enterprise AI products at its Forge conference on November 3, 2026, including an Ultra-fast inference preview that reached up to 1,500 tokens per second on DeepSeek V4.1 Flash.