What is data poisoning and how attackers corrupt AI models?
Data poisoning refers to the manipulation of training, fine‑tuning, evaluation, or retrieval data so that an AI system learns corrupted behavior or produces outcomes chosen by an attacker. The guide defines the technique with three practical commitments: an identifiable input, a transformation characteristic of poisoning, and an evaluable outcome. It stresses that a control is only meaningful…
Key points
- Data poisoning manipulates training or retrieval data to cause attacker‑chosen AI behavior.
- A five‑stage map outlines influence, insertion, survival, alteration, and activation phases.
- Detection requires tracing inputs, owners, and controls to spot tiny malicious subsets.
The article presents a five‑stage operating map for data poisoning: (1) gaining influence over a data source, (2) inserting mislabeled, biased, or trigger‑bearing examples, (3) surviving filtering and deduplication, (4) altering the learned model or retrieved context, and (5) activating broad degradation or a targeted backdoor. Each stage requires clear ownership, traceability, and testing to detect tiny targeted subsets that can hide in web‑scale data. The guide advises forward and backward analysis, rigorous benchmarking, and staged deployment with explicit stop conditions to ensure that defenses target the earliest observable precursor to failure.
Finally, the piece explains why data poisoning matters now: AI systems are receiving larger contexts, more modalities, and deeper integration with organizational decisions, making the technique a potential vector for latency spikes, security breaches, or legal liability. Effective mitigation involves documenting uncertainty, preserving data lineage, and designing recovery mechanisms before real‑world exposure.
What Is Data Poisoning? How Attackers Corrupt AI Models and Datasets
Unite.AI · 25 October 2026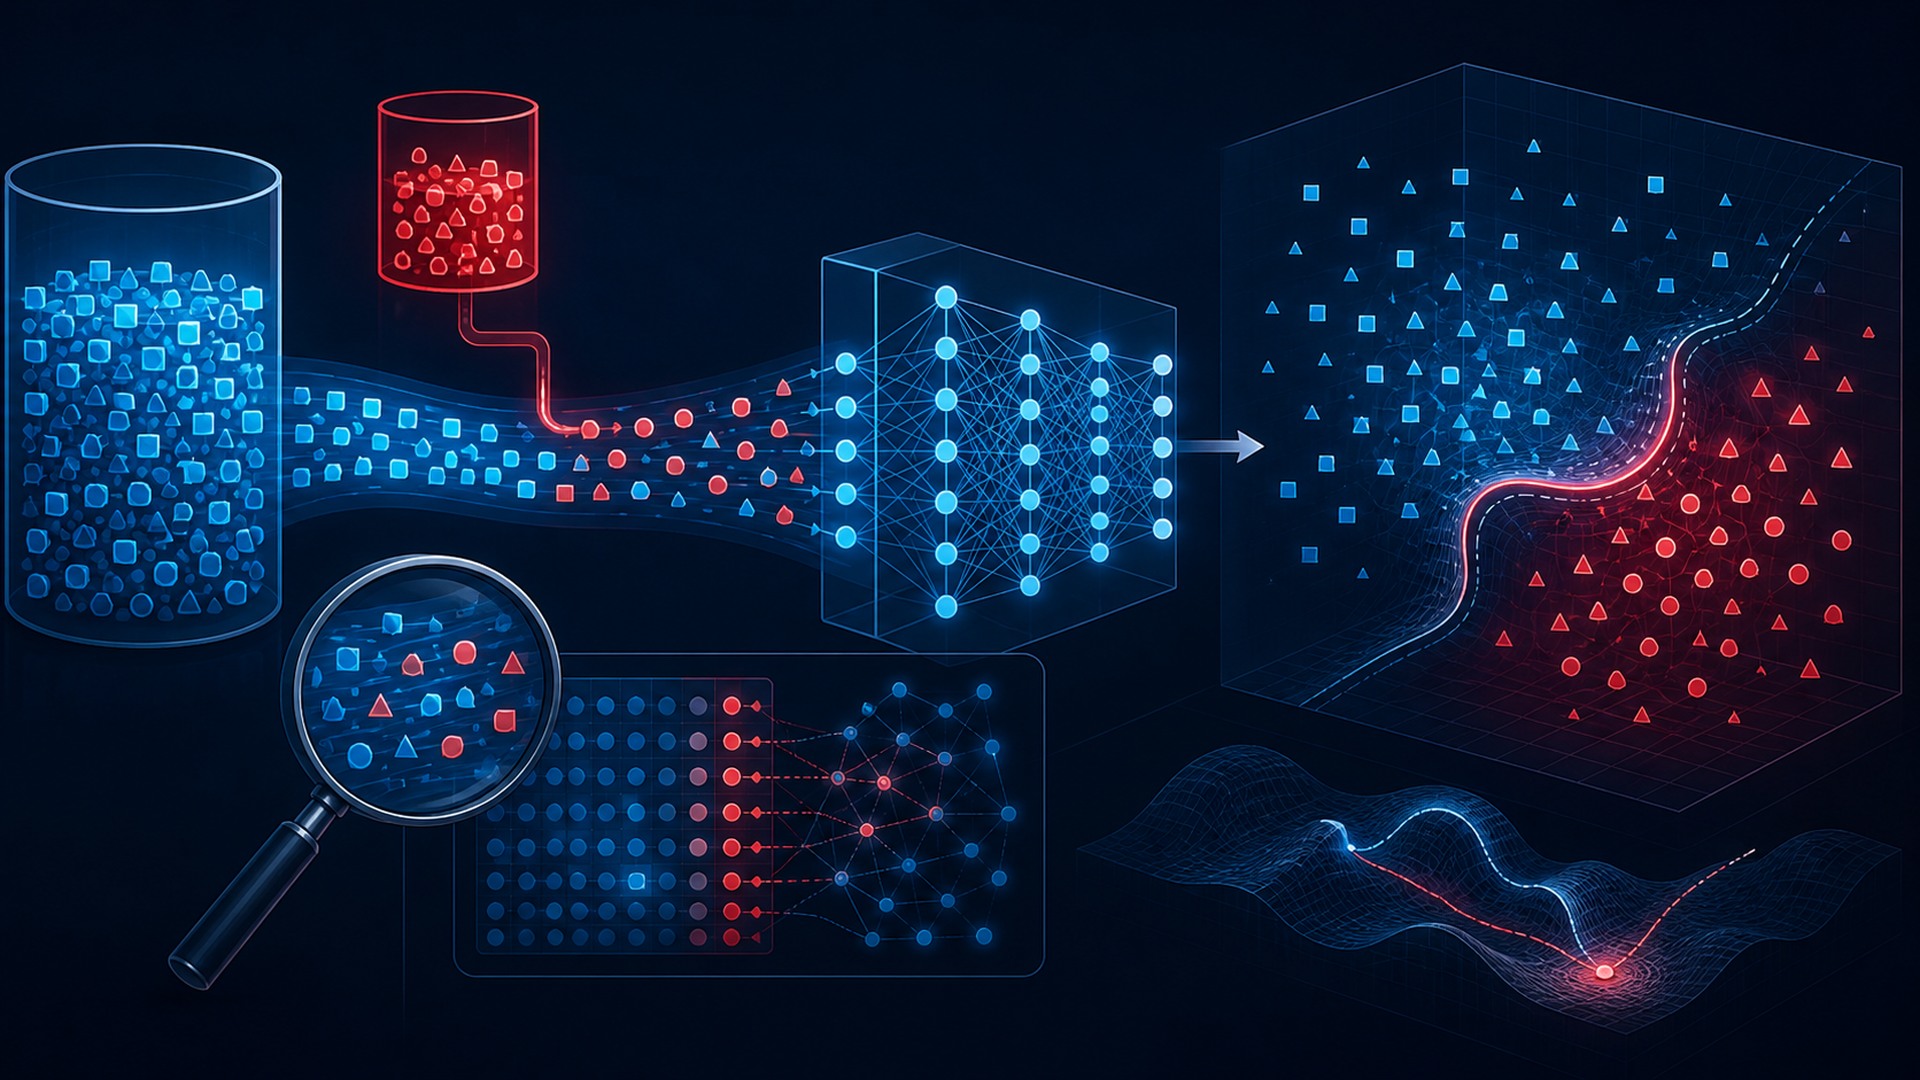
Loading the full article…
This text was published by Unite.AI and written by Miles Okada, AI & Cybersecurity, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- MarkTechPost publishes tutorial on running Underdog Saluki 27B quantized model · 1 src
- OpenAI agents study Parkinson-like disease data in 32 minutes · 1 src
- OpenAI releases LASER to find ambiguous AI safety cases · 1 src
- Study finds AI text harder to read due to information density · 1 src
- OpenAI suspects three ex-researchers leaked internal model designs to Ryan Greenblatt · 2 src
Comments
via GitHub Discussions