Lumai deploys Iris optical servers in ARIA’s £50M Scaling Inference Lab
The lab, run by CommonAI CIC, will use Lumai’s Iris servers as its first optical-compute platform to evaluate rack-scale integration in a commercial data-center environment. This follows the April launch of Iris Nova, which supports Llama models with 8 billion and 70 billion parameters and is available for data-center evaluation under standard rack infrastructure and air cooling.
Key points
- Lumai’s Iris servers tested in ARIA’s £50M Scaling Inference Lab for rack-scale integration
- Iris Nova supports Llama models with 8B and 70B parameters, available for data-center evaluation
- Lumai claims up to 90% power savings but lacks independent validation for full-system gains
Lumai’s hybrid optical-digital architecture targets dense matrix operations in AI inference, aiming to execute calculations in parallel via light propagation rather than transistor switching. The company claims potential power savings of up to 90% and total cost of ownership reductions to around one-tenth of conventional GPUs, though these figures are unconfirmed by independent validation. The lab’s structured pilots—each incorporating unproven tech into deployable systems—will compare full-system performance against commercial alternatives, with a new rack planned every six months. Lumai’s CEO, Xianxin Guo, called the ARIA deployment a critical step to prove real-world readiness.
ARIA Selects Lumai Optical Servers for Rack-Scale AI Inference Testing
Unite.AI · 3 November 2026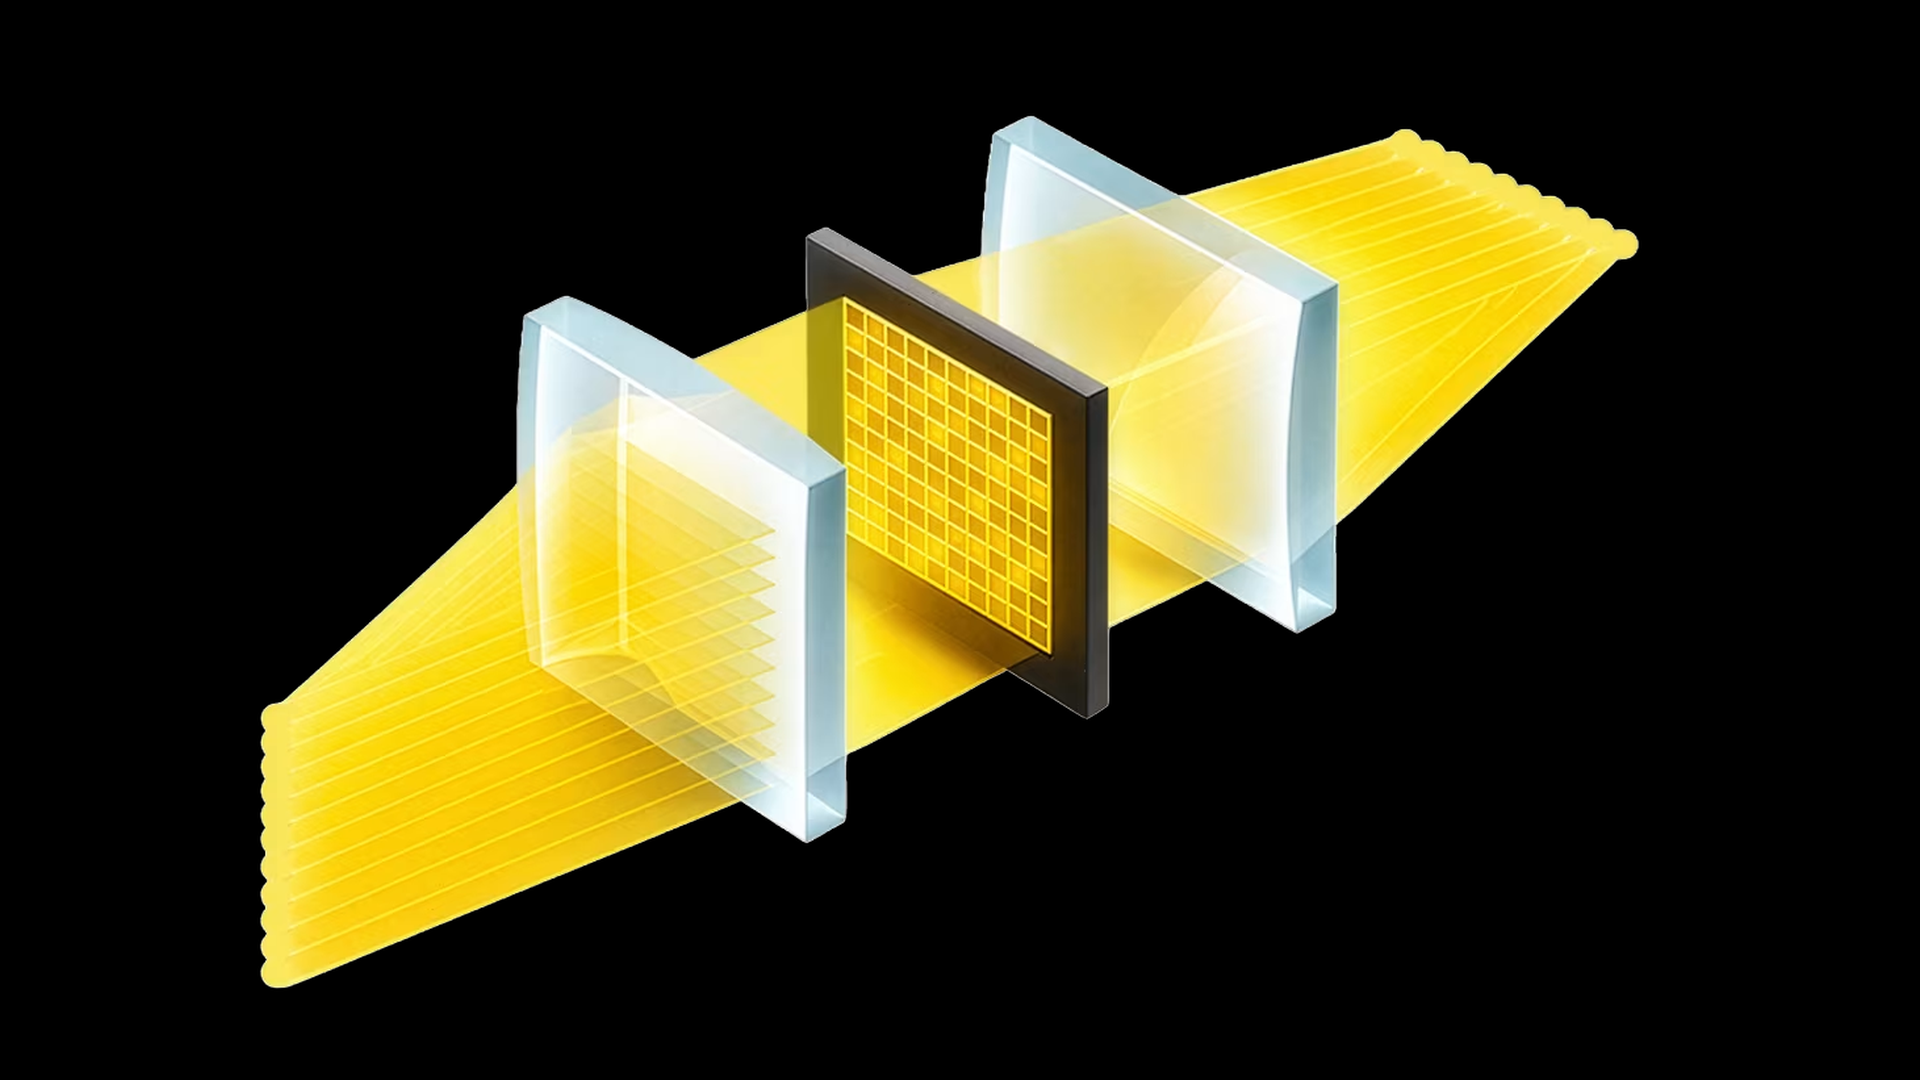
Loading the full article…
This text was published by Unite.AI and written by Theo Nash, AI Infrastructure & Compute, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Hardware & Compute
All →- NVIDIA directly contacts Nitto Boseki over 90% glass cloth market share · 1 src
- SpaceX scales AI cloud to 13GW by 2027, outpacing Google’s 1999-2026 total · 1 src
- Russia orders 10% of data centers reserved for state use amid drone attacks · 1 src
- Mtmd : add Nemotron 3.5 Transcribe support by pskrunner14 · Pull Request #31471 · ggml-org/llama.cpp · 1 src
- AMD launches Helion AI rack for flexible agentic workloads · 1 src
Comments
via GitHub Discussions