OpenAI releases PaperBench benchmark for AI research reproducibility
OpenAI released PaperBench, a benchmark to measure AI reproducibility of research papers. It covers 20 papers from ICML 2024, spanning 12 fields. The benchmark breaks each paper into 8,316 scorable items, allowing partial scoring.
Key points
- OpenAI's PaperBench benchmark covers 20 ICML 2024 papers and 8,316 scoring items.
- Highest average reproduction score 21.0% using Claude 3.5 Sonnet with open-source tools.
- Human experts outperformed AI; AI did not exceed human baseline.
The evaluation has three stages: code creation, execution in a new environment, and result scoring. The highest average reproduction score achieved was 21.0% by an agent combining Claude 3.5 Sonnet with open-source tools. Human experts outperformed AI, and the benchmark shows AI still lags behind human baseline.
Automated grading was also tested. JudgeEval achieved an F1 of 0.83. The study highlights gaps in AI's ability to fully reproduce research and suggests a collaborative workflow where AI handles preparation and humans verify results.
Can AI Reproduce Research Papers? The Reality Measured by OpenAI's "PaperBench"
note.com · 3 November 2026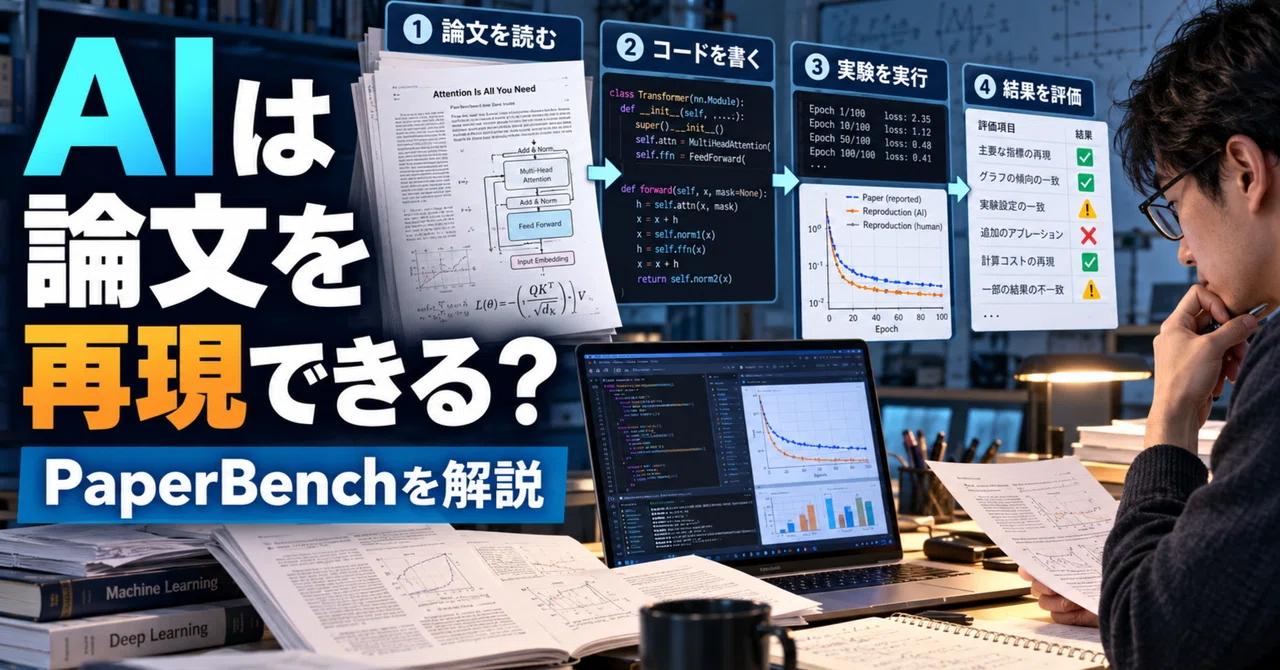
Loading the full article…
This text was published by note.com and written by つるとーのひとりごと. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Research
All →- Hugging Face proposes Model Integration Contracts to catch regressions in Transformers · 1 src
- MIT researchers report GPT-6 Astra natively reads and writes neural network weights, raising Qwen3.5-0.8B MATH-500 from 7.9% to 48.1% by editing 0.016% of weigh · 4 src
- Simon Willison sends October sponsors-only newsletter · 1 src
- Anthropic releases FlashProve for cryptographic AI inference proofs · 1 src
- Zyphra releases ZHA, a sparse attention method for frozen models · 1 src
Comments
via GitHub Discussions