SGD vs. Adam: How Machine Learning Optimizers Actually Learn
It details the stages from sampling a mini‑batch and computing loss to adjusting the learning‑rate schedule, emphasizing how each step can be traced and verified. The guide also warns that treating sgd and adam as interchangeable can mislead buyers, researchers, and operators.
Key points
- sgd and adam are optimization algorithms that update model parameters from estimated gradients
- the guide presents a five‑stage map for sgd and adam
- sgd and adam differ in momentum handling and per‑parameter step sizes
The piece stresses that the choice between sgd and adam matters for latency, generalization, and resource use in large‑scale AI systems, and recommends reporting distributions, failure categories, and tail latency rather than a single average metric.
SGD vs. Adam: How Machine Learning Optimizers Actually Learn
Unite.AI · 3 October 2026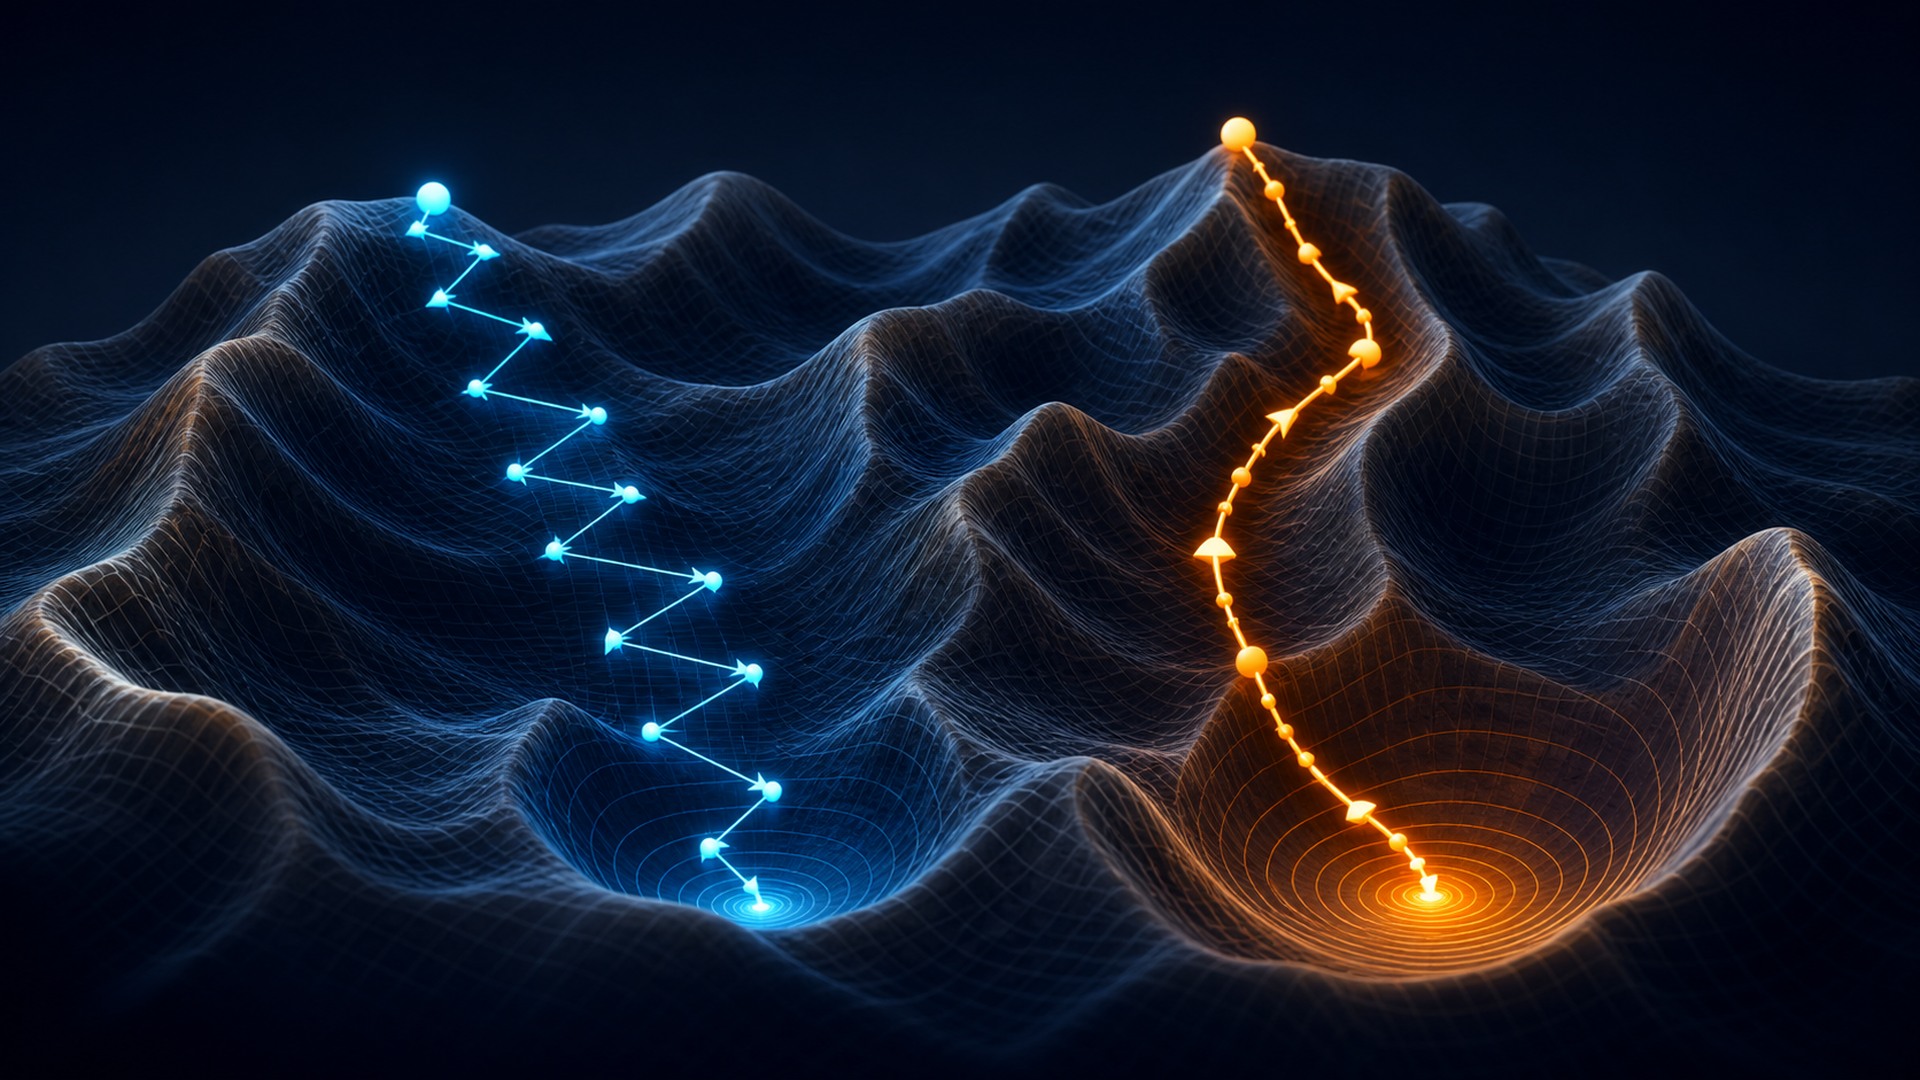
Loading the full article…
This text was published by Unite.AI and written by Jonas Reeve, Cognitive AI & AGI, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Agents & Tools
All →- OpenAI launches Dots, always-on AI agents in ChatGPT · 65 src
- University of Maryland and AWS evaluate GPT-6 Astra for 3D scene coding, hit 53% indoor accuracy · 1 src
- Meta, OpenAI and Uber launch proactive AI agents that interrupt users · 1 src
- Anthropic introduces mods for Claude Code · 2 src
- Prime Intellect launches Prime Inference for serving open models · 1 src
Comments
via GitHub Discussions