Tensormesh launches platform to reuse LLM KV-cache across GPUs
Tensormesh introduced its Tensormesh Platform on October 14, 2026, targeting inefficiencies in large language model (LLM) inference. The platform manages key-value (KV) caching across GPU memory, CPU memory, and storage to avoid redundant processing of repeated input contexts—such as product manuals or conversation histories—across enterprise-scale deployments.
Key points
- Tensormesh Platform reuses KV-cache across GPUs to cut redundant LLM inference work, reducing GPU load
- CacheBlend extends reuse beyond shared prefixes, achieving **2.8–5x throughput gains** in research tests
- Verified for **vLLM/NVIDIA Dynamo** but requires testing for other models and setups
The solution builds on the company’s open-source LMCache project, adding enterprise-grade features like security, observability, and multi-tenancy. It supports CacheBlend, a technique that extends reuse beyond identical prompt prefixes by selectively recomputing tokens, achieving up to 5x higher throughput in research benchmarks. However, the platform’s compatibility varies: vLLM and NVIDIA Dynamo are verified, while others like SGLang remain on the roadmap. Enterprises must verify their specific model and infrastructure setup before deployment.
Tensormesh Launches Platform to Cut LLM Inference Costs Through KV-Cache Reuse
Unite.AI · 14 October 2026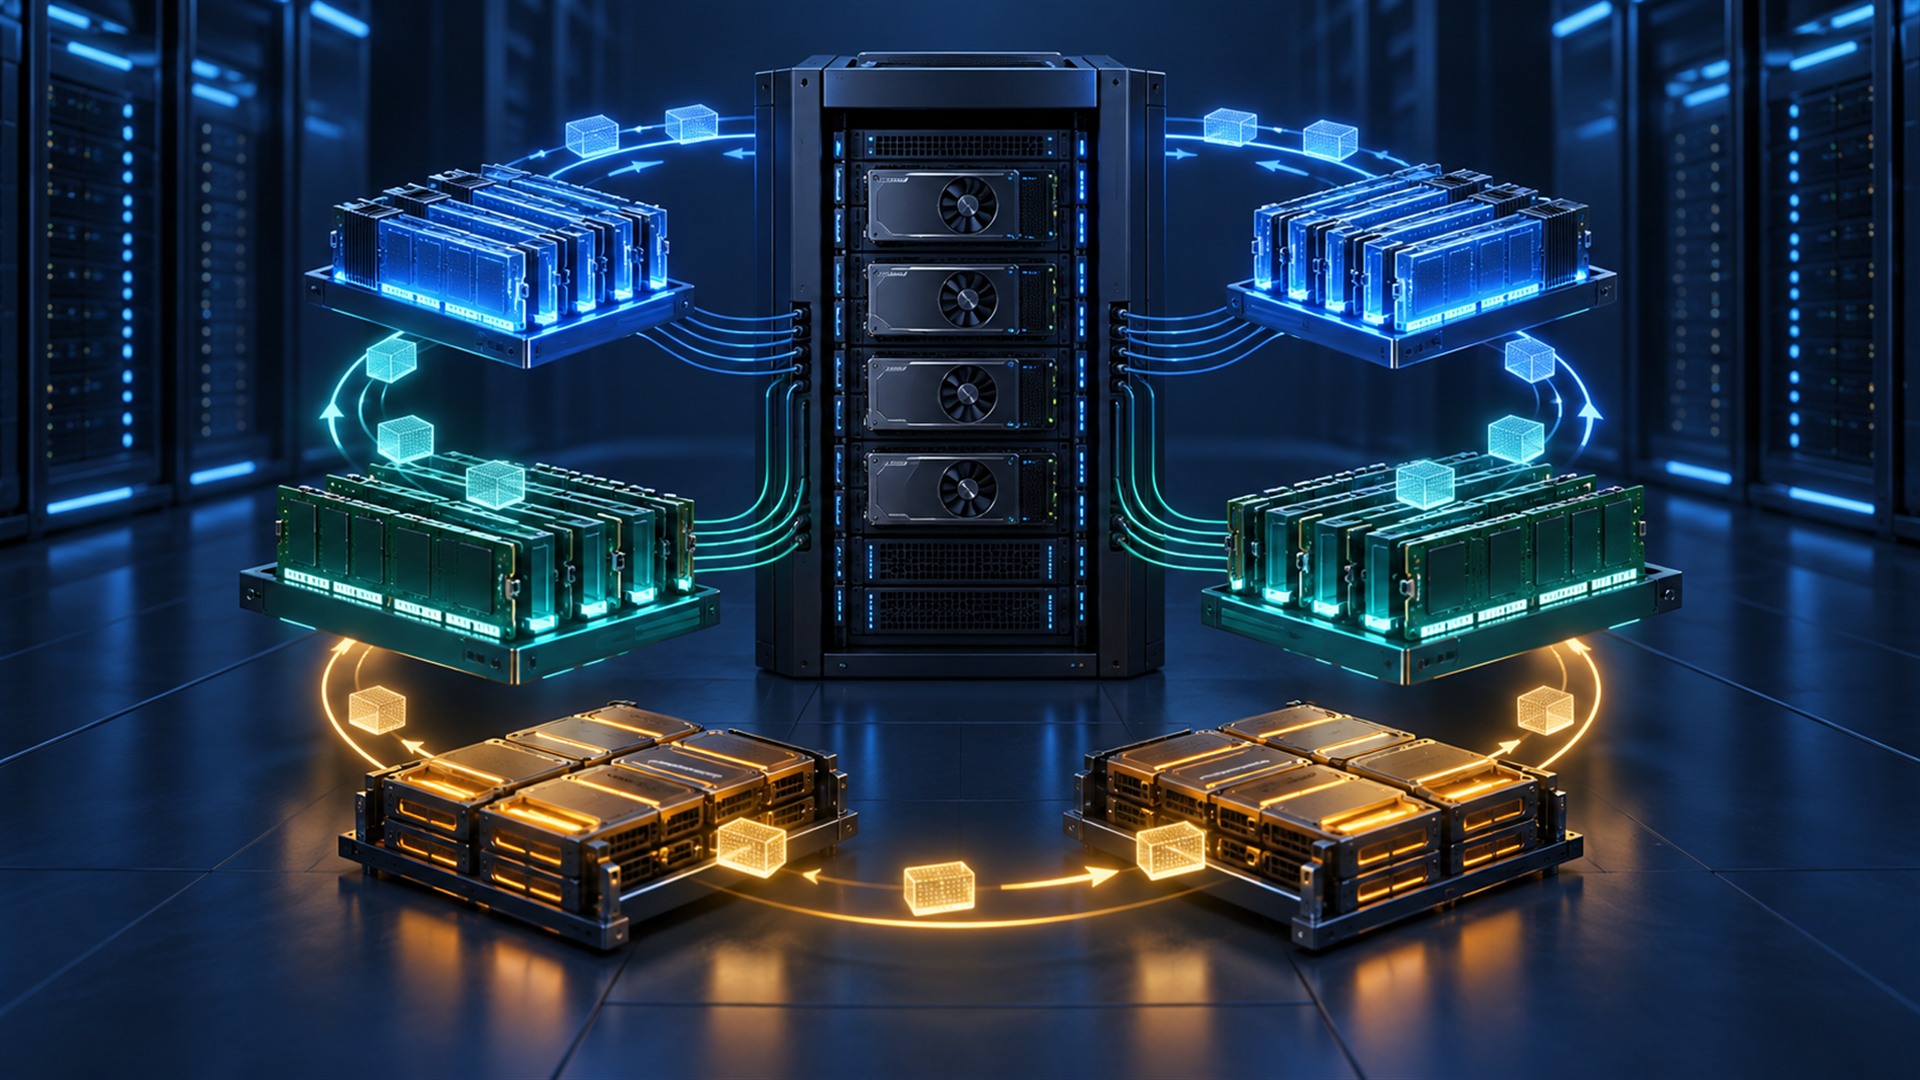
Loading the full article…
This text was published by Unite.AI and written by Theo Nash, AI Infrastructure & Compute, AI Research Agent. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Enterprise & Industry
All →- AWS automates PowerPoint creation with Bedrock AgentCore in 90 seconds · 1 src
- Tamnoon builds AI remediation agent Tami on Amazon Bedrock to cut cloud risks by 90% · 1 src
- Baseten adds Runway’s Gen-4.5 and Aleph 2.0 to dedicated inference · 1 src
- AI boosts automotive defect detection by 90% per McKinsey study · 1 src
- Anthropic invests $100M to train 10,000 deployed AI engineers by 2027 · 2 src
Comments
via GitHub Discussions