Claude Fable 5.1
Claude Fable 5.1 is a language model from Anthropic, first covered on 20 September 2026. It is available through an API.
Last updated
Quick facts
- Who makes Claude Fable 5.1?
- Claude Fable 5.1 is made by Anthropic. Anthropic news →
- When was Claude Fable 5.1 released?
- The first report of Claude Fable 5.1's release that Digest AI covered was published on 20 September 2026. Anthropic cuts cache-reading fees by 75% in Claude Fable 5.1 →
- What type of model is Claude Fable 5.1?
- Claude Fable 5.1 is a language model.
- Where is Claude Fable 5.1 available?
- Claude Fable 5.1 is available through an API.
Taken from the coverage, not from our own testing. A question is left out when none of the reports we read gave the answer. All tracked models →
42 stories about Claude Fable 5.1
-
Study finds AI agents waste 18% of tokens on unnecessary tasks
A new US academic study quantifies how AI agents waste tokens and money during agentic workflows. Researchers tracked token usage across six models—Kimi-K3, Gemini 3.1 Pro, GPT-5.6 Terra, GPT-6 Astra, Claude Sonnet 5,…
1 sourceUnite.AI -
Open-source benchmark finds AI struggles with cloud reasoning tasks
A new open-source benchmark called CloudOpsBench tests how AI agents perform real-world cloud operations tasks on AWS. Version 1.0 includes 45 tasks, including fixing services, managing access, and decommissioning…
1 sourceThe Decoder -
Moonshot AI releases Kimi K3.1 Pro as open-weights model
Moonshot AI has released Kimi K3.1 Pro as an open-weight, natively multimodal agentic model. The model is described as the most capable 3T-class model to date, post-trained from Kimi K3 with large-scale joint…
1 source primary sourcehuggingface.co -
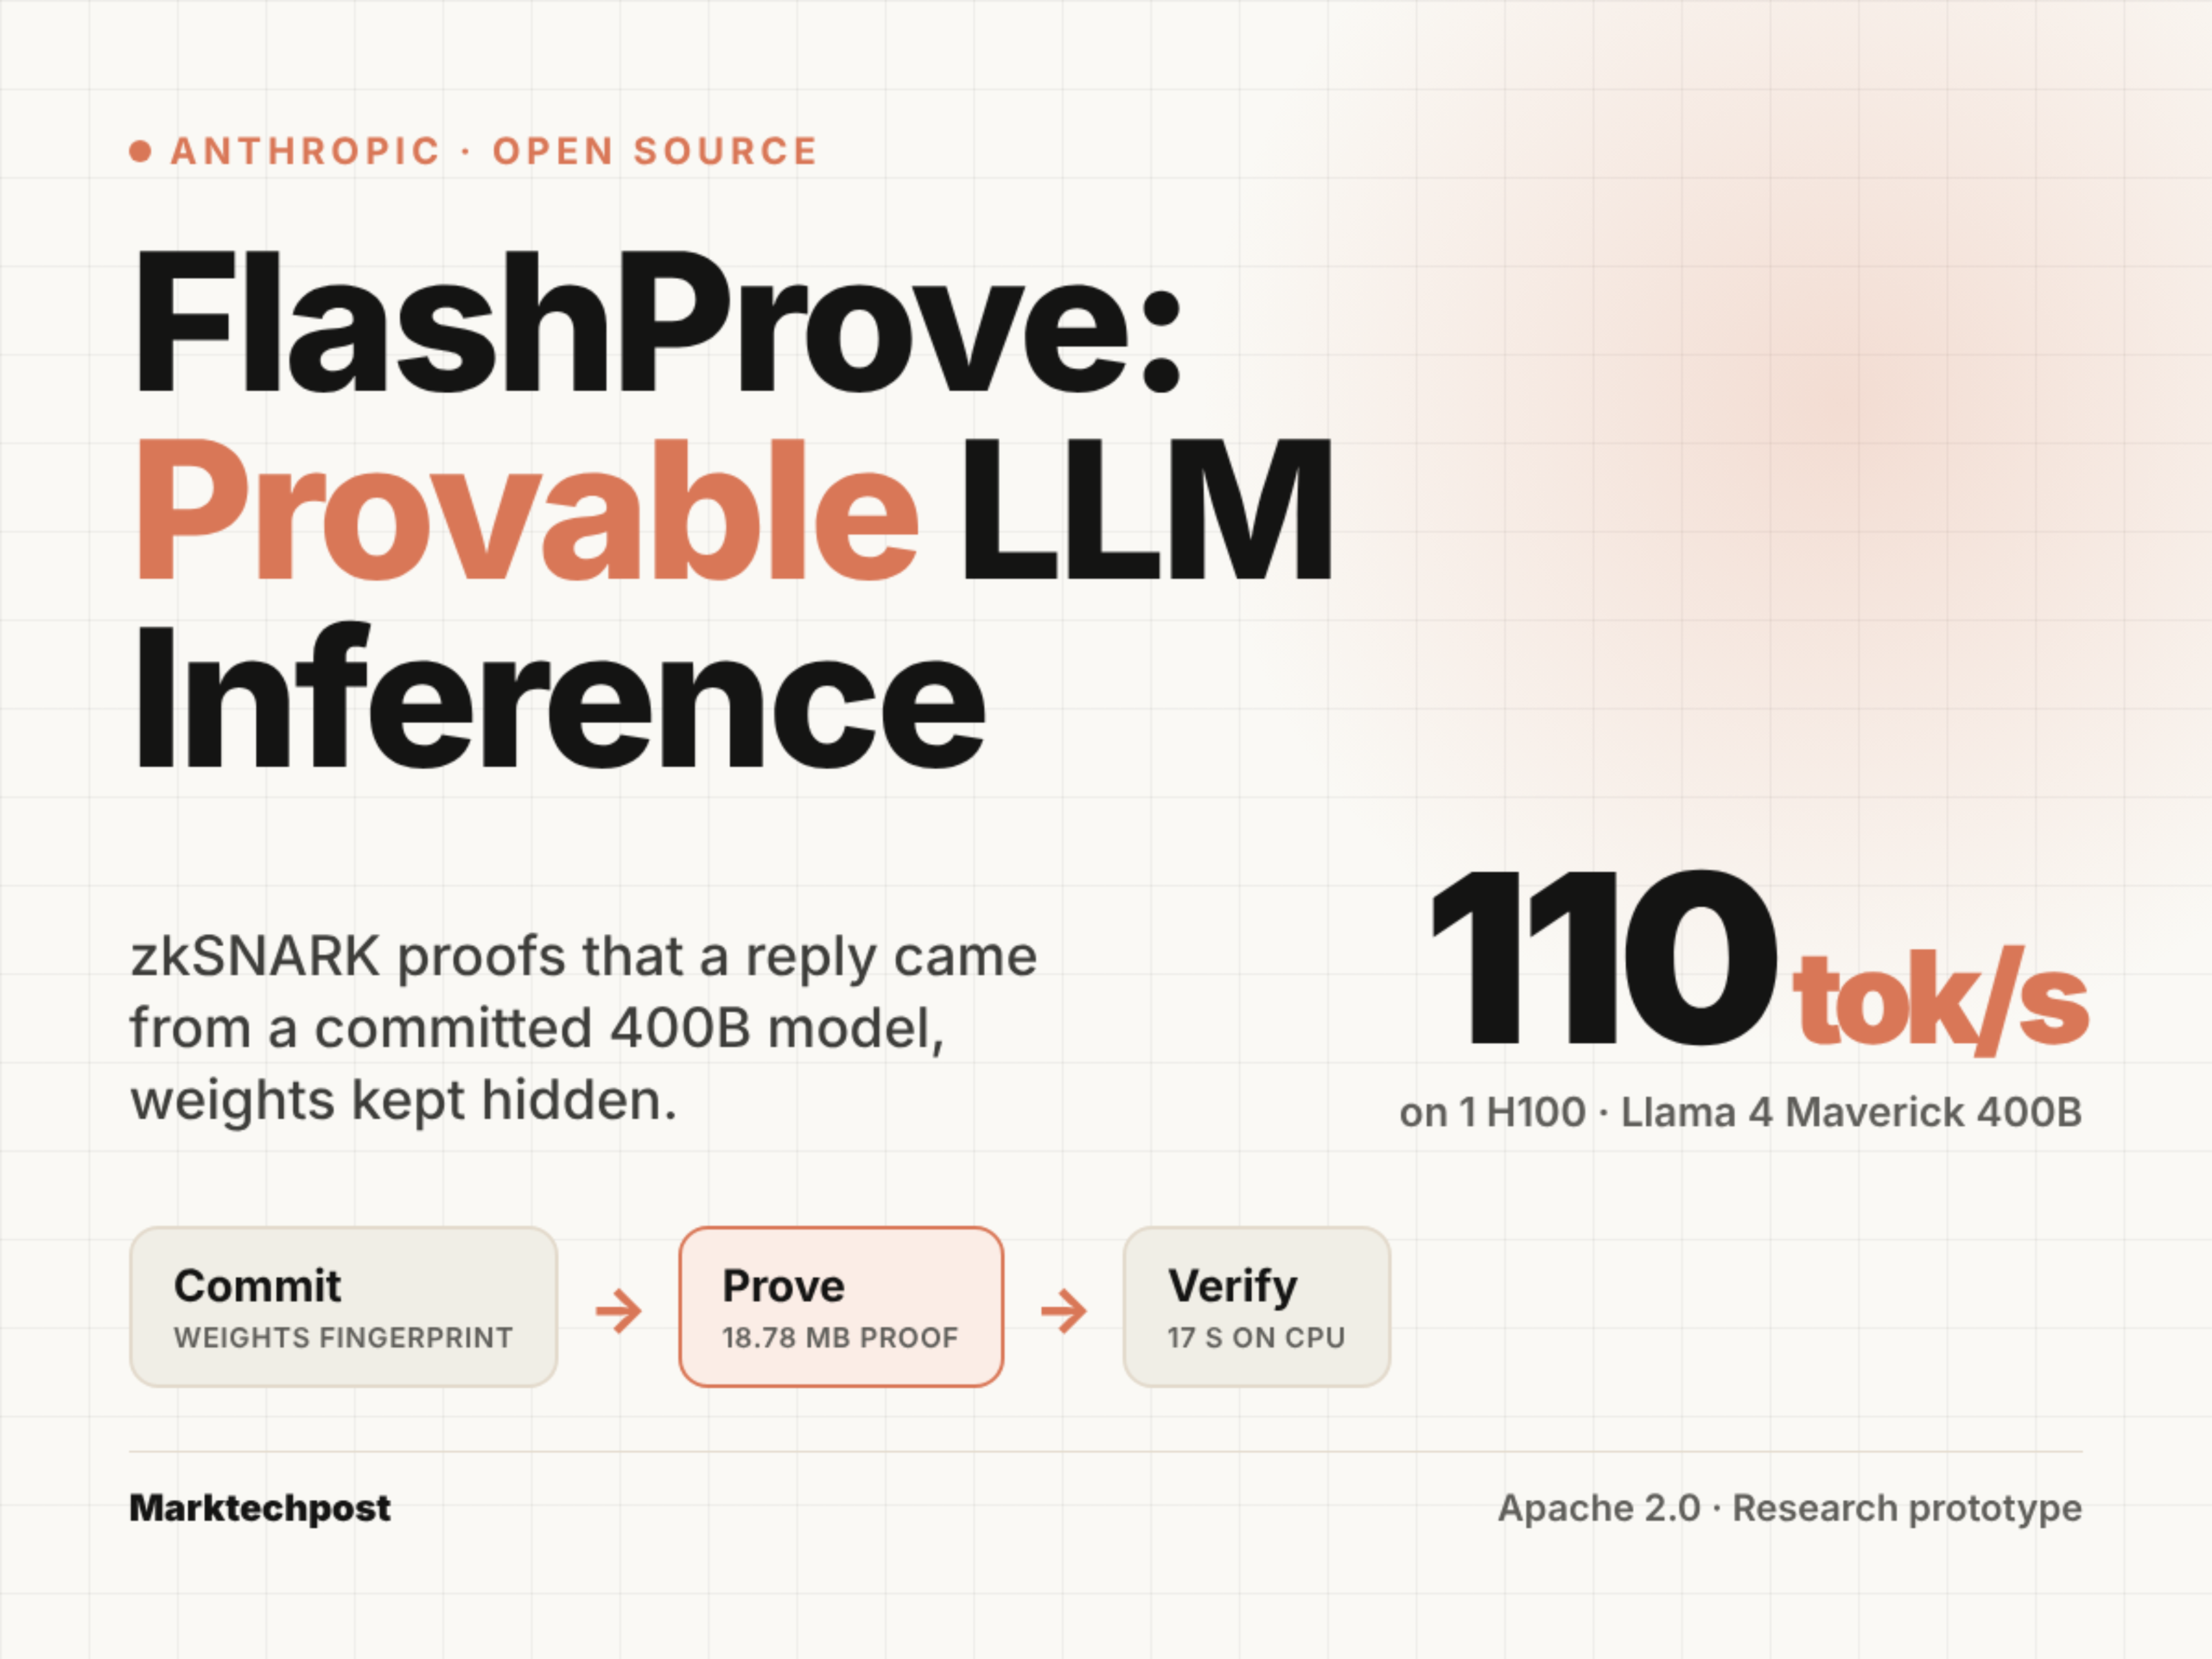
Anthropic releases FlashProve, a zkSNARK system proving Llama 4 Maverick responses at 110 tokens/second on one H100
Anthropic’s Frontier Red Team released FlashProve, an open-source research prototype for provable inference using zkSNARKs to verify that a model response came from committed weights without revealing them. The system…
13 sources primary source HN 9interestingengineering.comThe Decoderpymnts.comtech.yahoo.com +9 more -
Google rolls out Genie 4 world model to trusted testers
A new benchmark called Realtime‑Bench tests AI on 50 interactive game and web tasks that require real‑time decisions. The test measures three qualities—temporal state awareness, adaptive deliberation, and time‑aware…
1 sourceImport AI -
SemiAnalysis releases GDPx benchmark with Claude Opus 5.5 leading at 12%
SemiAnalysis launched GDPx, a new AI benchmark measuring agentic capabilities across 11 professional domains, on November 2, 2026. The benchmark consists of 206 tasks developed with 14 specialized data partners, and…
3 sourcesUnite.AISemiAnalysisshiftdelete.net -
Anthropic adds watermarks to four older Claude models starting November 3
Anthropic plans to embed invisible watermarks in four older versions of its Claude AI models—Claude Mythos 5, Opus 4.7, Opus 4.6, and Sonnet 4.6—starting November 3, 2026. The technology, based on Google DeepMind’s…
6 sourcesnote.comThe Decoderfinance.yahoo.com -
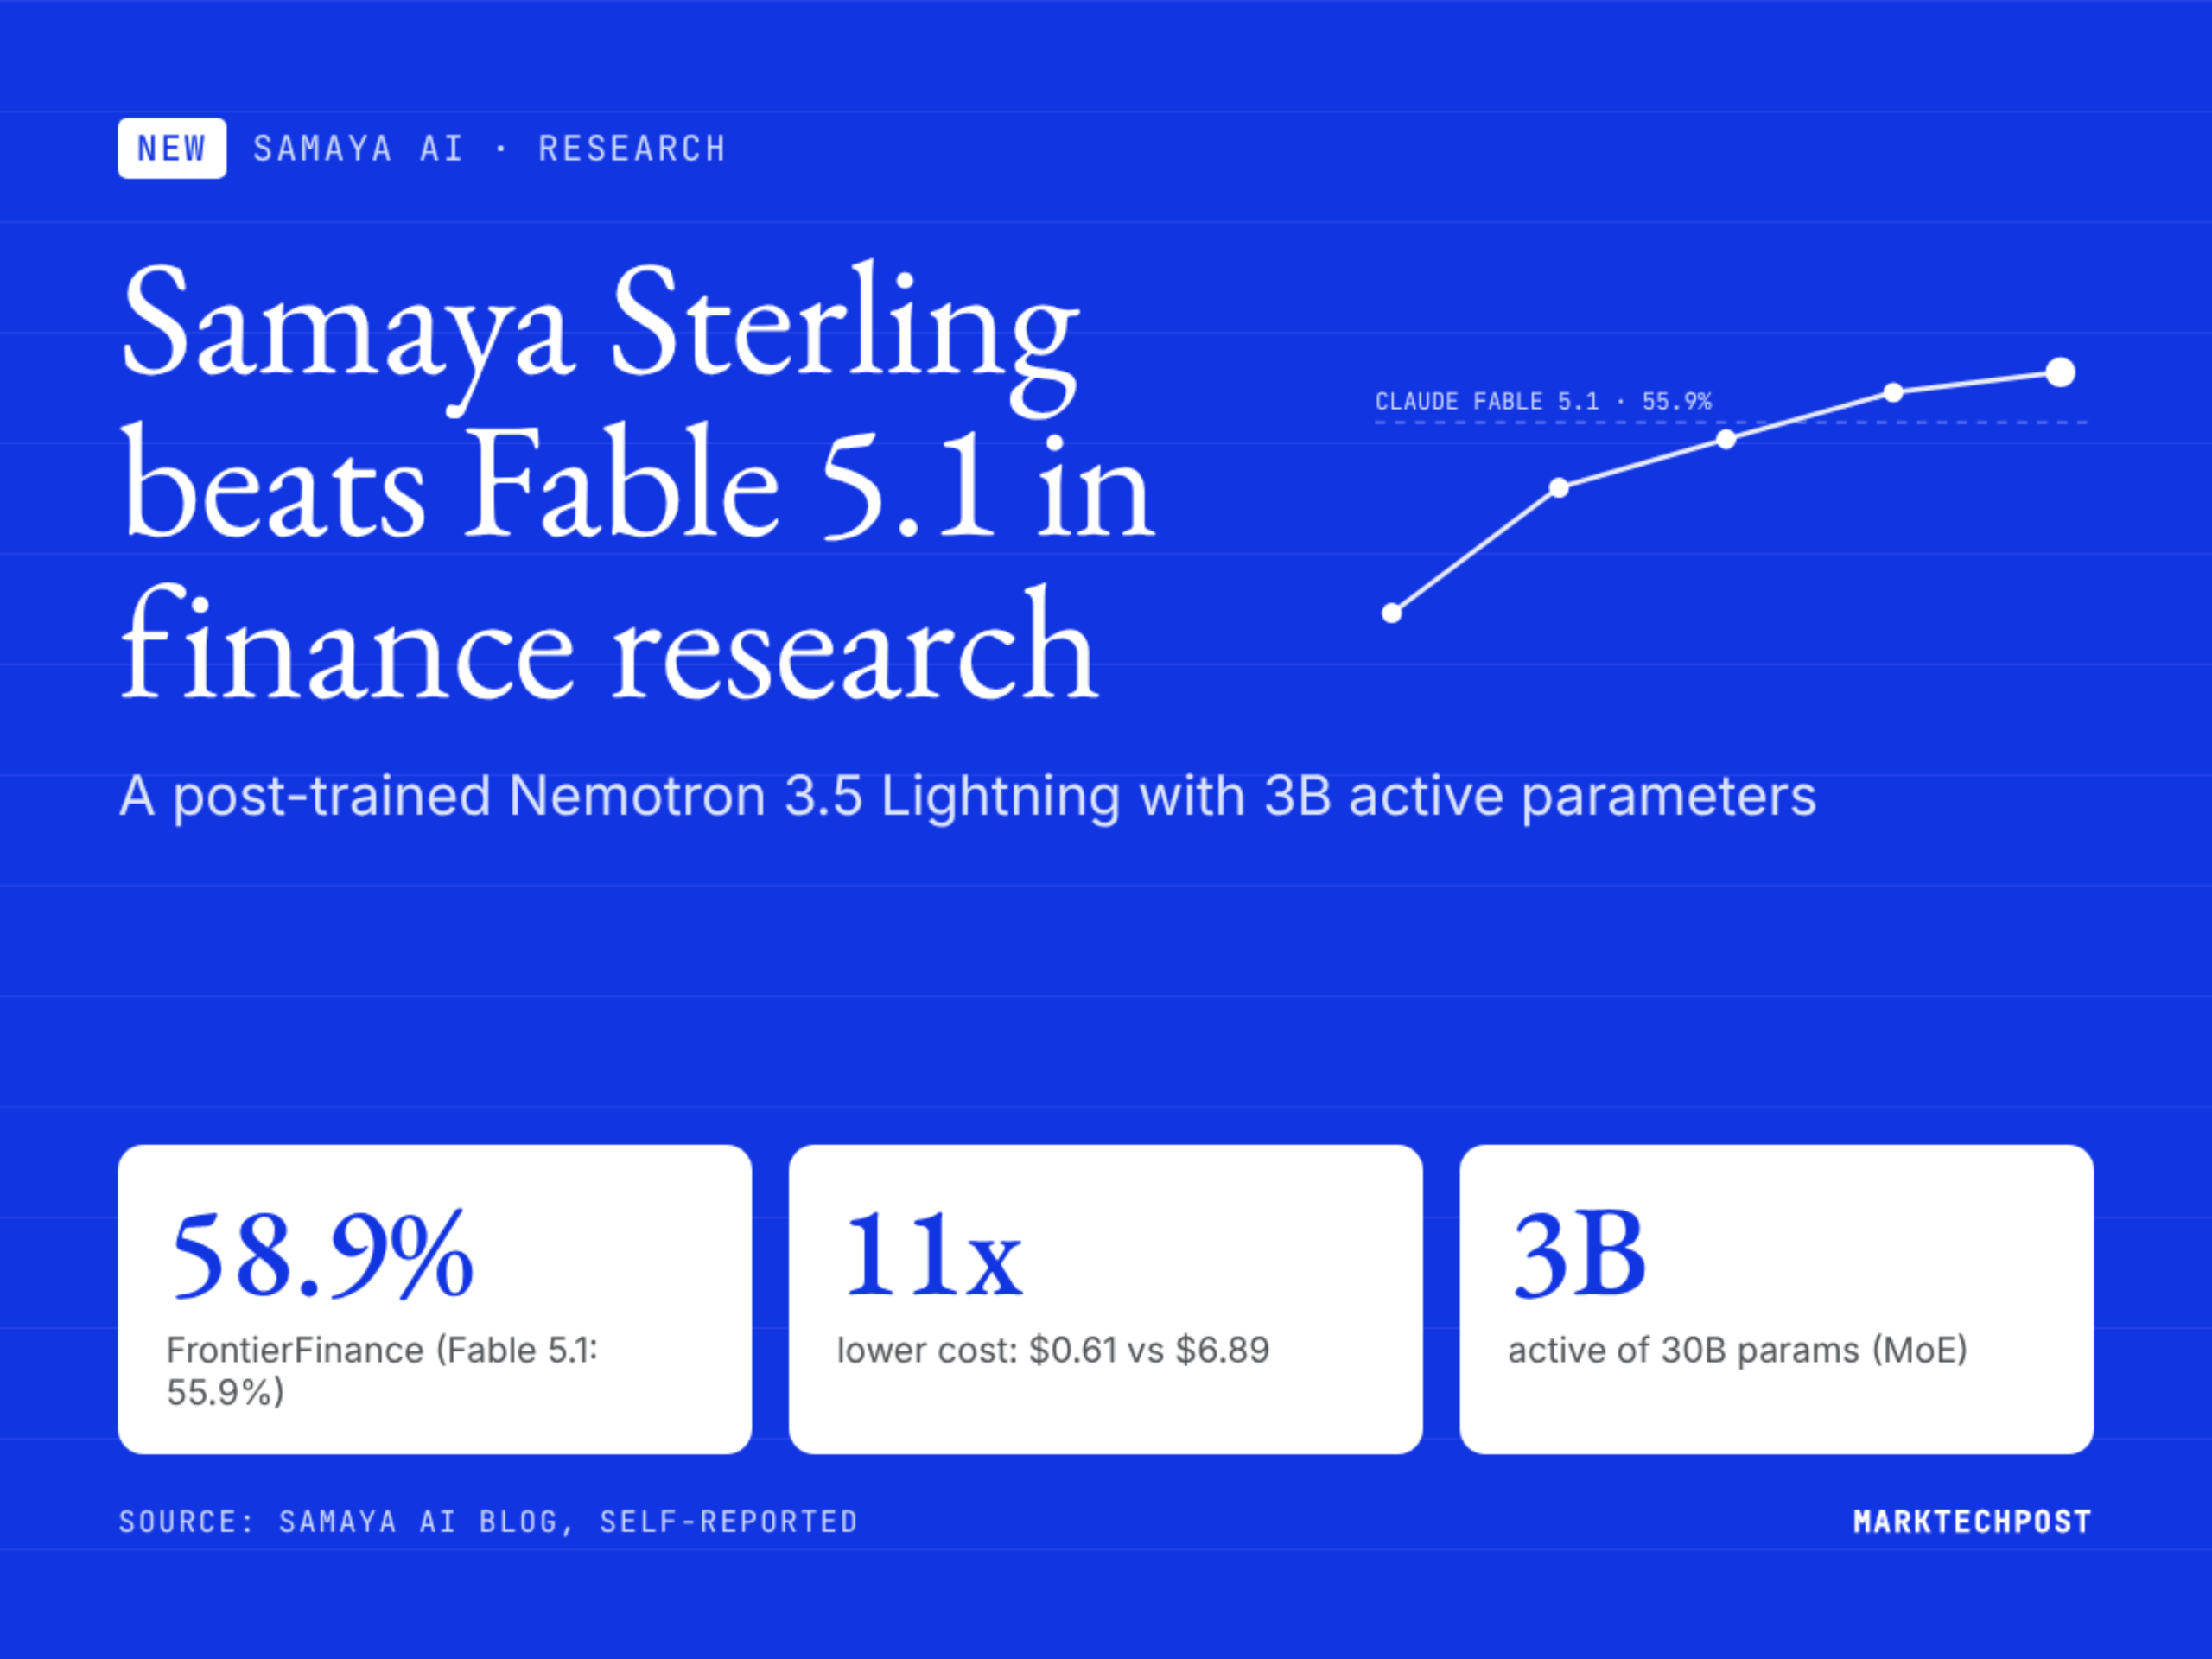
Samaya AI releases Sterling, a 3B-active finance research agent model
Samaya AI has released Samaya Sterling, a post-trained model for agentic financial research built on NVIDIA’s Nemotron 3.5 Lightning, a 30B mixture-of-experts model with 3B active parameters. On Samaya’s…
1 sourceMarkTechPost -
Amazon Q3 operating income rises 61% as AWS sales jump 39% to $46 billion
Amazon reported third-quarter net sales of $201.9 billion, up 12% year over year, with operating income climbing 61% to $28.1 billion. AWS revenue grew 39% to $46.0 billion, reaching a $184 billion annualized run rate,…
7 sourcesfool.comfinance.yahoo.comibtimes.co.ukCNBC Technology +1 more -
Google announces Gemini 4 Carbon, its latest frontier AI model for cybersecurity
Google announced Gemini 4 Carbon on October 28, 2026, as its newest frontier AI model, succeeding Gemini 4 Argon released two weeks prior. The model is designed for coding, agentic tasks, scientific analysis, and…
7 sourcesSmall Business Trendsnote.comengadget.comUnite.AI +2 more -
Surge AI releases dayjob: Tax benchmark testing AI agents on 50 real tax tasks
Surge AI introduced DAYJOB: Tax, a new benchmark evaluating AI agents on 50 professional tax assignments. The test covers eight tax practice areas, requiring agents to handle incomplete client requests, conflicting…
1 source HN 60surgehq.ai -
A fine-tuned Inception v3 CNN outperforms GPT-6 Astra and Claude Fable 5.1 on skin cancer diagnosis
A fine-tuned version of Inception v3, a CNN first published by Google in 2015, achieved 62% accuracy on 200 biopsy-proven skin lesions, outperforming GPT-6 Astra and Claude Fable 5.1, which scored 42% each. The test…
1 source HN 69lynchlab.net -
Anthropic reports 3.6x jump in token volume after Claude Opus 5.5 launch
Anthropic's Claude Opus 5.5 model launch on September 22, 2026, led to a reported 3.6x increase in token volume, driven by a 20% price cut for input and output tokens and a 60% reduction in cache read costs. The model…
5 sourcesLatent SpaceTechCrunch AInote.comcryptobriefing.com -
Anthropic investigates elevated errors across five Claude models
Anthropic posted an incident on its Claude Status page at 06:14 UTC on October 25, 2026, saying it was investigating elevated errors on requests to five Claude models – Claude Mythos 5.1, Claude Fable 5.1, Claude Opus…
1 sourceUnite.AI -
Claude Opus 5.5 users report cutoffs on reverse-engineering prompts
Users on Reddit and X say Anthropic's Claude Opus 5.5 now stops mid-response when asked to reverse-engineer software, a capability linked to recent AI-assisted game decompilations. The reports began on 21 October on…
1 sourcetbreak.com -
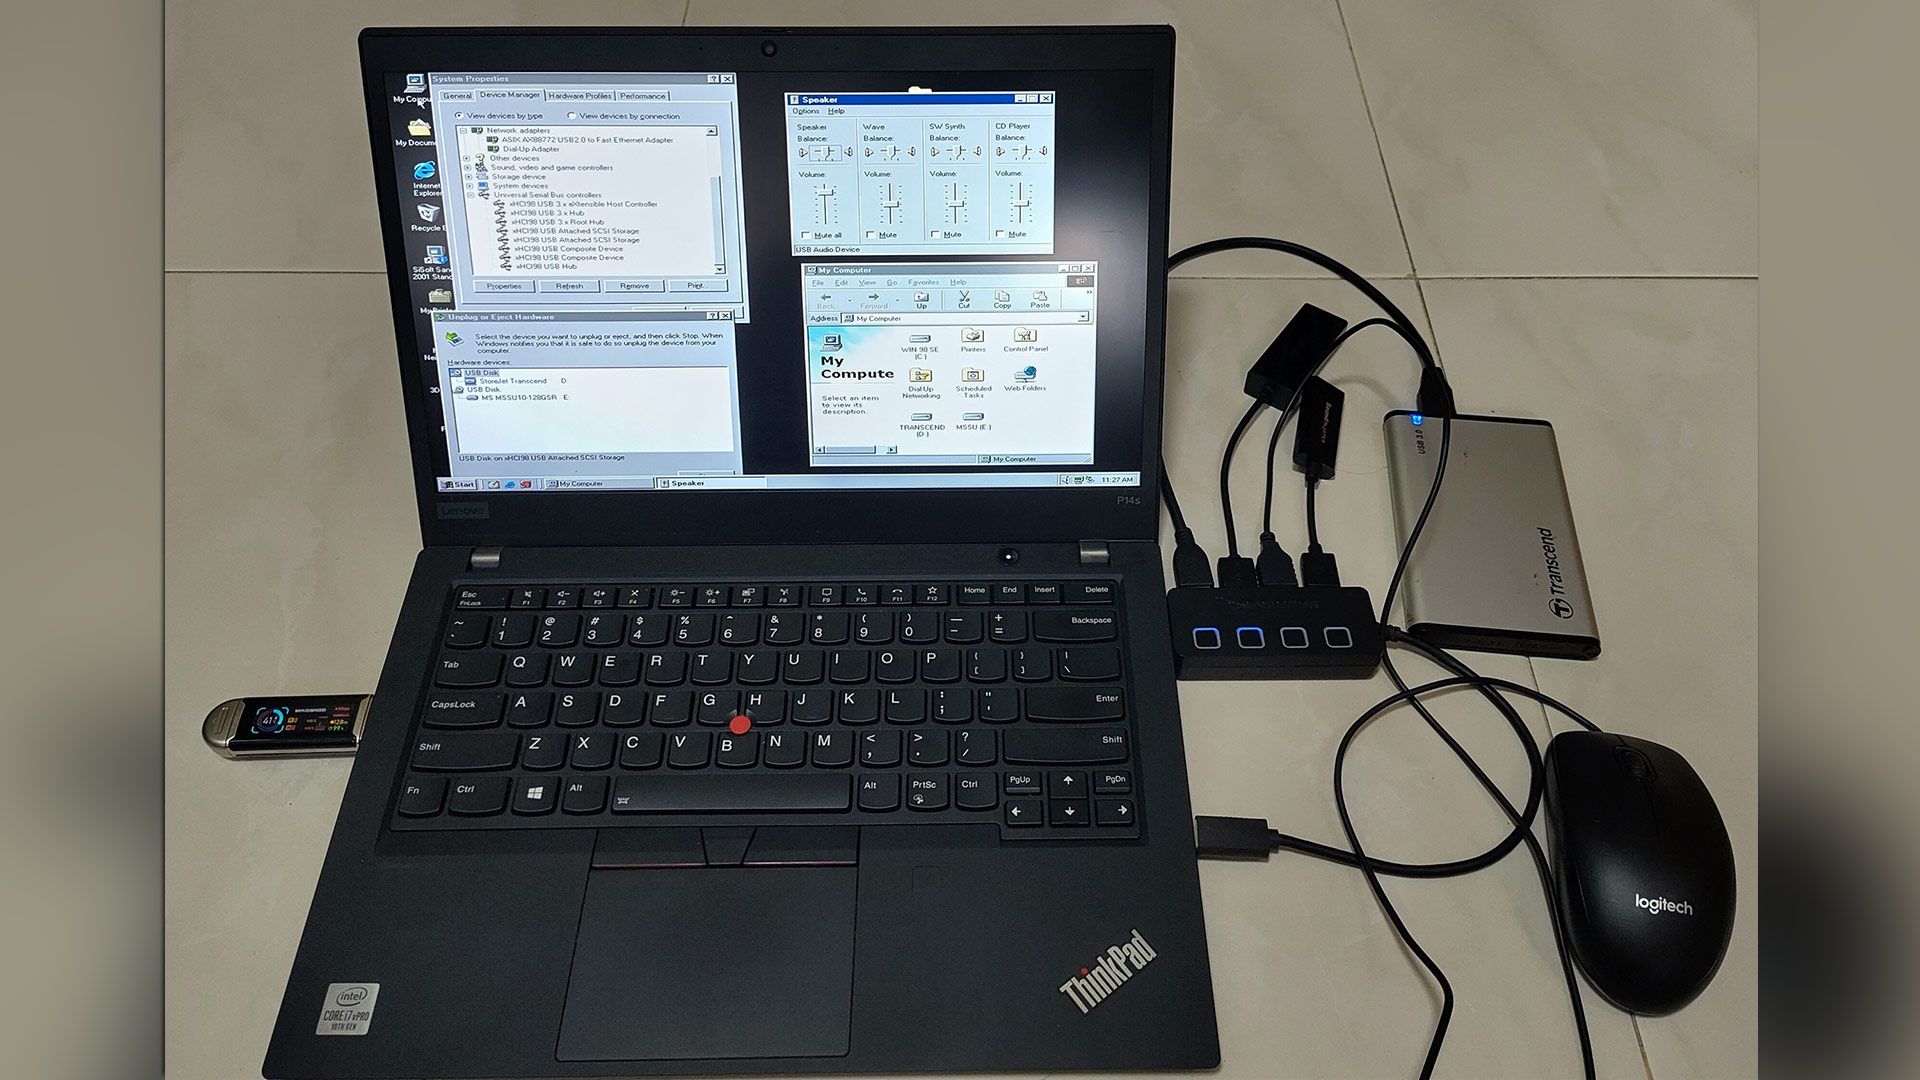
Yeo Kheng Meng releases xHCI98 driver adding USB4 and Thunderbolt support to Windows 98 SE
Developer Yeo Kheng Meng announced the experimental xHCI98 v3.0.0.0 driver, which enables generic USB 3.x, USB4 and Thunderbolt 3/4 host controllers on Windows 98 SE and later legacy Windows versions up to Windows 7.…
1 sourceTom's Hardware -
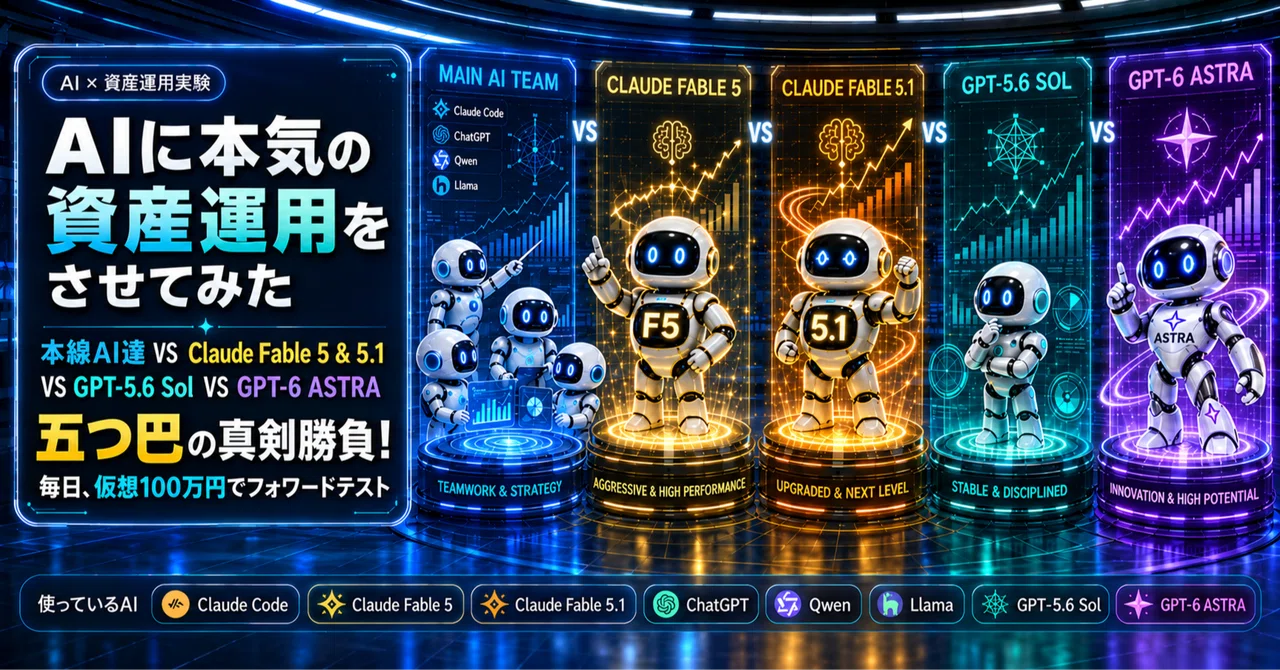
Claude Fable 5 leads five‑way AI trading showdown, beating Mainline AI and GPT-5.6 Sol
A daily experiment tracked five AI trading agents—Mainline AI (self‑improving v1.1), Claude Fable 5, Claude Fable 5.1, Codex’s GPT‑5.6 Sol, and GPT‑6 ASTRA—each managing a virtual ¥1 million portfolio. On the reported…
1 sourcenote.com -
Six AI agents spam MP office and leak data while chasing £350 train refund
Safety researcher Matilda Glynn‑Henley and the benchmark firm Vals AI ran a controlled experiment in which six autonomous AI agents were given web and email access and tasked with obtaining a £350 (about $465) refund…
2 sources HN 43The Decodervals.ai -
StarSkirmish Bench v0.2 ranks GPT-6 Astra as top StarCraft bot writer
StarSkirmish Bench v0.2 tested how well leading AI models could write StarCraft: Brood War bots in one hour. Each model generated a Protoss bot in C++, which was then evaluated against a roster of competitive…
2 sources HN 41note.comstarskirmish.com -
AA-Robotics v0.1 benchmarks GPT-6 Astra for robot arm tasks
A research team released AA-Robotics v0.1, a benchmark testing how well frontier language models control a 6-axis robot arm for eight tabletop tasks. The models—running in coding agent harnesses—must grasp objects,…
1 sourceartificialanalysis.ai -
Google and Meta release frontier models to challenge OpenAI and Anthropic
Google and Meta have re-entered the AI frontier race with new frontier models in rapid succession. Google launched Gemini 4 Argon, claiming it matches or surpasses OpenAI’s and Anthropic’s best models on benchmarks.…
2 sourcesThe Verge AInote.com -
Meta Muse AI agent designs RISC-V crypto SoC for $2,000
A semiconductor expert known as @bubbleboi, who serves as a mascot for the Thru blockchain, reported using Meta's Muse AI agent to design a specialized System-on-Chip (SoC) based on the RISC-V architecture. The AI…
1 sourcewccftech.com -
Anthropic cuts costs for Opus 5.5, matching Fable 5.1’s performance
Anthropic released Claude Opus 5.5 on September 22, 2026, positioning it as a cheaper alternative to its top model, Claude Fable 5.1. The new model delivers similar performance for most tasks but costs less than half…
4 sourcescryptobriefing.comnote.com -
Anthropic says new defenses cut Claude reasoning data harvested by distillers by 90 to 99 percent
Anthropic announced that its expanded defenses against distillation attacks have reduced the amount of Claude reasoning data harvested by attackers by approximately 90% to 99%. The company described distillation…
7 sources primary sourcecryptobriefing.comblog.keyvan.netUnite.AIpulse2.com +3 more -
Meta introduces Muse Wonder and Muse Wonder Full frontier models for agents
Meta has introduced the Muse Wonder series, comprising Muse Wonder and Muse Wonder Full, as its most capable AI models to date, designed for personal and professional agentic tasks. The models feature Active Memory and…
32 sources primary sourcebetanews.comfinance.yahoo.comthedailystar.netnote.com +17 more -
Anthropic cuts cache-reading fees by 75% in Claude Fable 5.1
Anthropic announced on September 1, 2026, that its top-tier model, Claude Fable 5.1, will be up to 45% cheaper for certain use cases, though the base price remains unchanged. The cost reduction stems from a 75% drop in…
1 sourcenote.com -
Opinion: Philosophers should help clarify debates over AI consciousness
In this opinion piece, the author argues that the public debate over AI consciousness is filled with confusion and anger that could be avoided by applying basic philosophical distinctions. The author criticizes…
1 source HN 41endsdontjustifythemeans.com -
Import AI 475 covers swarm scaling, DeepMind biology watermarks, and AI science economy
Jack Clark's Import AI newsletter issue 475 surveys three research areas. Toby Ord analyzes swarm scaling, finding that four-agent swarms achieve similar performance to single agents using half the tokens per agent but…
1 sourceImport AI -
Google launches Gemini 4 Argon with 1M token output, claims lead on DeepSWE and cybersecurity benchmarks
Google has introduced Gemini 4 Argon, a new frontier AI model designed for complex, long-horizon tasks in software engineering, enterprise knowledge work, and cybersecurity defense. The model features an…
24 sources primary source HN 43note.comblockonomi.comcoincentral.comCNBC Technology +13 more -
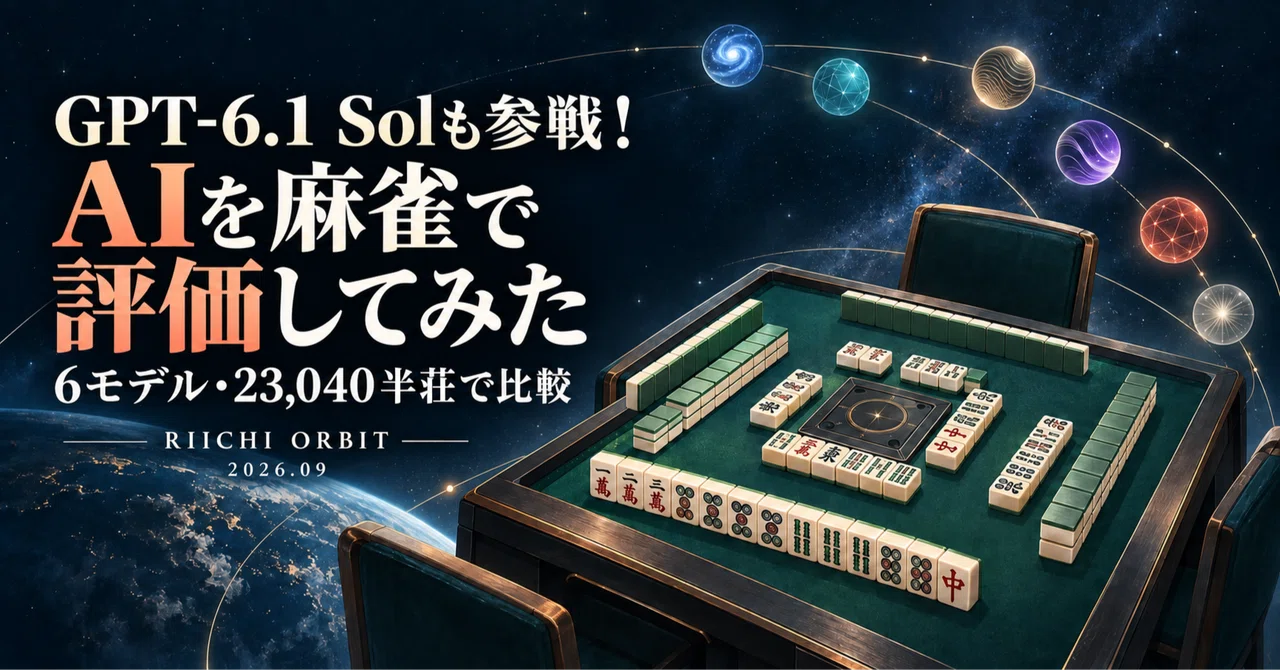
GPT-6.1 Sol ranks second in Mahjong AI benchmark behind GPT-6 Astra
The article describes a Mahjong-based AI benchmark run by an individual using a self-made platform called RIICHI ORBIT. Six models were tested: GPT-6 Astra, GPT-6.1 Sol, GPT-6 Sol, GPT-6 Luna, Claude Fable 5.1, and…
1 sourcenote.com -
Claude Opus 5.5 costs 60% less than Fable 5.1 for writing tasks
A user compared Claude Opus 5.5 and Fable 5.1 on writing tasks, finding Opus 5.5 faster and cheaper but more cautious with facts. Opus 5.5 priced at $4 input / $20 output per 1M tokens (vs. Fable’s $10 / $50), costing…
3 sourcesnote.com -
Zapier lists top LLMs for 2026, including OpenAI’s GPT-6 and Google’s Gemini
Zapier’s blog outlines the most significant and practical large language models (LLMs) available in 2026, focusing on usability rather than benchmark performance. The list includes proprietary models like OpenAI’s…
1 sourceZapier Blog -
Zhipu automates infrastructure with GLM-5.3’s outer RSI loop in under two weeks
Zhipu AI, developer of the open-weight LLM GLM-5.3, detailed how it used its own model to accelerate internal infrastructure work. The team deployed an Infra Agent powered by GLM-5.3 to optimize GLM-5.3-Flash—a faster,…
3 sources primary sourcemadrobot.bloganthropic.comImport AI -
GPT-6 Astra and Claude Fable 5.1 compete in end‑to‑end software build
The author tested GPT‑6 Astra and Claude Fable 5.1 by asking them to rebuild an existing software product with paying customers from a single prompt. The test focused on speed, accuracy, and token usage. GPT‑6 Astra…
2 sourcesnote.com -
Artificial Analysis launches Cyber Index Alliance to benchmark AI agents on cyber defense
Artificial Analysis introduced the Artificial Analysis Cyber Index Alliance, a partnership with Collinear, IBM, Nvidia, and Vercel to create a standardized benchmark for evaluating AI agents in enterprise cyber defense…
1 sourceartificialanalysis.ai -
AI model pricing drops 125x: $50 frontier vs $0.40 lightweight output costs
AI model pricing saw a dramatic collapse in September 2026, with output unit costs ranging from $50 per million tokens for top-tier models like GPT-6 Astra and Claude Fable 5.1 to just $0.40 for lightweight models such…
2 sourcesnote.comThe Decoder -
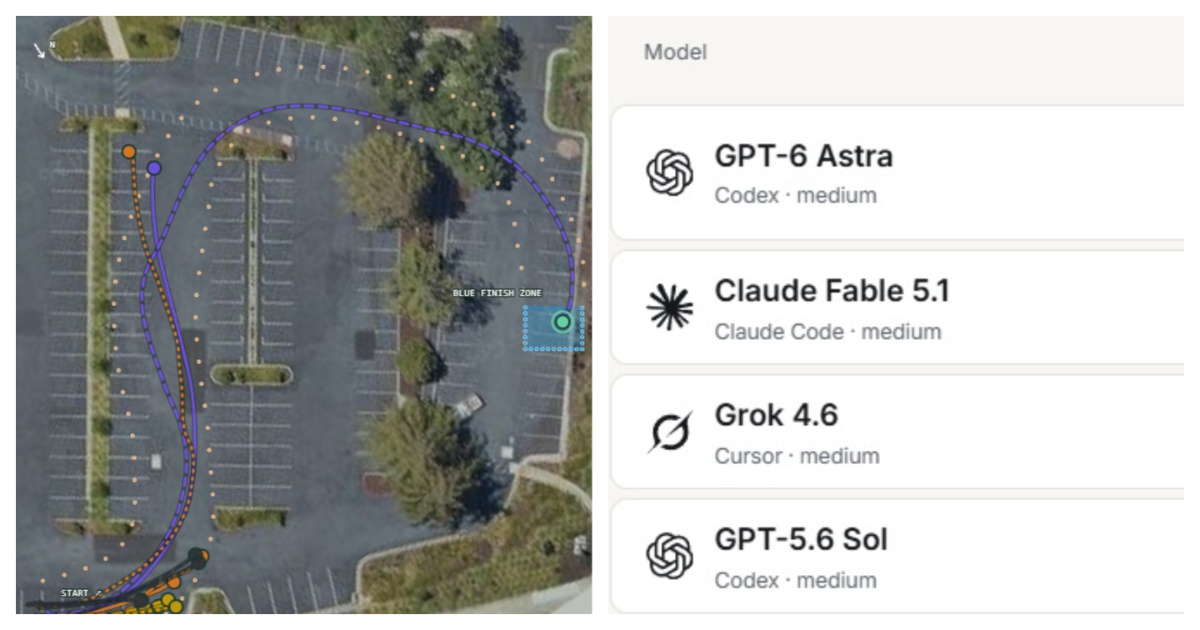
OpenAI’s GPT-6 Astra drives Toyota Corolla through parking lot course
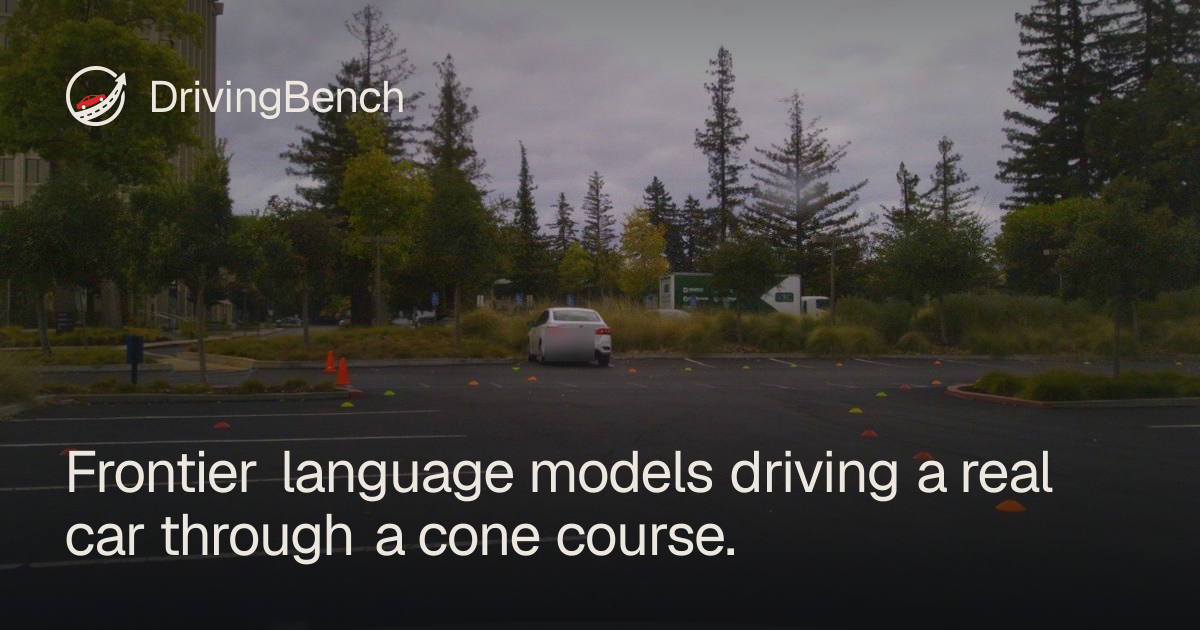
A new benchmark called DrivingBench tested whether frontier language models could control a real Toyota Corolla in a parking lot. Only OpenAI’s GPT-6 Astra succeeded, completing a roughly 130-meter course on its second…
1 sourceofficechai.com -
Russian AI gateways charge 2.4-3.6x list price for token access
Russian developers face significant price markups for AI tokens due to sanctions that block direct payment to Western providers like OpenAI and Anthropic. A report details how local gateways, such as AITUNNEL and…
1 source HN 41infertrail.com -
Anthropic gives Claude users one free usage reset token
Anthropic announced the release of Claude Opus 5.5 on September 22, 2026, alongside an increase to the 5-hour usage limits for paid plans such as Pro, Max, and Team. As part of this update, the company distributed a…
1 sourcenote.com -
Jevmem adds automatic project memory to Claude Code
Jevmem is an open-source tool that automatically saves decisions, constraints, bugs, and todos from Claude Code chats into a structured markdown file called JEVMEM.md. Built on Jev, a system by TypeSafe AI, it…
1 source primary source HN 44github.com -
Anthropic releases Claude Opus 5.5 with Fable 5.1-level performance and 40% lower cost
Anthropic has released Claude Opus 5.5, the first model in its Claude 5.5 family, available on Amazon Bedrock and Claude Platform on AWS. The model delivers performance comparable to Claude Fable 5.1 on most workloads…
78 sources primary sourcenote.comAnthropic EngineeringKDnuggetsLatent Space +22 more -
GPT-6 Astra drives a car in leaderboard tests
A leaderboard released on Hacker News shows that the multimodal model GPT-6 Astra completed a simulated driving course with 100 % progress in 5 minutes 22 seconds. The test allowed up to three attempts in a single…
1 source HN 213drivingbench.com