OpenAI cuts Git push times by 80% with Pando backend
OpenAI introduced Pando, a custom Git backend that reduces median push latency by nearly 80% in its monorepo. The system, built in Rust and deployed in 10 weeks, handles nearly 1 petabyte of Git data daily—peaking at over 57 TB in an hour—using commodity hardware. OpenAI reports thousands of concurrent pushes without performance degradation, citing internal tests. The backend replaces…
Key points
- OpenAI’s Pando backend slashes median Git push latency by ~80%, handling 1PB of data daily on standard cloud VMs
- Causal consistency per branch and reusable packfiles cut contention and reduce fetch times to O(log Δ)
- Commit volume in OpenAI’s monorepo rose 1,378% YoY in Q3 2026, prompting the backend’s development
Model page: GPT-6 Astra →
The story so far
5 episodes →- OpenAI cuts Git push times by 80% with Pando backendthis story
OpenAI Introduces Pando: A Git Backend That Cuts Median Push Latency ~80%
MarkTechPost · 3 November 2026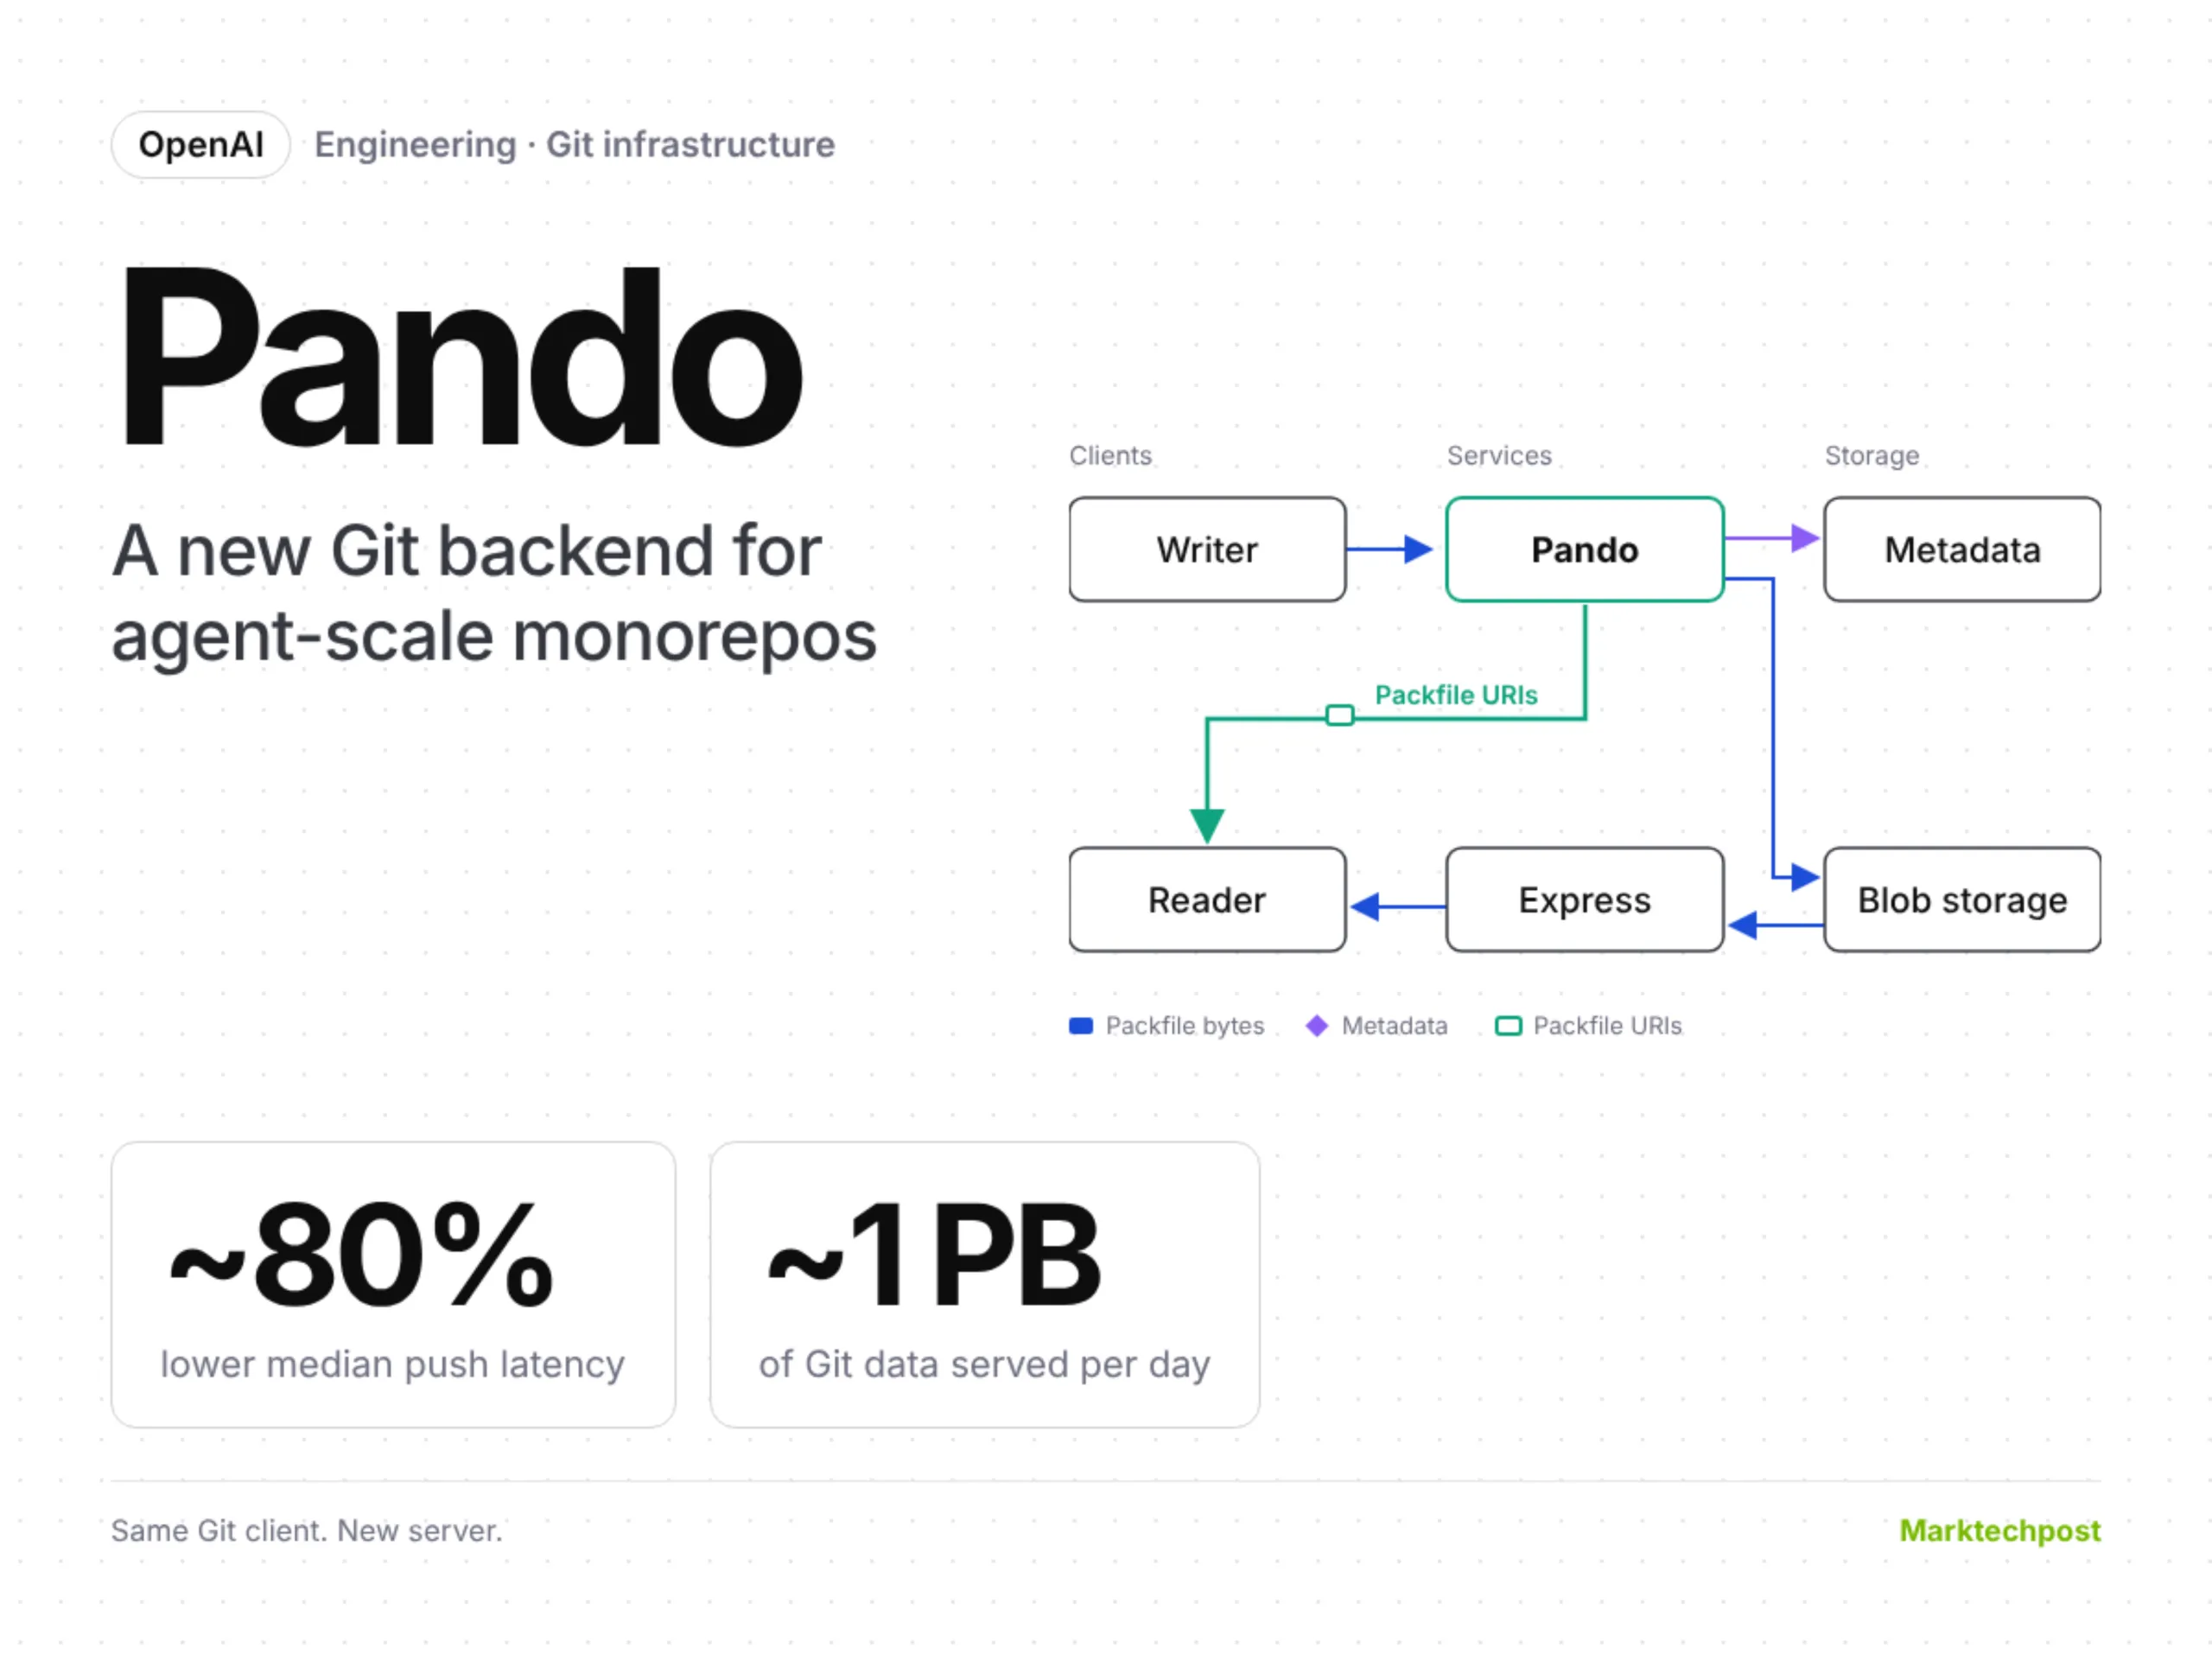
Loading the full article…
This text was published by MarkTechPost and written by Michal Sutter. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Enterprise & Industry
All →- NVIDIA expands physical and agentic AI services for cities worldwide · 2 src
- Windward buys Azimut.ai for visual vessel tracking at ports · 1 src
- Merck and Google Cloud announce $1B agentic AI partnership for pharma · 1 src
- Larridin raises $30M Series A to track AI spending and workforce productivity · 2 src
- CrowdStrike and Dell launch integrated AI security for Dell AI Factory with NVIDIA · 1 src
Comments
via GitHub Discussions