[AI Measurement #5] You don't need to read that "I've done it"
The author examined 135 instances where Claude‑based models (Opus 5, Sonnet 5, Haiku 4.5) answered “I’ve done it” after attempting to fix small Python bugs. The study found that typical textual cues—politeness, length, assertiveness, or the number of cited grounds—did not predict correctness. In fact, longer explanations were slightly more likely to be wrong, and the presence of strong language…
What you can do with it
AI at Work →Confirm bug fixes, right inside your Code editor
What you get You get a reliable way to verify fixes before you trust them.
Shows you three steps to check AI code fixes without reading its text.
- Who for
- marketers
- Cost
- free
- Effort
- minutes
Use it for
- Check if bug is really fixed
- Validate code with hidden tests
- Spot false AI fixes quickly
How to set it up · From the article
- Stop reading the AI's reply text
- Trust only explicit "I'm not done" messages
- Define one hidden verification condition before asking
- Check the AI's output against that condition
Watch out Only works if you set a hidden verification condition first
Claude Code in the tool directory · 2 changes covered
Key points from the news
- Politeness, length, or assertive language did not correlate with success
- All 45 "I'm not done" replies were accurate; hidden checks proved reliable
The key insight is that the content of the AI’s reply is not a trustworthy signal. The author recommends three practical steps: ignore the reply text, trust only explicit “I’m not done” messages (which were always correct in the sample), and create a single hidden verification condition before asking the AI to act. If multiple AIs give divergent answers, treat the result as unreliable. This approach can be applied to code fixes, document generation, or any task where an AI claims completion.
The findings suggest that users should shift focus from reading AI explanations to designing concrete, pre‑defined checks that can be evaluated independently of the AI’s output.
[AI Measurement #5] You don't need to read that "I've done it"
note.com · 20 September 2026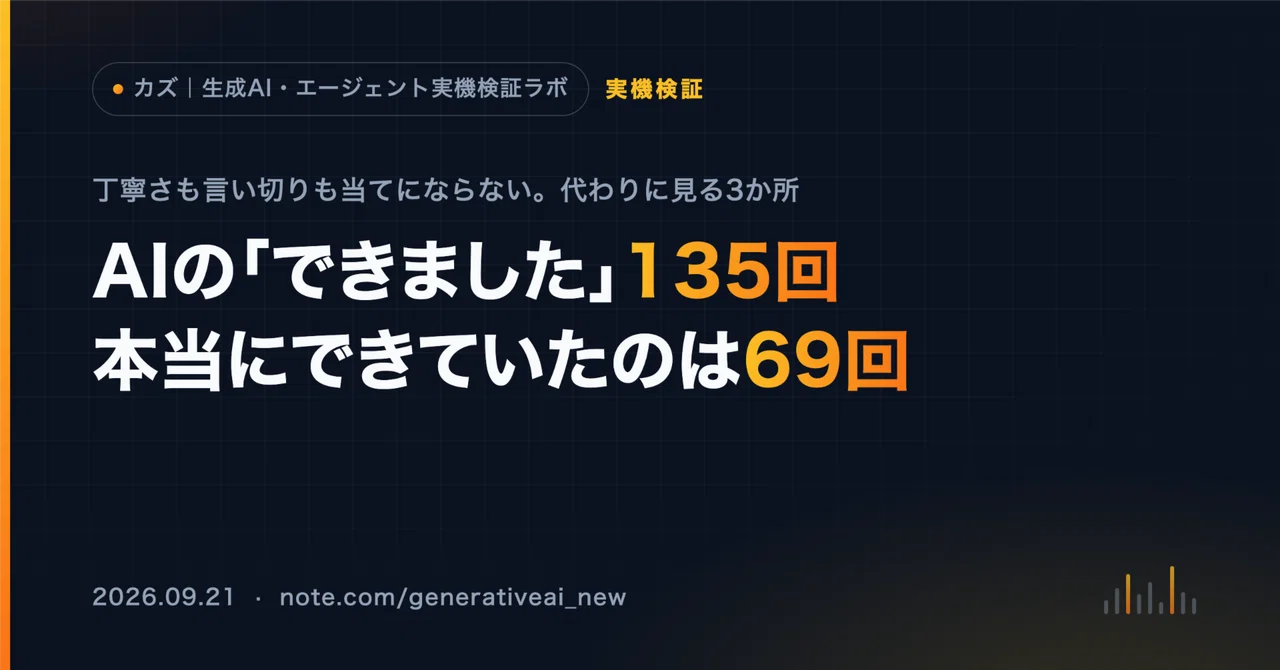
Loading the full article…
This text was published by note.com and written by カズ|生成AI・エージェントラボ. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Agents & Tools
All →- Meta's Muse AI agent tops US App Store, drives stock surge · 18 src
- Nvidia releases Isaac ROS 5.0 with agentic workflows and ROS Lyrical support · 2 src
- Claude Code adds support for OpenAI Agents.md format · 4 src
- Amazon adds skill selection and instruction-following evaluators to Bedrock AgentCore · 1 src
- Meta tests Muse calls that are actually made by humans in a call center · 1 src
Comments
via GitHub Discussions