Kyutai releases Voice of Reason speech-to-speech model for spoken math
Kyutai announced two open‑weight speech‑to‑speech models, called Voice of Reason, built on the GLM‑4‑Voice‑9B foundation. The models solve math problems directly from spoken input, removing the need for a transcription step or a separate text LLM. On the spoken GSM8K benchmark the direct model reaches 70.3% accuracy, and with a reasoning‑chunk variant (Stitch) it climbs to 77.1%, up from the…
Key points
- Voice of Reason raises spoken GSM8K accuracy from 27.3% to 77.1% using reinforcement learning.
- Training used 150,616 math problems, 16 H100 GPUs, and 1,500 RL updates.
- Both 9B checkpoints are open‑weight, run on a single H100, but not hosted on Hugging Face inference.
Training used 150,616 math problems from Orca‑Math, which were rewritten by Qwen3‑235B and voiced by Kyutai’s DSM TTS system. Supervised fine‑tuning lifted accuracy to 61.7%, and a second reinforcement‑learning stage—sampling four replies per question and scoring them with a Qwen3‑235B‑A22B‑2507 judge—added the remaining gains. The RL run involved 1,500 updates on 16 H100 GPUs. Both 9B checkpoints run on a single H100 for inference, are released under the GLM‑4‑Voice license, and are currently not hosted by Hugging Face’s inference service.
The work demonstrates that speech‑native models can reason about math without the latency of cascaded pipelines, preserving paralinguistic cues and keeping interaction fluid. Kyutai’s results suggest reinforcement learning can substantially improve reasoning performance in audio‑only systems.
Kyutai Releases Voice of Reason: A Speech-Native Model that Solves Spoken Math with Reinforcement Learning
MarkTechPost · 23 September 2026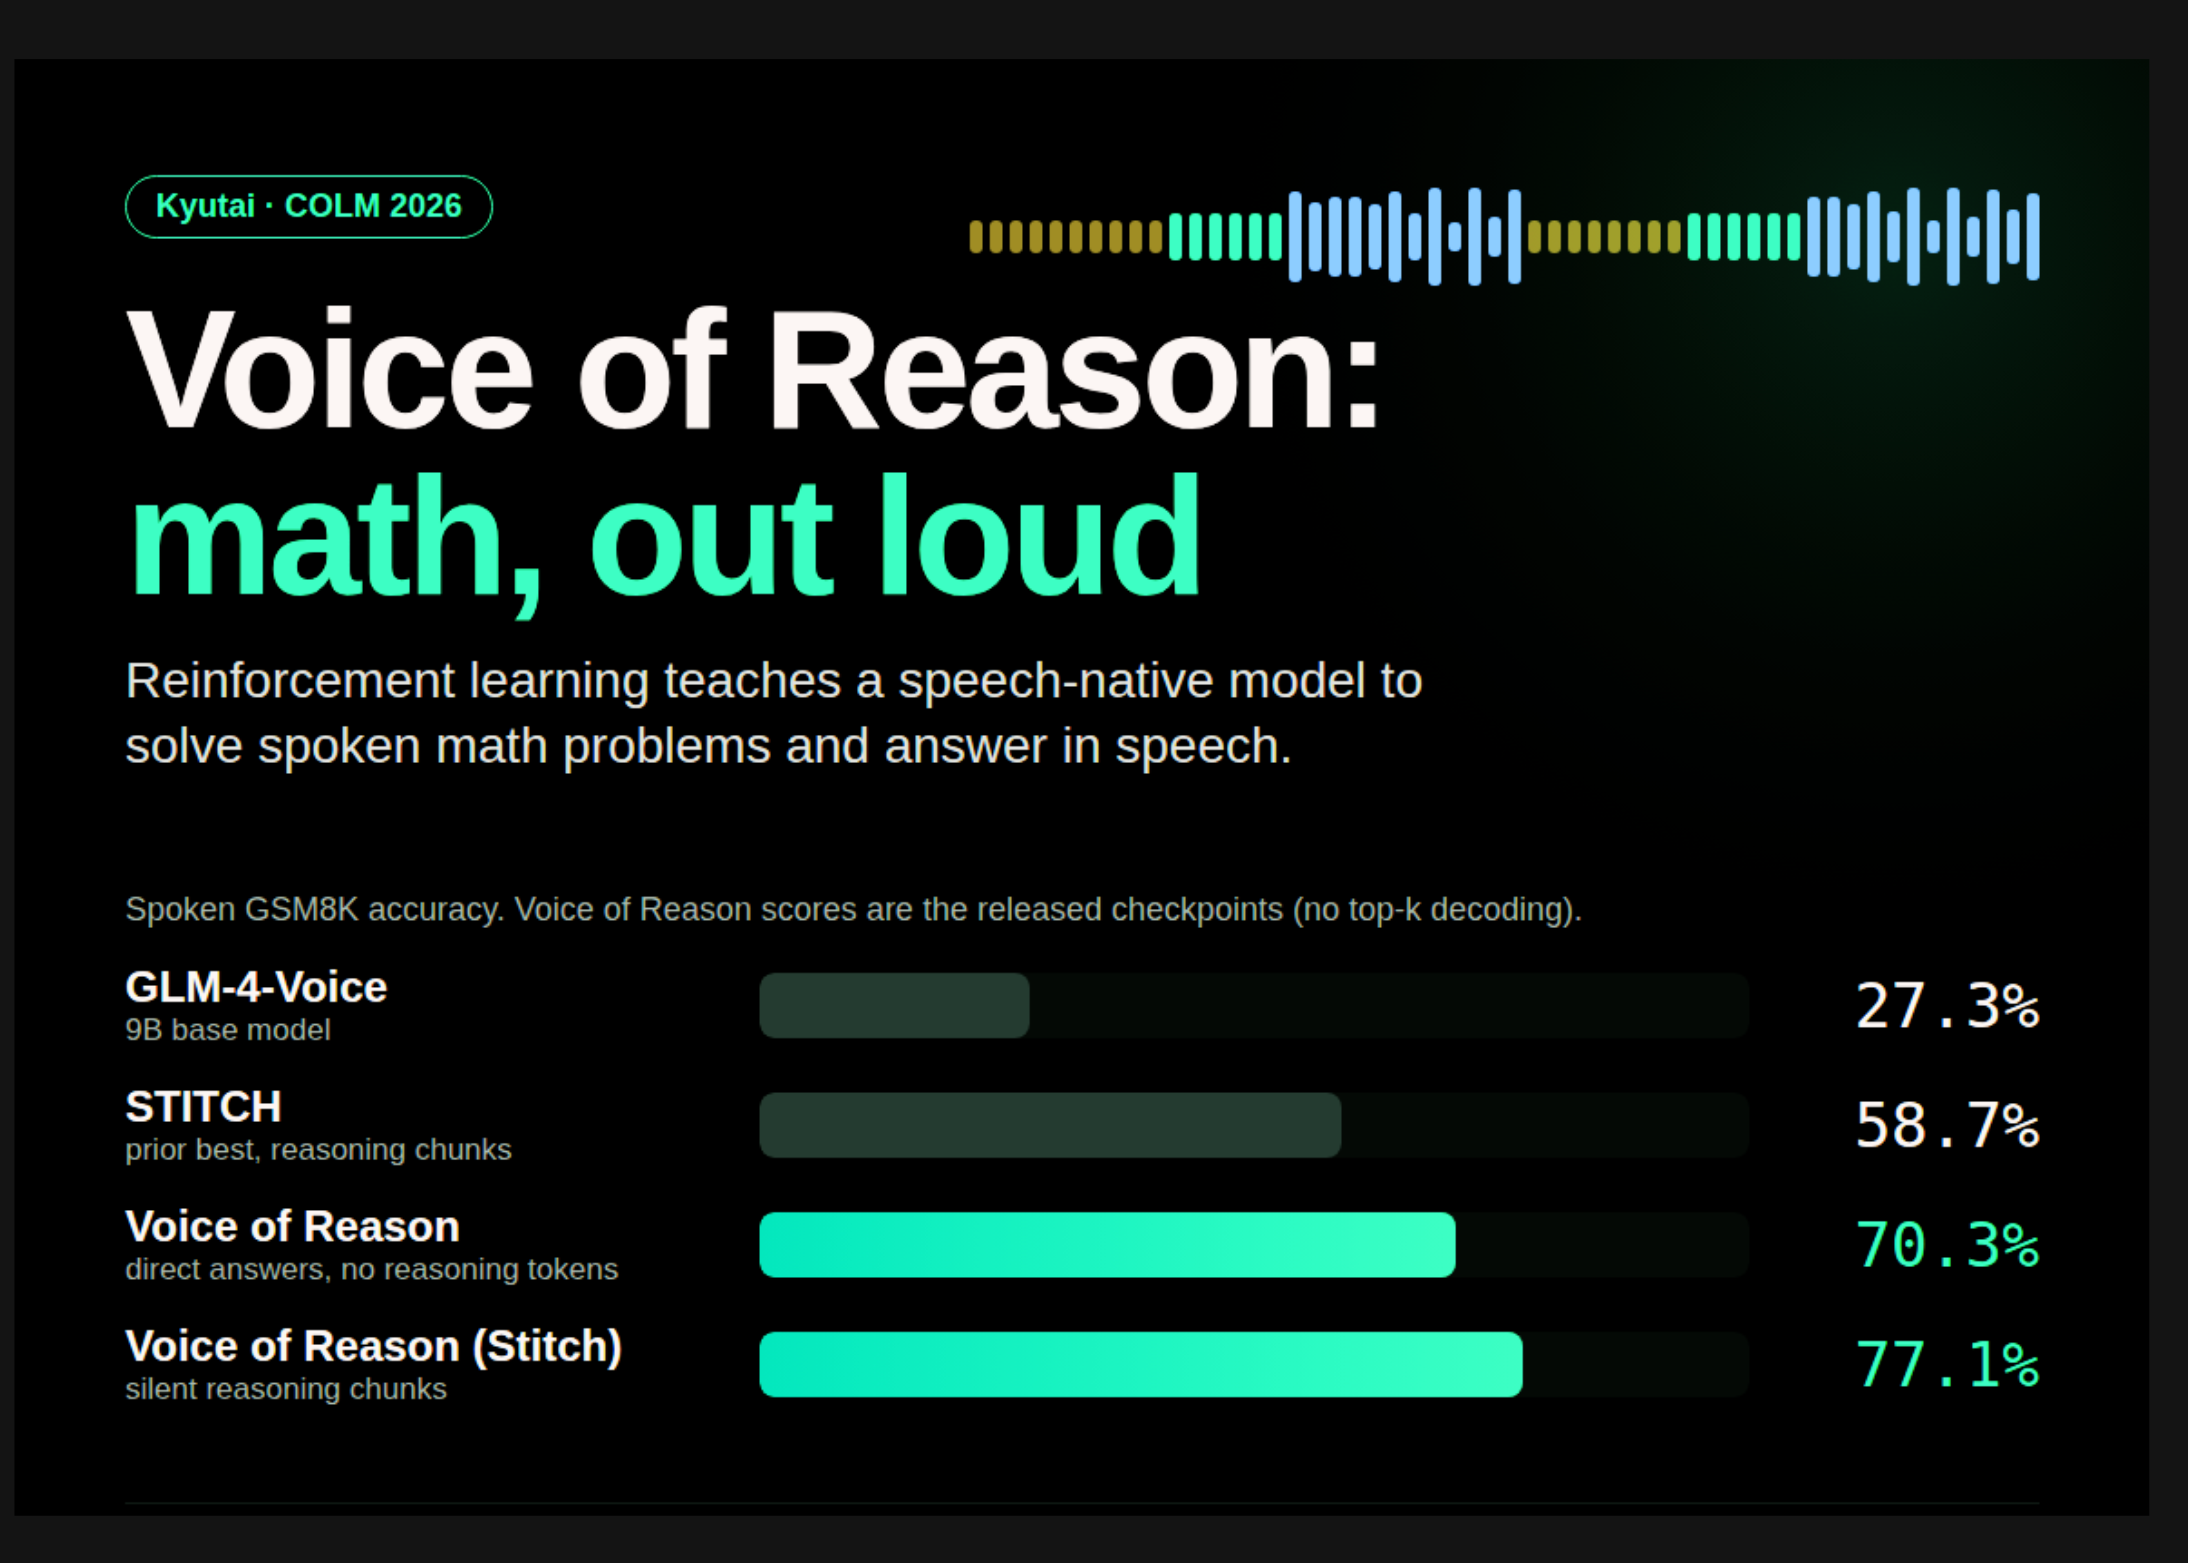
Loading the full article…
This text was published by MarkTechPost and written by Asif Razzaq. It is reproduced here with attribution so you can read it in full; the rights remain with the publisher. Read it at the source ↗
The headline, key points and digest above were generated by Digest AI's editorial model from the linked sources. Automated summaries can contain errors: the sources are the record. Spotted a mistake? Tell us. Published by Martin K., who runs Digest AI and handles corrections.
More in Generative AI & Models
All →- Anthropic releases Claude Opus 5.5 with $4 input and $20 output pricing, claiming 40% lower cost than Opus 5 · 18 src
- Anthropic releases Claude Opus 5.5 and OpenAI counters with cheaper GPT-6 Sol and Luna models · 22 src
- Anthropic releases Claude Opus 5.5 with Fable 5.1-level performance and 40% lower cost · 12 src
- Opinion: OpenAI could copy TypeSafe's Jev classifier and embed it in future models · 2 src
- Researchers unveil Ovis-Embedding, a universal omni-modal embedding family · 1 src
Comments
via GitHub Discussions